AI glossary
Large Language Model (LLM)
A large language model (LLM) is a neural network, almost always a transformer, trained on very large amounts of text to predict the next token given what came before. That single skill lets it answer questions, write, summarise, translate, classify text, and write code. “Large” refers to the number of parameters (learned weights, ranging from billions to hundreds of billions or more) and the sheer volume of training data (often measured in trillions of tokens).
Today, the ecosystem includes major families like OpenAI GPT (including GPT-6 Sol and GPT-6 Astra), Anthropic Claude, Google Gemini, Meta Llama, DeepSeek, Alibaba Qwen, and Mistral. Popular interfaces like ChatGPT, Claude.ai, and Gemini are chat applications built on top of these underlying LLMs. This guide covers what makes a model “large”, how LLMs work step by step, how they scaled from 117 million parameters to hundreds of billions, what they cost, where they fail and how to get better results from them. Current models and prices are tracked in our AI model directory.
<img src=“/images/llm-chatgpt-phone.webp” alt=“A smartphone showing the ChatGPT app with the prompt “What can I help with?”” width=“1600” height=“900” loading=“lazy” decoding=“async” />
What makes a language model “large”
The distinction between a standard language model and an LLM lies primarily in scale and the emergent abilities that come with it. While traditional statistical language models might rely on simple n-gram frequencies or small neural networks, LLMs leverage massive parameter counts and vast datasets to capture complex linguistic patterns, reasoning structures, and factual knowledge.
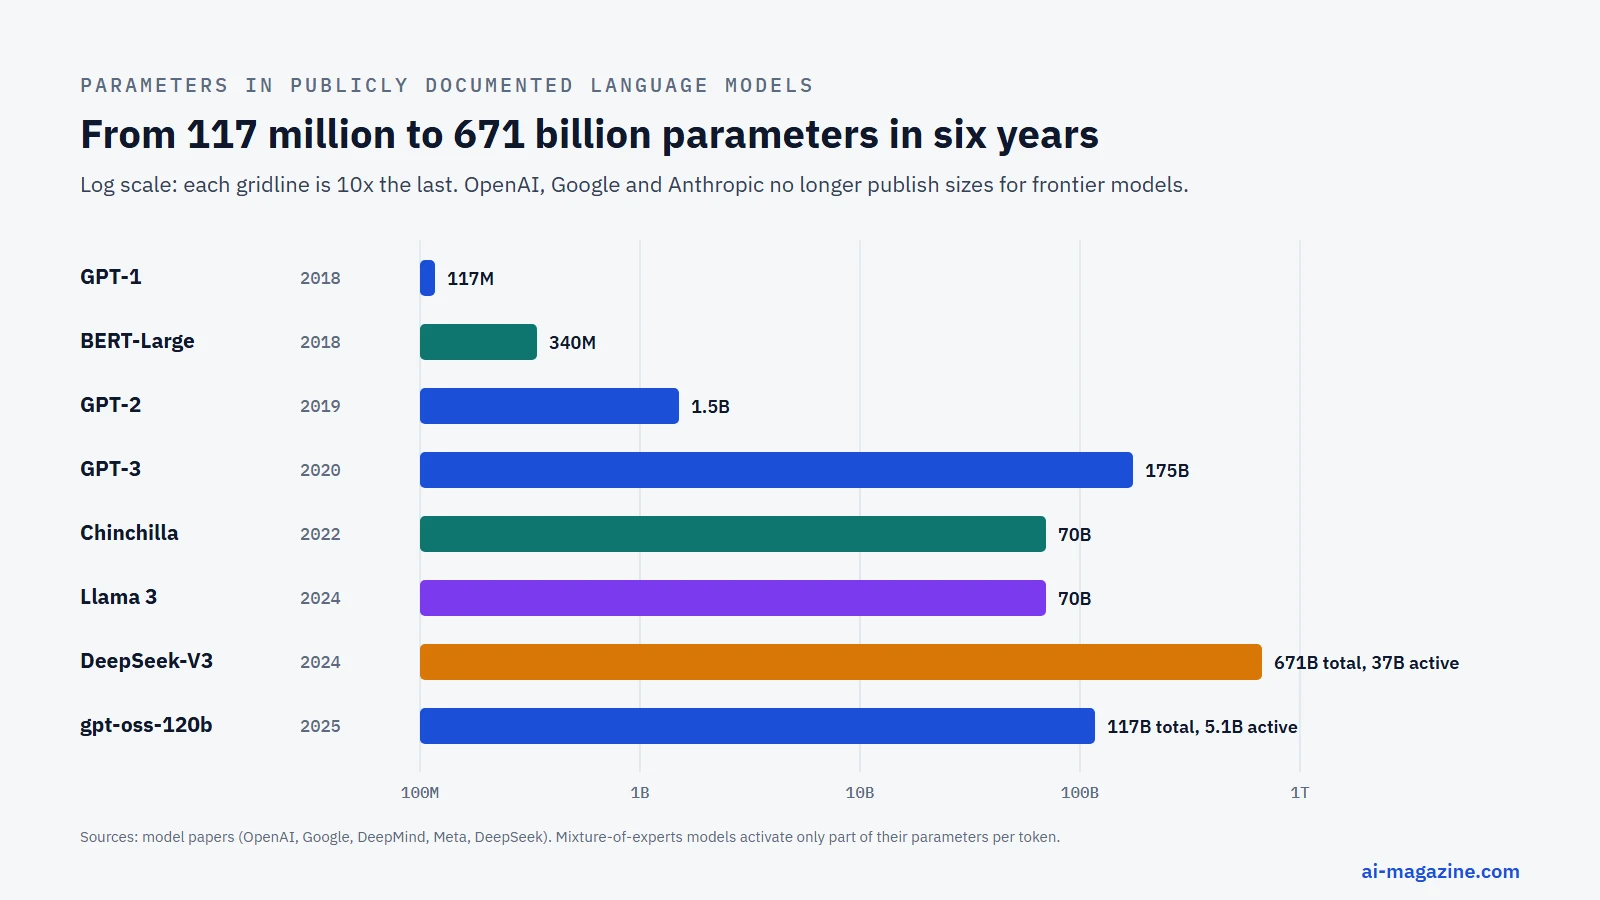
Parameters are the internal adjustable weights that the model learns during training. They determine how the model interprets the relationship between words and concepts. An LLM typically contains billions of these parameters. For context, early models like GPT-1 had only 117 million parameters. GPT-3 had 175 billion, and among models whose size is public, mixture-of-experts designs such as DeepSeek-V3 reach 671 billion. Frontier labs no longer publish these numbers for their closed models. The more parameters a model has, the greater its capacity to store information and perform complex transformations, provided it is trained on sufficient data.
Equally important is the volume of training data, measured in tokens. A token is a chunk of text, which can be a word, part of a word, or a punctuation mark. To train a modern LLM, datasets often comprise trillions of tokens scraped from the internet, books, code repositories, and academic papers. The relationship between parameters and data is critical; simply increasing parameters without increasing data leads to diminishing returns, while increasing data without enough parameters limits the model’s ability to learn from that data. Research has formalised this relationship through scaling laws, which describe how performance improves predictably as you increase model size, dataset size, and compute. At this scale, models become capable of zero-shot and few-shot learning: performing tasks they were never explicitly trained for, given only a prompt and perhaps a few examples.
How LLMs work, step by step
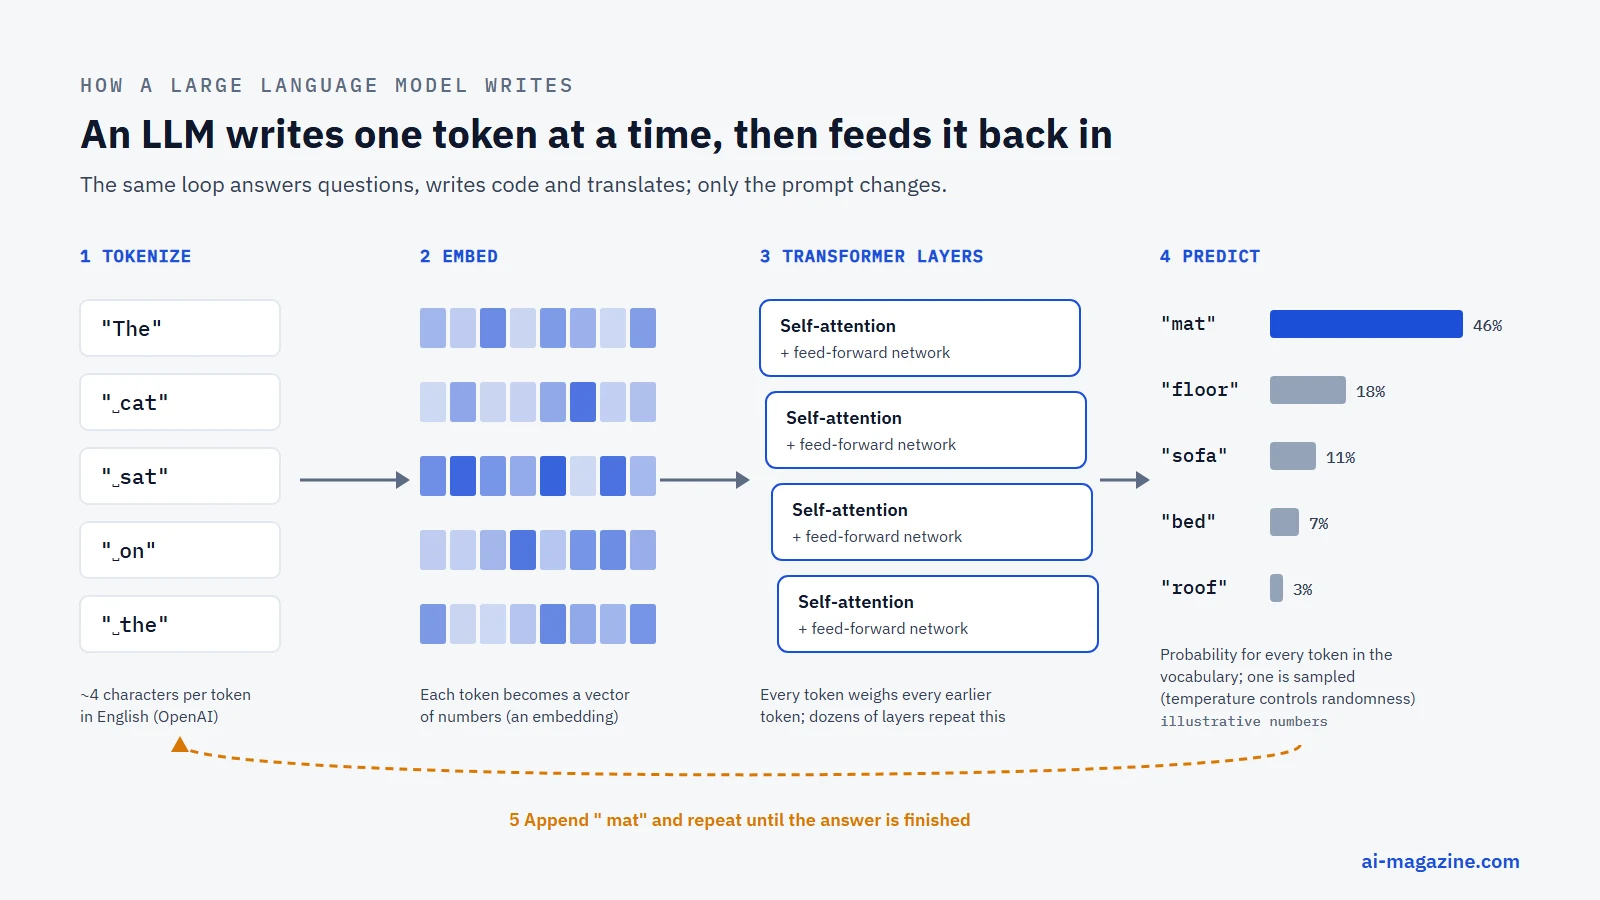
To understand how an LLM functions, you must trace the path of data from raw text to generated output. This process involves several distinct stages: tokenisation, embedding, attention mechanisms, prediction, and training.
1. Text becomes tokens
When you input text into an LLM, the model does not read it like a human. It breaks the text down into smaller units called tokens. A tokenizer handles this process, typically using algorithms like Byte-Pair Encoding (BPE); see tokenization. This method splits text into sub-word pieces, allowing the model to handle rare words or out-of-vocabulary terms by breaking them into known components.
For English text, OpenAI provides a useful rule of thumb: one token is roughly four characters or about three-quarters of a word. Consequently, 100 tokens approximate 75 words. Each token is then converted into an integer ID based on the model’s vocabulary. This numerical representation is the first step in making text machine-readable. The tokenizer ensures that every piece of text, whether it is a common word like “the” or a complex technical term, is reduced to a discrete unit that the neural network can process.
2. Tokens become vectors (embeddings)
Once text is tokenised into IDs, those IDs are mapped to dense numerical vectors known as embeddings. An embedding is a list of floating-point numbers that captures the semantic meaning of the token. Tokens with similar meanings, such as “king” and “queen,” will have vectors that are close together in this high-dimensional space.
These embeddings serve as the initial input to the transformer layers. They are not static; as the text passes through the model’s layers, the vectors are continuously transformed. Each layer refines the representation, adding context. By the time the vectors exit the final layer, they contain rich contextual information about how the token relates to every other token in the prompt. This ability to represent meaning in a continuous vector space is what allows LLMs to perform tasks like translation and analogy-making.
3. Attention: the transformer at the core
The architectural engine of most modern LLMs is the transformer, introduced in the 2017 paper “Attention Is All You Need” by eight Google authors. This architecture dispensed with recurrence and convolutions entirely, relying instead on self-attention. Our visual explainer of attention shows the maths step by step.
Self-attention allows every token in the input sequence to weigh the importance of every other token. If you are processing the sentence “The animal didn’t cross the street because it was too tired,” the model uses attention to determine that “it” refers to the “animal,” not the “street.” In most chat LLMs, the architecture is decoder-only with masked attention. This means that when predicting a token at position N, the model can only attend to tokens at positions 1 through N, ensuring that future information doesn’t leak into the prediction. This causal masking is crucial for autoregressive generation, where the model predicts text one token at a time in a forward direction.
4. Predicting the next token
The core task of an LLM is next-token prediction. After processing the input through the transformer layers, the final layer outputs a probability distribution over the entire vocabulary for the next token. For example, if the prompt is “The sky is”, the model might assign high probabilities to “blue,” “clear,” or “dark,” and low probabilities to “banana” or “jump.”
To generate text, the model samples from this distribution. One common method is sampling with temperature. Temperature controls randomness: a lower temperature makes the model more deterministic and focused on high-probability tokens, while a higher temperature introduces more variety and creativity. The selected token is appended to the input, and the process repeats. This loop continues until an end-of-sequence token is generated or a limit is reached.
The context window is the maximum number of tokens the model can consider at once. If the input exceeds this window, earlier information is truncated or compressed. The context window size is a critical constraint for developers, as it determines how much historical data or long documents the model can process in a single inference.
5. How an LLM is trained
Training an LLM is a multi-stage process that transforms raw data into a usable model.
First is pre-training. The model is trained on massive, unlabeled text corpora using self-supervised learning. The objective is simple: predict the next token in a sequence. This phase teaches the model grammar, facts, reasoning patterns, and code structures. It requires enormous compute resources.
Second is supervised fine-tuning (SFT) or instruction tuning. Pre-trained models are good at predicting text but not necessarily at following instructions. Developers curate datasets of example conversations (prompt-response pairs) and fine-tune the model to align its outputs with human expectations. This makes the model more useful for chat and task-based applications.
Third is reinforcement learning from human feedback (RLHF). Human evaluators rank different model outputs, and a reward model is trained to predict these preferences. The LLM is then optimised using reinforcement learning to maximise these rewards, further aligning it with human values and preferences.
Recently, a fourth stage has emerged for reasoning models: reinforcement learning on problems with checkable answers. Models like OpenAI’s o1, released on 12 September 2024, demonstrated that performance consistently improves with more reinforcement learning (train-time compute) and with more time spent thinking (test-time compute). In practice, such models write out a long chain of thought before giving a final answer.
The effectiveness of these stages is evident in results like InstructGPT (March 2022). Human evaluators preferred outputs from a 1.3B-parameter InstructGPT model over the 175B GPT-3 model, despite InstructGPT having 100 times fewer parameters. This showed that alignment and instruction tuning could outweigh raw scale in perceived quality.
LLM vs generative AI vs AI vs chatbot
These terms are often used interchangeably, but they represent distinct layers in the technology stack. Understanding the hierarchy is essential for technical product managers and developers.
| Term | What it is | Example |
|---|---|---|
| AI | The broadest category, encompassing any system that mimics human intelligence, including rule-based systems and machine learning. | Self-driving cars, spam filters |
| Generative AI | A subset of AI that creates new content (text, images, audio) rather than just classifying or predicting existing data. | DALL-E, Midjourney, LLMs |
| LLM | A specific type of generative AI model based on transformer architecture, trained on text to predict next tokens. | GPT-4, Llama 3, Claude |
| Chatbot | An application interface that uses an LLM (or other AI) to converse with users. | ChatGPT, Claude.ai, Gemini |
An LLM is a model. A chatbot is an application that wraps that model in a user interface. Generative AI is the capability of the model to create new content. AI is the overarching field. Most modern chatbots are powered by LLMs, but not all generative AI is text-based (e.g., image generators), and not all AI is generative (e.g., recommendation engines).
From GPT-1 to today: how LLMs scaled
The history of LLMs is a story of steadily larger models trained on more data, with more compute.
It started with GPT-1 in June 2018, a 12-layer decoder-only transformer with 117 million parameters, trained on the BooksCorpus of over 7,000 unpublished books. This was a proof of concept for transfer learning. Later in 2018, Google released BERT, an encoder-only transformer. BERT-Large had 340 million parameters and raised the GLUE benchmark score to 80.5%, demonstrating the power of bidirectional attention.
In February 2019, OpenAI released GPT-2 with 1.5 billion parameters, trained on 40 GB of text from over 8 million documents. It showed that scale improved text coherence and creativity. By May 2020, GPT-3 arrived with 175 billion parameters, trained on about 300 billion tokens. It was 10 times larger than any previous non-sparse language model and demonstrated few-shot learning, where it could perform tasks by providing examples in the prompt.
In between, two research results reshaped how labs spent their compute: OpenAI’s 2020 scaling laws and DeepMind’s 2022 Chinchilla paper, both explained in the scaling section below.
November 2022 saw the launch of ChatGPT, bringing LLMs to the mainstream. Meta entered the open-weight space with Llama 3 in April 2024, pre-trained on over 15 trillion tokens, seven times Llama 2’s data, released at 8B and 70B parameters. DeepSeek followed in December 2024 with DeepSeek-V3, a mixture-of-experts model with 671B total parameters but only 37B active per token. It was trained on 14.8 trillion tokens using 2.788 million H800 GPU hours, DeepSeek put the cost of the final training run at $5.576 million; the caveats are covered below.
OpenAI’s open-weight gpt-oss-120b, released in August 2025, has 117B total parameters with 5.1B active per token. Meanwhile the closed frontier went dark: according to the Stanford AI Index 2026, labs no longer disclose parameter counts or training data for their frontier models, so the table below stops at models whose figures are public.
| Model | Year | Parameters | Training data |
|---|---|---|---|
| GPT-1 | June 2018 | 117 million | BooksCorpus (over 7,000 books) |
| BERT-Large | October 2018 | 340 million | BooksCorpus + English Wikipedia |
| GPT-2 | February 2019 | 1.5 billion | WebText (40 GB, 8 million docs) |
| GPT-3 | May 2020 | 175 billion | About 300 billion tokens |
| Chinchilla | March 2022 | 70 billion | About 4× Gopher’s data |
| Llama 3 | April 2024 | 8B / 70B | Over 15 trillion tokens |
| DeepSeek-V3 | December 2024 | 671B (37B active) | 14.8 trillion tokens |
| gpt-oss-120b | August 2025 | 117B (5.1B active) | Not published in detail |
Scaling laws: why bigger (and longer-trained) models got better
The relationship between model size, data volume, and performance is not linear; it follows a predictable mathematical pattern known as the scaling law. In January 2020, researchers at OpenAI published a paper establishing that the loss (error rate) of a language model scales as a power-law function of three variables: model size, dataset size, and the amount of compute used for training. This meant that simply adding more parameters would yield diminishing returns unless the training data and compute scaled proportionally.
For years, the industry assumed that massive parameter counts were the primary driver of intelligence. DeepMind’s own Gopher, a 280-billion-parameter model announced in December 2021, followed that recipe: very large, but trained on relatively little data for its size. DeepMind’s subsequent release of Chinchilla in March 2022 corrected this trajectory. The Chinchilla paper demonstrated that for every doubling of model size, the number of training tokens should also be doubled to maintain optimal efficiency. Chinchilla, a 70-billion-parameter model, used the same amount of compute as Gopher but with roughly four times more data. It outperformed Gopher on the MMLU benchmark, achieving a score of 67.5%, showing that training data matters as much as raw size.
However, the scaling formula expanded again with the introduction of reasoning models. OpenAI’s o1, released on 12 September 2024, demonstrated that performance does not stop at training time. The model showed that accuracy “consistently improves with more reinforcement learning (train-time compute) and with more time spent thinking (test-time compute).” This shift introduced a new variable: inference compute. Instead of generating a single token immediately, these models can spend additional compute cycles to evaluate multiple potential paths before settling on an answer. Scaling now has a third lever: besides parameters and training data, labs can spend more compute at inference time on hard problems.
What LLMs cost to build and run
Building a frontier model requires significant capital. According to the Stanford AI Index 2024, the compute cost for training GPT-4 was approximately $78 million, while Gemini Ultra required roughly $191 million. These are estimates of the compute used for the final training run; they do not include the extensive research, data cleaning, and engineering efforts that precede the final training phase.
DeepSeek’s V3 model, released in December 2024, offers a more granular look at these expenses. It is a mixture-of-experts model with 671 billion total parameters but only 37 billion active parameters per token. It was trained on 14.8 trillion tokens using 2.788 million H800 GPU hours. DeepSeek calculated the training cost at $5.576 million, assuming a rate of $2 per GPU hour. However, this figure covers “only the official training” and excludes prior research experiments and ablation studies, meaning the true cost of development was likely higher.
Inference costs have dropped dramatically. The Stanford AI Index 2025 notes that the cost of querying a GPT-3.5-level model fell over 280-fold between November 2022 and October 2024. This massive reduction in inference cost has made it feasible to run LLMs at scale in consumer applications, even if the initial training investment remains high. For most developers, the decision is no longer about whether an LLM is too expensive to run, but whether the latency and cost per token align with the value of the specific use case.
Open vs closed LLMs
The ecosystem is divided between closed API models and open-weight models. Closed models, such as OpenAI’s GPT, Anthropic’s Claude, and Google’s Gemini, are proprietary. Developers access them via API, paying per token without knowing the exact architecture or training data. These models often lead in raw capability and benchmark scores. As of March 2026, closed-weight models led open-weight models by 3.3% in performance, up from 0.5% in August 2024, according to the Stanford AI Index 2026.
Open-weight models, such as Meta’s Llama, DeepSeek, Qwen, Mistral, and OpenAI’s own gpt-oss-120b, allow developers to download the weights and run the model on their own hardware. This provides greater control, data privacy, and the ability to fine-tune the model for specific domains without recurring API fees. OpenAI’s gpt-oss-120b, released in August 2025, has 117 billion total parameters with 5.1 billion active per token and runs on a single 80 GB GPU. Smaller open models can even run on a laptop; see our guide to running an LLM locally with Ollama.
The trade-off is clear. Closed models offer ease of use and often higher baseline intelligence but introduce vendor lock-in and variable pricing. Open models offer transparency and control but require significant infrastructure expertise to run efficiently, especially for large models. The performance gap is small, a few percent, but it widened again in 2025–2026. Open models are a strong choice where data privacy and cost predictability matter more than the last few points of capability.
What LLMs are used for
LLMs have moved beyond simple chatbots into a wide array of professional applications:
- Chat assistants: Conversational interfaces that answer questions, provide recommendations, or act as customer support agents, such as ChatGPT, which now serves more than 1.2 billion weekly users as of October 2026.
- Writing and editing: Tools that draft emails, generate blog posts, rewrite text for clarity, or adjust tone and style based on user prompts.
- Coding: Assisting developers by generating code snippets, explaining complex functions, debugging errors, and converting code between programming languages.
- Search and question answering over documents (RAG): Retrieval-Augmented Generation systems that pull relevant information from private databases or documents to provide sourced answers with fewer hallucinations; see what is RAG.
- Summarisation: Condensing long articles, meeting transcripts, or legal documents into concise summaries while preserving key details.
- Translation: Translating text between languages, including tone and idiom.
- Classification and data extraction: Categorizing text into predefined labels or extracting specific entities (names, dates, amounts) from unstructured text for database entry.
- Agents that call tools: Models that can execute actions, such as searching the web, querying a database, or controlling software, based on the output of their reasoning process.
Limitations of LLMs
Despite their capabilities, LLMs have distinct limitations that developers must account for:
- Hallucination: Models can confidently state facts that are incorrect. According to Vectara’s hallucination leaderboard (updated 22 September 2026), which measures unsupported facts in summaries, rates range from 1.8% for the best-performing model to 12.2% for Claude Opus 4.6 and 9.3% for GPT-5.5. These rates vary by task and change monthly; our article on LLM hallucinations explains why they happen.
- Knowledge cutoff: Most models are trained on data up to a specific date. They cannot provide information about events that occurred after their training cutoff unless augmented with external tools.
- Prompt sensitivity: Small changes in wording or formatting can significantly alter the output, requiring careful prompt engineering to achieve consistent results.
- Bias: Models inherit biases present in their training data, which can lead to skewed representations of gender, race, or cultural norms in their outputs.
- Prompt injection: Malicious users can manipulate the model’s instructions by embedding hidden commands in the input text, potentially causing the model to ignore its original instructions or leak data.
- Cost and latency: Large models can be slow and expensive to run, especially when processing long contexts or using reasoning steps, which impacts user experience in real-time applications. See how to reduce LLM API costs.
- Opacity: Many frontier models are “black boxes.” Labs no longer disclose exact parameter counts or training data for these models (Stanford AI Index 2026), making it difficult to understand why a model behaves a certain way or where its knowledge originates.
How to get better results from an LLM
Improving LLM performance requires a combination of techniques:
- Prompting: Clear, structured instructions yield better results than vague requests. Using few-shot examples (providing sample input-output pairs) helps the model understand the desired format and logic.
- Retrieval-Augmented Generation (RAG): By feeding relevant documents into the context window, RAG grounds the model’s answers in specific data, reducing hallucinations and allowing the model to access up-to-date information without retraining.
- Fine-tuning: Adjusting the model’s weights on a specific dataset can improve performance for specialized tasks, such as legal document analysis or medical diagnosis, where domain-specific language is critical.
- Tool use: Enabling the model to call external APIs or databases allows it to perform actions and retrieve real-time data, extending its capabilities beyond its training data.
FAQ
What is an LLM in simple terms?
An LLM is a type of artificial intelligence that understands and generates human language. It works by predicting the next word (more precisely, the next token) in a sequence based on the text it has seen before. This ability allows it to perform tasks like writing, translation, and question answering.
How do LLMs work?
LLMs are neural networks, typically based on the transformer architecture. They process text as numbers (tokens) and use attention mechanisms to understand the relationship between words. During training, they learn to predict the next token in a sequence, which enables them to generate coherent text.
Is ChatGPT an LLM?
ChatGPT is not an LLM itself; it is a chat application. It runs on OpenAI’s GPT (Generative Pre-trained Transformer) models, which are the actual large language models. ChatGPT provides the interface and additional features, while the GPT model handles the language processing.
What is the difference between AI and an LLM?
AI is the broad field of creating machines that can perform tasks requiring human intelligence. LLMs are a specific type of AI focused on understanding and generating text. All LLMs are AI, but not all AI are LLMs; other AI types include computer vision and robotics.
What is the difference between an LLM and generative AI?
Generative AI is a subset of AI that creates new content, such as text, images, or audio. LLMs are a type of generative AI that specifically generates text. Generative AI includes other technologies like diffusion models for image generation, which LLMs do not perform.
What are examples of large language models?
Common examples include OpenAI’s GPT series, Anthropic’s Claude, Google’s Gemini, Meta’s Llama, DeepSeek, and Alibaba’s Qwen. These models vary in size, capability, and whether they are open-source or proprietary.
What are parameters in an LLM?
Parameters are the internal weights that the model learns during training. They determine how the model processes information and generates output. The number of parameters, often in the billions or hundreds of billions, is a key indicator of the model’s capacity and complexity.
Why do LLMs hallucinate?
LLMs hallucinate because they are designed to predict plausible text, not necessarily factual truth. If the training data contains errors or if the model lacks specific information, it may generate a confident but incorrect statement. This is a result of the probabilistic nature of their design.