AI glossary
Natural Language Processing (NLP)
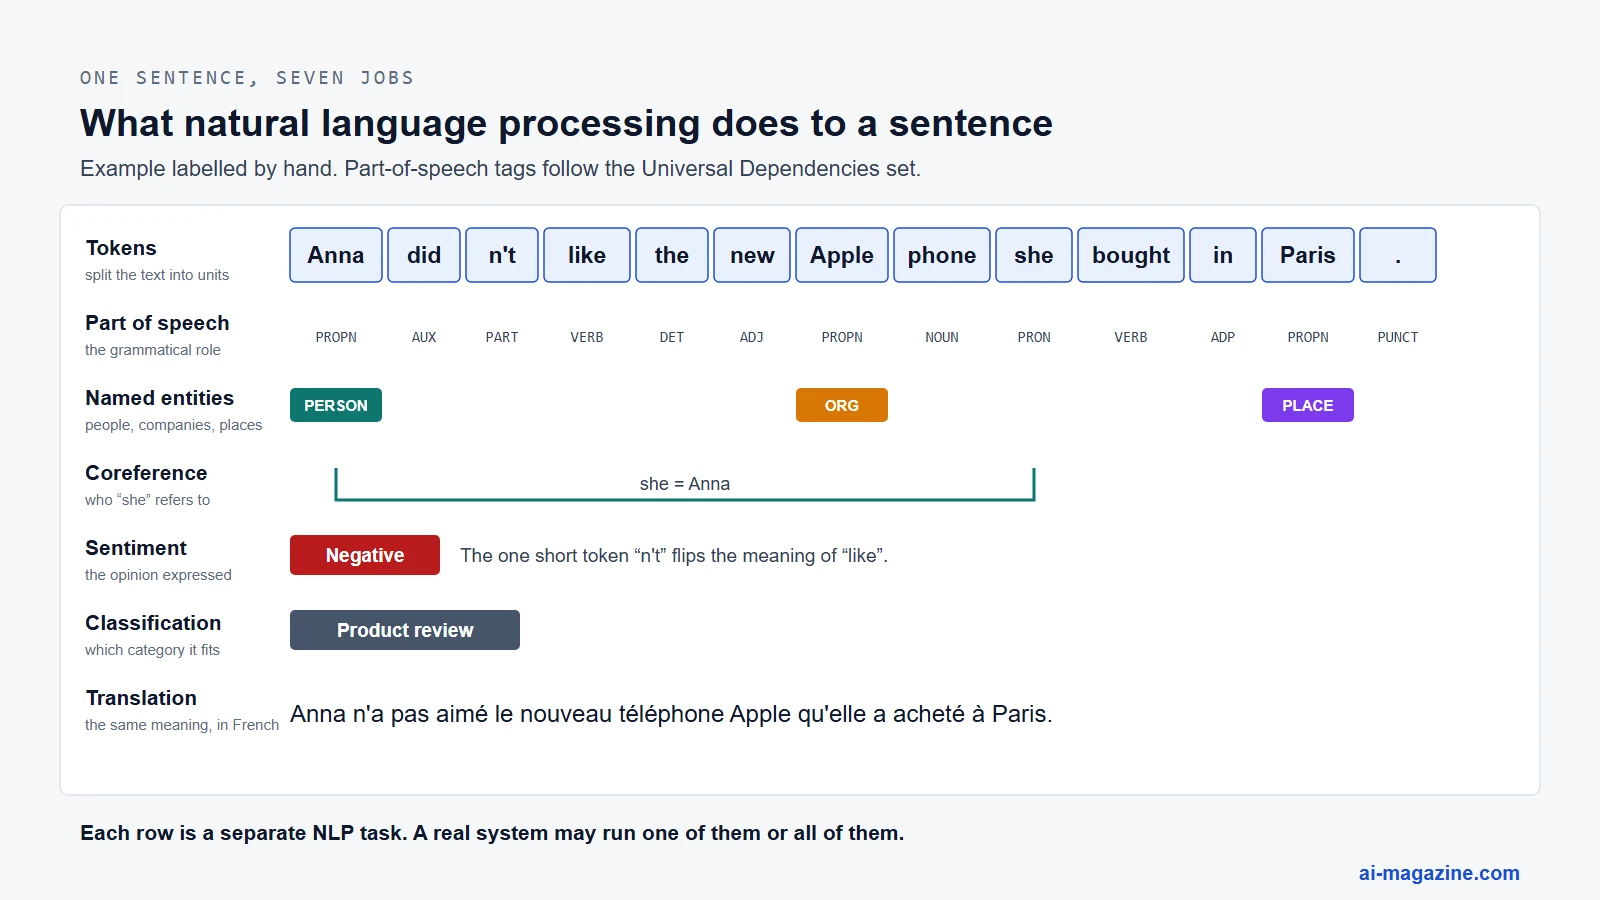
Natural language processing (NLP) is the field of AI that gets computers to do useful work with human language, written or spoken. Translation, spam filters, voice typing, search and chatbots are all NLP. So are many duller jobs, such as sorting support tickets or pulling company names out of contracts.
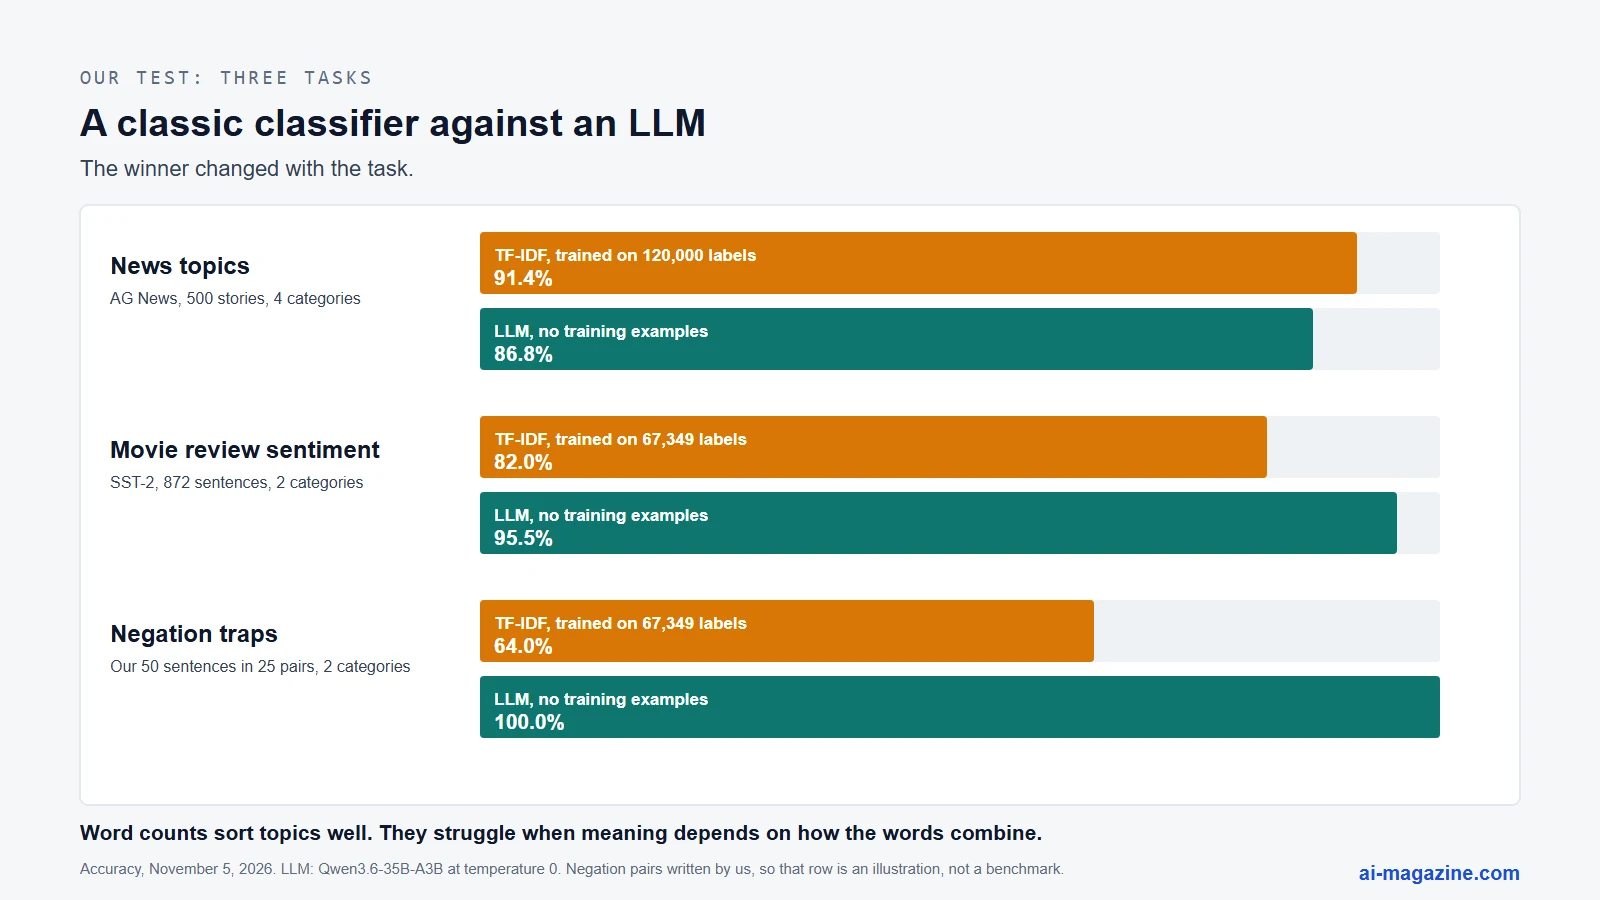
Large language models now dominate the field, so it is easy to assume an LLM is always the right tool. To check, we set a 1970s idea, TF-IDF word counting with a simple classifier, against an LLM on three tasks. The old method won on news topics by 91.4% to 86.8%, and the LLM won on review sentiment by 95.5% to 82.0%. On sentences built around negation, such as “It could not have been better”, the LLM got all 50 right and the old method got 64%. The rest of this guide explains what NLP is, how it works and how to choose between these tools.
What is natural language processing?
The field’s standard textbook, Jurafsky and Martin’s free Speech and Language Processing, does not offer a neat one-line definition. It treats NLP as one field with several names, including computational linguistics and speech recognition, and gives it a practical goal: getting computers to perform useful tasks involving human language.
“NLP” has a second meaning that causes real confusion. Neuro-linguistic programming is a coaching and therapy practice with nothing to do with computers. If you searched “NLP meaning” and found talk of practitioners and life coaching, that is the other one. This guide covers only the computing field.
The neighboring terms overlap, and vendor pages often make them sound more separate than they are:
| Term | What it means | How it relates to NLP |
|---|---|---|
| Machine learning | Software that learns patterns from data | The main source of NLP methods today, but it also covers images, numbers and more |
| Large language model (LLM) | A very large neural network trained to predict text | One family of NLP methods, and currently the dominant one |
| Natural language understanding | Going from text or speech to meaning | The reading direction of NLP |
| Natural language generation | Producing text to meet a goal | The writing direction of NLP |
| Computational linguistics | Using computing to study language itself | The ACL, the field’s professional body, treats it as nearly the same field as NLP |
| Speech recognition | Turning audio into text | Sometimes described as separate, but it is covered in the same textbook and often combined with NLP |
So ChatGPT is an NLP system, but NLP is not ChatGPT. The field is decades older and includes plenty of systems with no neural network in them.
How NLP works
Computers do arithmetic, so the first problem is turning language into numbers. Almost every NLP system, old or new, follows the same four steps.
- Split the text. Tokenization cuts text into units. Those can be words or, in modern systems, pieces of words. Translation systems now commonly use subword tokens.
- Turn tokens into numbers. This step is where the methods differ most.
- Run a model. A set of rules, a statistical classifier or a neural network works on those numbers.
- Produce an output. That might be a label, a set of highlighted names, a translation or a written answer.
The second step has moved through three main ideas:
| Representation | The idea | What it misses |
|---|---|---|
| Word counts and TF-IDF | Count each word, and give more weight to words that are rare across all documents. “Enron” tells you more than “the” | Word order. “Good, not bad” and “bad, not good” look the same |
| Embeddings | Give each word a list of numbers, so words used in similar contexts get similar lists | One word gets one meaning, whatever the sentence (“bank” of a river or a bank that lends) |
| Contextual models (transformers, BERT, LLMs) | Work out each word’s numbers from the words around it, using attention | Less about language than about cost, opacity and made-up answers |
The IDF half of TF-IDF comes from Karen Spärck Jones’s 1972 paper, written for document retrieval. It is still a good baseline more than 50 years later, as our test below shows.
Try it: would word counting catch this?
Take two reviews: “The wait was long” and “The wait was not long”. Word counting sees almost the same bag of words, with one extra “not”. And “not” appears in plenty of positive sentences too, so it is a weak signal alone. In our test, a TF-IDF model trained on more than 67,000 labelled phrases called both of these sentences negative. Adding two-word phrases such as “not long” to the model did not make it better overall.
Core NLP tasks, and how good the results are
Scores vary a lot by task. The figures below are published benchmark results. They use different metrics, so treat them as a rough guide and don’t compare one row directly with another. Several come from NLP-progress, a community leaderboard with no update dates, so newer systems may score higher.
| Task | Plain example | Published result |
|---|---|---|
| Part-of-speech tagging | “Book” here is a verb, not a noun | About 97% accuracy on English treebanks |
| Dependency parsing | Which word modifies which | 97.42 unlabelled attachment score, Penn Treebank |
| Named entity recognition | Spot “Apple” as a company | F1 of 94.6 on CoNLL-2003, 90.32 on OntoNotes |
| Sentiment analysis | Is this review positive? | 96.8% on SST-2, 96.21% on IMDb |
| Text classification | Route a ticket to billing | 92.36% with TF-IDF on AG News; supervised neural models reach about 95.6% |
| Coreference resolution | Who does “she” refer to? | F1 of 81.0 on CoNLL 2012 |
| Question answering | Find the answer in a passage | F1 of 93.2 for BERT on SQuAD 1.1 |
| Machine translation | English to German | BLEU of 28.4 for the original Transformer |
| Summarization | Shorten an article | ROUGE-1 of 47.78; the metric mainly measures word overlap, not quality |
| Speech recognition | Voice to text | 2.7% word error on clean audio, 25.5% at noisy dinner parties (Whisper large-v2) |
Two lessons come out of these numbers.
High accuracy can be cheap. A trivial part-of-speech tagger that gives each word its most common tag already scores about 92%. The best systems add only about five points. Always ask what the simplest possible method scores before being impressed by a figure.
The harder a task leans on knowledge of the world, the lower the score tends to be. Tagging needs mostly grammar. Coreference needs you to know how the world works. This is a rough pattern and not a law, because the metrics differ.
A short history of NLP
Most explainers tell a tidy story of rules, then statistics, then neural networks. Jurafsky and Martin tell it differently. Statistical and neural ideas both date from the late 1940s to early 1960s. Symbolic rules dominated from about 1965 to the early 1990s, and the data-driven approach then ran for decades. They mark prompting, from 2019, as the next big shift.
| Year | Event | The result |
|---|---|---|
| 1954 | Georgetown-IBM demonstration | Translated just over 60 Russian sentences with 250 lexical items and six rules. The press release predicted working translation within five years, perhaps three |
| 1966 | ALPAC report | A US committee found “no immediate or predictable prospect of useful machine translation” and recommended funding computational linguistics and better aids for human translators |
| 1966 | ELIZA | Simple pattern substitution imitated a therapist. People became deeply engaged anyway |
| 1972 | TF-IDF’s IDF idea | Rare words count for more when searching documents |
| 1990 | IBM statistical translation | Learned from 117,000 Canadian parliament sentence pairs with no grammar rules. 48% of test translations were reasonable |
| 1998 | Naive Bayes spam filter | Word statistics plus a few domain features caught spam with 100% precision and 98.3% recall on a 251-message test set |
| 2013 | word2vec | Learned word vectors from 1.6 billion words in under a day |
| 2016 | Google Neural Machine Translation | Cut translation errors by 60% on average in the paper’s side-by-side human tests. Google’s blog said 55% to 85% on major language pairs |
| 2017 | Transformer | Dropped recurrence for attention and trained in 3.5 days on 8 GPUs |
| 2018 | BERT | State-of-the-art results on 11 NLP tasks |
| 2020 | GPT-3 | 175 billion parameters. People spotted its longer news articles about 52% of the time, close to guessing |
| 2022 | ChatGPT | Brought LLMs to the general public |
A note on a common error: you may read that Georgetown-IBM translated 49 sentences. John Hutchins’s account explains that 49 is only one author’s partial list. The promised five years also turned out to be off by decades, a warning worth keeping in mind for today’s forecasts. For the wider story of how machines came to seem conversational, see our guide to the Turing test.
NLP examples in the real world
Most figures in this table come from the companies selling the product, so read them as claims and not as audited results.
| Where | What it does | The evidence |
|---|---|---|
| Web search | Reads a query’s meaning, not just its keywords | Google said BERT helped with 1 in 10 US English searches in 2019, and almost every English query by 2020 |
| Translation | Converts text between languages | Google Translate added 110 languages in 2024 with an LLM. Meta’s NLLB-200 covers 200 languages |
| Filters spam | Gmail claims to block more than 99.9% of spam, phishing and malware. That figure is Google’s own and covers more than language analysis | |
| Voice typing | Turns speech into text | Whisper’s average word error was 12.8, against 29.3 for an earlier system across the paper’s test sets |
| Customer support | Suggests replies to agents | A study of 5,179 agents found 14% more issues resolved per hour, 34% for novices and very little for the most skilled |
| Legal research | Finds and summarizes case law | Stanford researchers found leading legal AI tools produced false information 17% to 33% of the time |
Those last two rows are the realistic picture: real gains for many users, and errors that still need a human to catch them.
Our test: TF-IDF against an LLM
The published comparisons of LLMs and classic classifiers we read mostly use GPT-3, GPT-3.5 or GPT-4, and none of them tested zero-shot LLMs, LLMs given examples and TF-IDF together on AG News. So we ran that comparison ourselves on November 5, 2026.
The classic model. TF-IDF plus logistic regression in scikit-learn 1.9.1, using standard TF-IDF settings with sublinear term frequency, and regularization set to C=10. It ran on the CPU of an ordinary work computer.
The LLM. Qwen3.6-35B-A3B, an open-weight model, in a compressed, uncensored community build on our server. We ran it at temperature 0 with its thinking mode off and a limit of 12 output tokens. It got each text with a short instruction and a list of allowed labels, and no fine-tuning. This is a mid-sized model and not a frontier one.
The tasks:
- News topics. AG News, four categories, with 120,000 training stories. We tested the LLM on a random 500 of the 7,600 test stories, and the classic model on the same 500 and on all 7,600.
- Review sentiment. SST-2, positive or negative movie review phrases. The classic model trained on 67,349 of them, and both models took the 872-sentence validation set.
- Negation traps. We wrote 25 pairs of short sentences where negation sets the meaning, for example “It never disappoints” and “It always disappoints”. The classic model used the same SST-2 training. Since we wrote these ourselves, this task is an illustration and not a benchmark.
The results
| Task | TF-IDF | LLM, no examples | LLM, 8 examples |
|---|---|---|---|
| News topics, 500 stories | 91.4% (88.6 to 93.6) | 86.8% (83.6 to 89.5) | 84.0% (80.5 to 87.0) |
| Review sentiment, 872 sentences | 82.0% | 95.5% | Not run |
| Negation traps, 50 sentences | 64.0% | 100% | Not run |
| Labelled data needed | 67,000 to 120,000 here | None | 8 |
The numbers in brackets are 95% intervals. On news topics the TF-IDF and LLM intervals overlap a little, so 500 stories are not enough to call that gap decisive. For sentiment, TF-IDF scored 82.2% with two-word phrases added, barely different. On the negation pairs, adding those phrases made it worse at 58%.
What we learned
Topics are mostly about vocabulary. A story containing “stadium” and “coach” is almost certainly sports, and word counts capture that. Sentiment depends on how words combine. The classic model called “It could not have been better” negative, and “It was not a bad movie at all” too. It got both sentences right in only 7 of the 25 pairs. The LLM got all 25.
The labels you have decide a lot. With only 100 training examples, TF-IDF scored 66.8%. It drew level with the LLM at about 4,000 examples, scoring 87.4% across the full test set, though just 85.5% on our 500-story sample. Most of the later gain came slowly, with 40,000 examples reaching 90.7%.
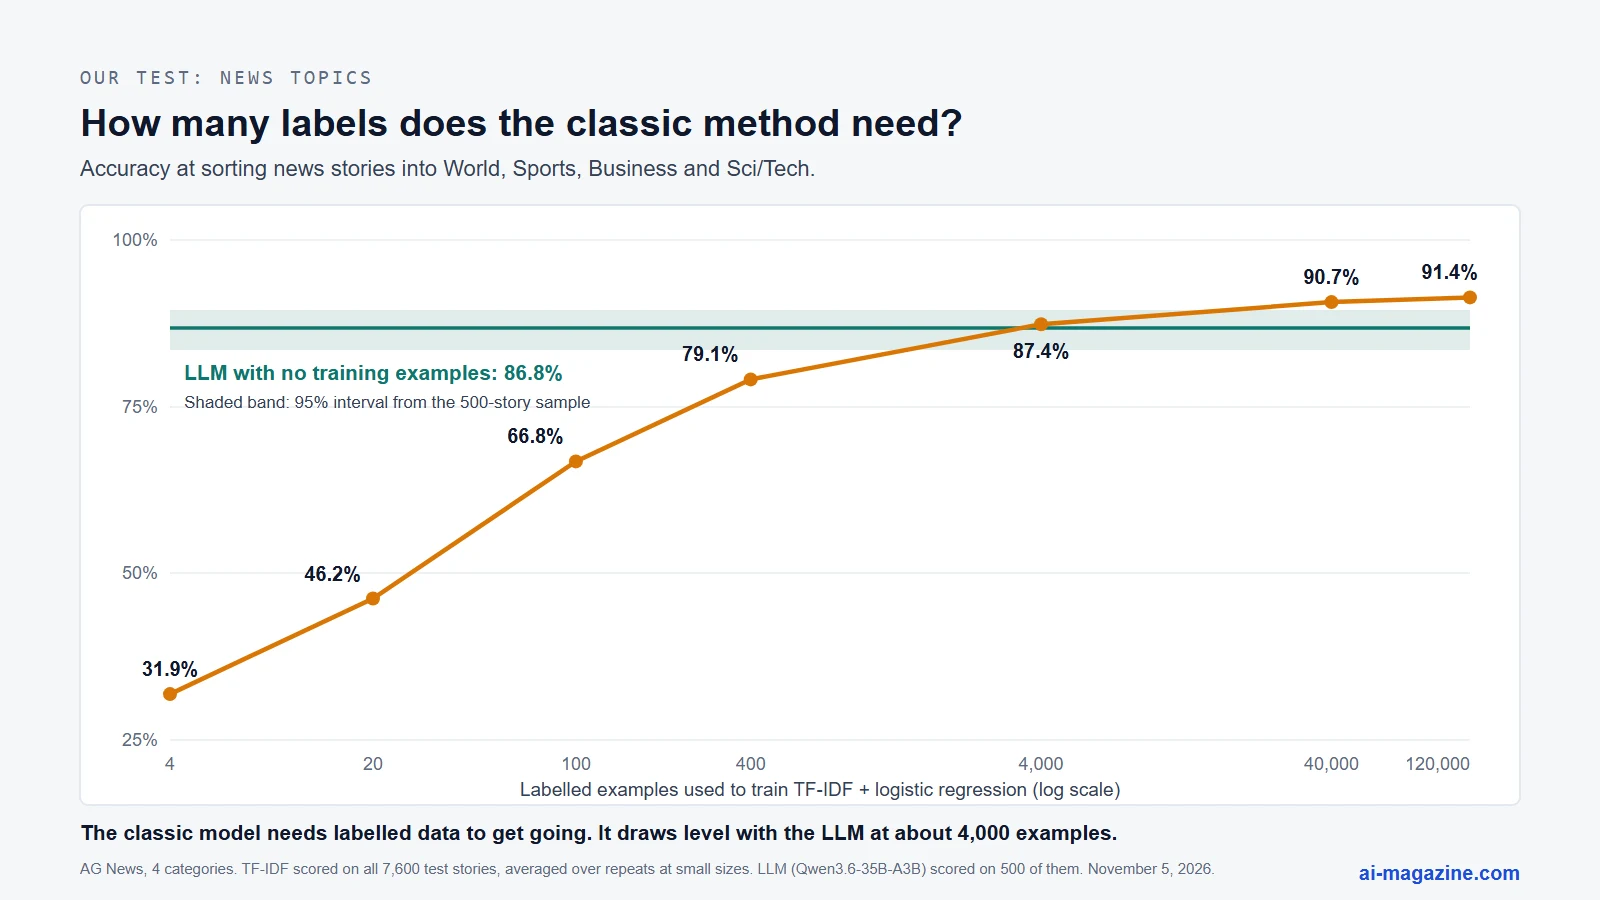
Giving the LLM examples didn’t help here. Eight examples, two per category, scored 84.0% against 86.8% with none. The intervals overlap, so this doesn’t prove examples hurt, but they used more than five times the input tokens for no visible gain. They were picked at random, and better chosen ones may do more.
Many errors were arguments about the label. Of the LLM’s 66 errors, 34 were calling Sci/Tech stories Business. A story about Intel cutting chip prices is labelled Sci/Tech, and both models called it Business, which is defensible. On 24 stories, both models disagreed with the official label. Some of the “ground truth” here is simply one reasonable opinion.
The classic model learned its era. The words most linked to each category included Enron and Martha for Business, and Arafat and Darfur for World. Others were pure noise, such as “39”, left over from an HTML code in the source text. The sample stories date from around 2004, and a model like this would be poor at 2026 news without new labels. An LLM needs no retraining for the labels, though it has its own knowledge cutoff.
Speed and cost are very different. TF-IDF labelled 7,600 stories in 0.57 seconds on that computer, about 13,000 per second. The LLM did about 22 per second, with 8 requests running at once on a separate server, so the two machines are not comparable. At the list price of GPT-6 Luna, $0.10 per million input tokens and $0.50 per million output, our token counts would come to about $0.012 per 1,000 labels. Other models count tokens differently and this is an estimate.
Repeat runs can differ. Running the same 500 stories again at temperature 0 changed 1 label. At temperature 0.7, 12 labels changed and accuracy was 86.2%. A saved TF-IDF model returns the same output for the same input every time, which is useful if someone audits your decisions.
How this fits published research
Published results are mixed. In the original AG News paper, TF-IDF over word n-grams reached 92.36%, ahead of the neural networks tested there. Zero-shot GPT-3 later scored 90.72% with a plain prompt and 92.60% with a reasoning prompt, about level with that and needing no labels. With 16 random examples, the reasoning prompt reached 95.18%, so examples helped there, unlike in our test. The same paper’s 96.40% relied on a fine-tuned model to pick its examples, so it isn’t a no-training result.
Mu and colleagues call logistic regression a weak baseline and say zero-shot LLMs generally beat it, and it does trail the best GPT-3.5 prompt on macro F1 in five of six tasks. But by our reading of their table, TF-IDF logistic regression beat that prompt on plain accuracy in four of six. They also found that different prompting strategies could shift accuracy and F1 by more than 10%. A larger replication of 27 annotation tasks found GPT-4 uneven enough that its authors recommend checking it against human labels task by task.
Limits of our test
- We tried one LLM, and a frontier model may do better. Better models could close the news gap.
- We used our first reasonable prompts and settings, and ran no tuning search on either side.
- The LLM’s sentiment score counts 2 unreadable replies as wrong.
- 500 news stories gives wide intervals. A difference of a few points may be noise.
- We wrote the negation pairs ourselves, and they are short and simple. Real reviews are messier.
- AG News and SST-2 are old, clean benchmarks. Your own data will behave differently, and that’s the data to test on.
Try the baseline yourself
This is close to the code we ran. It downloads AG News and needs pandas, pyarrow and scikit-learn. On our computer it scored 91.5%, and training took under a minute. It is slightly different from the 91.4% above because the labels and row order differ.
import pandas as pd
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.linear_model import LogisticRegression
from sklearn.pipeline import make_pipeline

base = "https://huggingface.co/api/datasets/fancyzhx/ag_news/parquet/default/"
train = pd.read_parquet(base + "train/0.parquet")
test = pd.read_parquet(base + "test/0.parquet")

model = make_pipeline(
    TfidfVectorizer(sublinear_tf=True),
    LogisticRegression(max_iter=2000, C=10),
)
model.fit(train.text, train.label)
print("accuracy:", round(model.score(test.text, test.label), 4))

labels = ["World", "Sports", "Business", "Sci/Tech"]
print(labels[model.predict(["Rocket startup raises $200 million ahead of IPO"])[0]])
Which NLP approach should you use?
Our test and the research above point to a simple order of work. Start with the cheapest thing that could work, and measure it on a few hundred of your own labelled examples.
| Your situation | Start with | Why |
|---|---|---|
| Fixed patterns such as dates, order numbers or postcodes | Rules or regular expressions | Exact, free and easy to explain |
| Topic sorting with thousands of labels | TF-IDF and a linear classifier | Cheap, fast, repeatable. Hard to beat on vocabulary-driven tasks |
| No labels, or you need an answer today | An LLM with a clear prompt | Works at once. Use it to get started or to help create labels |
| Sentiment, intent, or anything where meaning depends on word order | An LLM or a fine-tuned transformer | Our largest gaps were here |
| Millions of items, or strict latency | A trained classifier, possibly on embeddings | Speed is far higher and no per-call fee applies. One study found logistic regression on small-model embeddings usually beat GPT-4 on simple sentence tasks once it had a few dozen labels per class |
| Writing, summarizing, or open questions | An LLM | Classic methods don’t really do this |
| Decisions that must be audited | A simple saved model, or an LLM with human review | The output is repeatable and easier to explain |
Whatever you choose, keep a held-out set of examples that nobody tuned on. If you use accuracy, also check per-category results, because a model can look strong overall while failing on the rare category you care most about.
The limits of NLP
Ambiguity and world knowledge. In “The trophy didn’t fit into the suitcase because it was too large”, “it” means the trophy. Change “large” to “small” and it means the suitcase. These Winograd schemas were proposed as a hard test of machine understanding, but transformer systems passed 90% by 2019. The authors of that review conclude the test measured less than its designers hoped, which echoes the fate of the Turing test.
Sarcasm. It was hard for the models tested in 2023. On one sarcasm dataset, the top F1 in Mu and colleagues’ study was just 65.8.
Most languages get left out. There are about 7,000 languages in the world. A 2020 survey put 88.38% of the languages it classified, spoken by 1.2 billion people, in the lowest resource group. Seven languages, including English and Spanish, had the most. Even the 243 languages Google Translate reportedly reached in 2024 are about 3.5% of the total. Speech error rates show the gap as well: Jurafsky and Martin’s rough figures run from under 3% on clean English audio to about 50% on Bengali and Swahili test sets.
Bias. Models absorb patterns in their training text. A 2016 study of Google News word vectors found the analogy “man is to computer programmer as woman is to homemaker”. In a 2020 PNAS study, five commercial speech-to-text tools had an average word error of 0.35 for Black speakers and 0.19 for white speakers.
Hallucination. LLMs can invent people and facts, and they aren’t well calibrated about their own confidence. Speech tools can do it too: one 2024 study found invented phrases or sentences in about 1% of Whisper transcriptions of its aphasia-study audio, in 2023 tests. For more, see our analysis of LLM hallucinations.
Prompt injection. An LLM reads instructions and data as the same stream of text, so text hidden in a web page or email can take control of the application. OWASP says it is unclear whether a foolproof defense exists. A TF-IDF classifier can be fooled, but it can’t be given new instructions.
Privacy. Researchers extracted 604 memorized training examples from GPT-2, some with personal data. Sending customer text to an outside API also raises its own questions.
Energy. A widely quoted claim says training a model emits as much as five cars. That figure is for a full neural architecture search of 626,155 pounds of CO2e, not for training one model, which the same paper put at 192 pounds. Later work showed that location and hardware change such estimates a great deal. Current frontier training runs are much larger, and vendors publish little about them.
Tools for getting started with NLP
All four are free and open source. Versions were checked on November 5, 2026.
| Tool | Best for | Current version |
|---|---|---|
| scikit-learn | TF-IDF, classic classifiers and your first baseline | 1.9.1 |
| spaCy | Fast production pipelines for tagging and named entities | 3.8.18 |
| NLTK | Learning the basics, with more than 50 corpora and a free book | 3.10.4 |
| Hugging Face Transformers | Using or fine-tuning neural models, when the baseline falls short | 5.22.1 |
A sensible route is to build the scikit-learn baseline first, then try an LLM or a transformer on the same held-out examples. The comparison tells you whether the extra cost buys anything. To price the LLM side, see our API pricing tables.
Frequently asked questions
What does NLP stand for in AI?
Natural language processing: the field of getting computers to do useful work with human language. It has nothing to do with neuro-linguistic programming, the coaching practice that shares the abbreviation.
Is ChatGPT natural language processing?
Yes. ChatGPT is an application of NLP built on a large language model. NLP is the wider field, and it also includes spam filters, spell-checkers and translation systems that use no LLM at all.
What is the difference between NLP and machine learning?
NLP is defined by its subject, which is human language. Machine learning is defined by its method, which is learning from data. They overlap heavily, since most modern NLP uses machine learning, but rule-based NLP needs no machine learning, and machine learning also covers images and numbers.
Have LLMs made older NLP methods obsolete?
No. In our test, a TF-IDF classifier beat a mid-sized LLM on news topics and ran hundreds of times more items per second, though on different hardware. Jurafsky and Martin still describe supervised machine learning as the most common way to classify text. LLMs are often the better choice when you have no labels or when meaning depends on context.
What are the main NLP techniques?
Tokenization, part-of-speech tagging, parsing, named entity recognition, sentiment analysis, text classification, summarization and translation are the main tasks. The main technique families are rules, statistical models like TF-IDF with a classifier, embeddings, and transformers, including LLMs.
Which programming language is best for NLP?
Python, in practice. All four tools in the table above are Python libraries, and most research code is published in it.
Related terms
- Large Language Model (LLM): the dominant family of NLP models today.
- Tokenization: the first step of almost every NLP pipeline.
- Embedding: turning words and texts into lists of numbers.
- Transformer: the architecture behind BERT and modern LLMs.
- Sentiment Analysis: working out the opinion in a text.
- Named Entity Recognition: finding names of people, companies and places.
- Reinforcement Learning: a different branch of machine learning, also used in training chatbots.