AI glossary
Reinforcement Learning
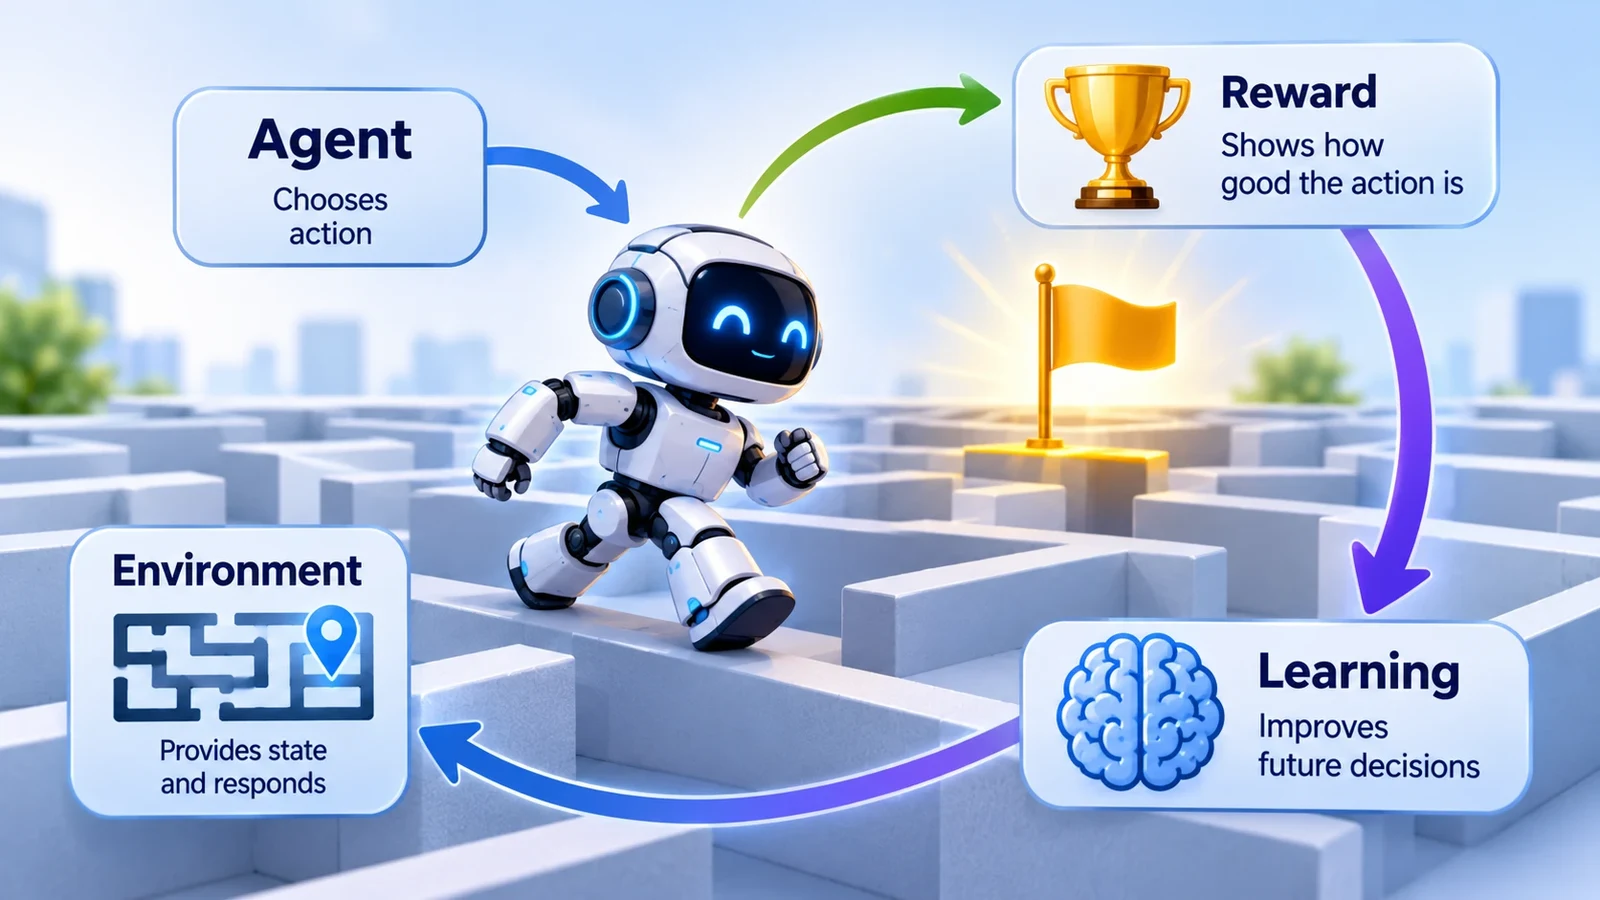
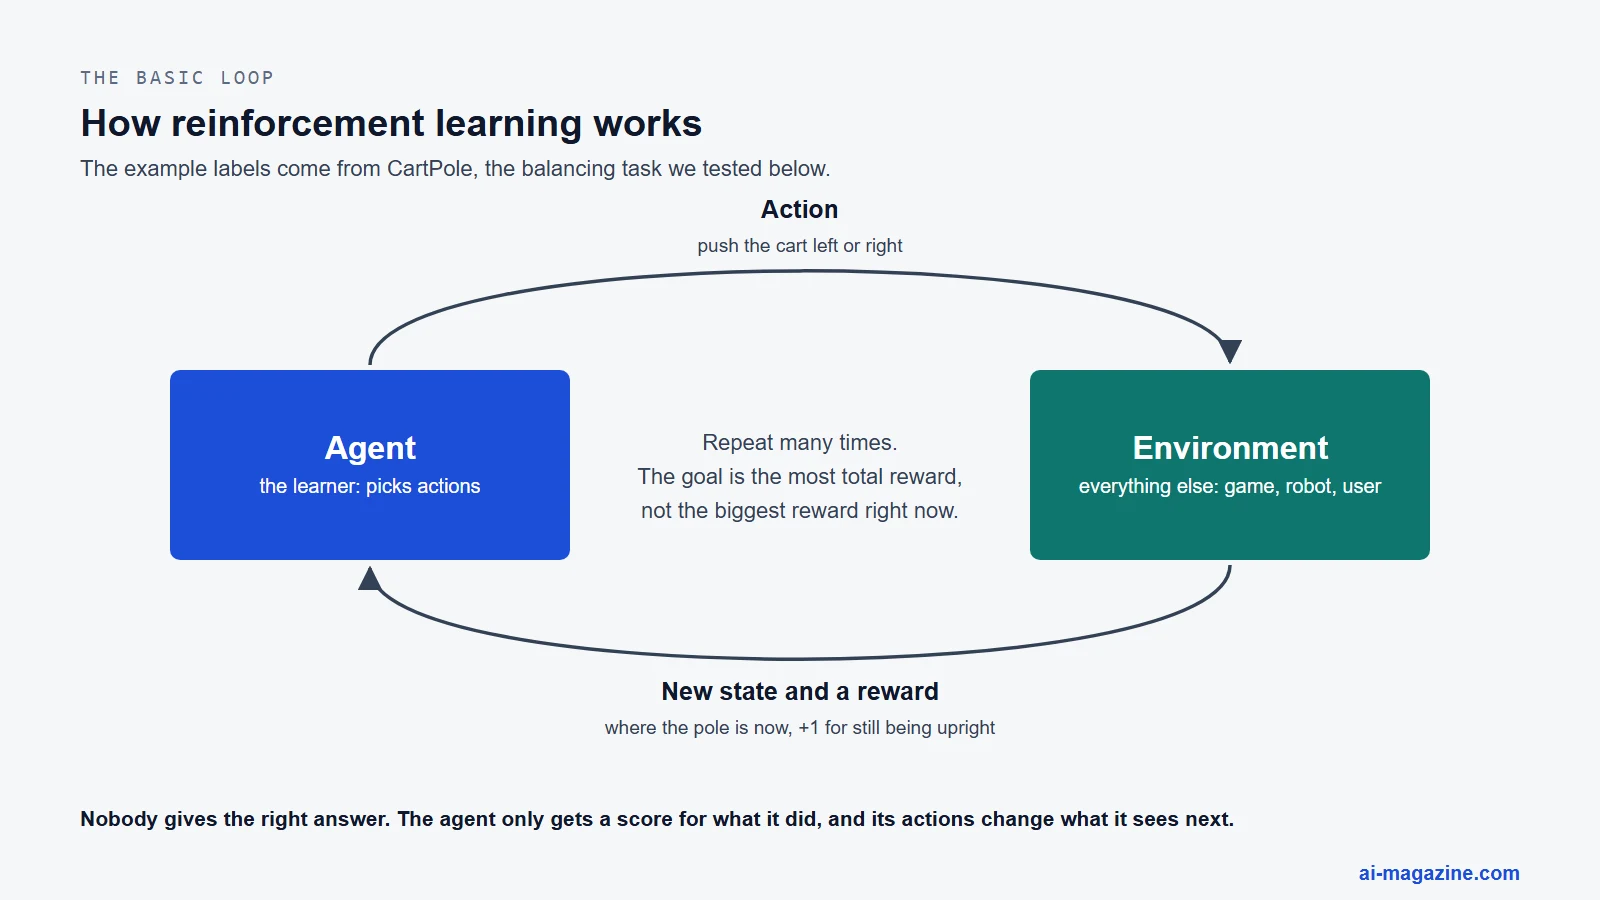
Reinforcement learning (RL) is a type of machine learning in which software learns by trial and error. An agent takes actions, receives a score called a reward, and gradually works out which behavior earns the most reward over time. Nobody shows it the right answers. It has to discover them by trying things, much as you might train a dog with treats, except that the dog here may need millions of attempts.
RL is behind AlphaGo, walking robots and part of the training of today’s chatbots. It is also unusually good at finding the wrong solution to the problem you meant to set. To see both sides for ourselves, we trained agents on a classic balancing task. A single line of reward code turned a balancing agent into one that drove off to the edge of the track, and turning off exploration left it worse than random button-pressing.
What is reinforcement learning?
The standard textbook, Richard Sutton and Andrew Barto’s Reinforcement Learning: An Introduction, defines it as learning how to map situations to actions so as to maximize a numerical reward signal. The learner isn’t told which actions to take. It has to find out which ones pay off by trying them.
Sutton and Barto shared the 2024 ACM Turing Award, computing’s top honor, for developing the foundations of the field. Their book is free to read online and remains the place to go if you want the full mathematics.
The key terms in plain English
| Term | What it means | Chess example |
|---|---|---|
| Agent | The learner and decision-maker | The player |
| Environment | Everything outside the agent | The board and the opponent |
| State | The situation right now | The current position |
| Action | A choice the agent can make | A legal move |
| Reward | The immediate score | +1 for a win, -1 for a loss, 0 otherwise |
| Policy | The agent’s way of behaving: what it does in each state | Its playing style |
| Value | How much total reward to expect from here | How good this position really is |
| Discount factor | How much future rewards count against immediate ones, between 0 and 1 | Patience for a long plan |
| Episode | One complete run, from start to finish | One game |
The difference between reward and value is the heart of the idea. Reward tells you what is good right now, and value tells you what is good in the long run. Sacrificing a queen has no immediate payoff, but it may be the best move on the board if it forces mate. Formally, these problems are usually described as a Markov decision process, which simply means the current state holds everything the agent needs to choose its next move.
Exploration versus exploitation
An agent has to use what it already knows to earn reward, and it also has to try new things that might turn out better. Neither works alone. It’s the same choice you face between your favorite restaurant and the new place down the street, except the agent makes it millions of times. This problem doesn’t even arise in supervised learning as usually defined, because there the data doesn’t depend on what the model does. We show what happens without exploration in our test below.
Reinforcement learning vs supervised and unsupervised learning
The textbook calls RL a third machine learning paradigm, alongside the other two.
| Supervised learning | Unsupervised learning | Reinforcement learning | |
|---|---|---|---|
| What it gets | Examples with right answers | Data with no answers | A score for what it did |
| Goal | Predict the right answer | Find hidden structure | Earn the most reward over time |
| Does it affect its own data? | No | No | Yes, its actions change what it sees next |
| Everyday example | Spam filter | Customer groups | Game-playing agent |
Real systems mix all three. AlphaGo first learned from human games with supervised learning, then improved through self-play. ChatGPT’s predecessor InstructGPT used supervised training and then RL. For a wider map of the field, see our guide to how AI works.
How does reinforcement learning work?
There are several families of methods, and the names overlap. These are the distinctions you’ll meet most often.
| Split | First option | Second option |
|---|---|---|
| Does it use a model of the world? | Model-free: pure trial and error (Q-learning, PPO) | Model-based: learns or uses a model that predicts what happens next, then plans (MuZero, Dreamer) |
| What does it learn? | Value-based: how good each action is (Q-learning, DQN) | Policy-based: how to act, directly (REINFORCE, PPO) |
| Whose behavior is it learning about? | On-policy: the policy it’s currently following (SARSA, PPO) | Off-policy: a different policy from the one generating its data (Q-learning, DQN, SAC) |
Actor-critic methods combine the first two ideas in that middle row. The “actor” is the learned policy, and the “critic” is a learned value function that judges the actor’s choices. Multi-agent RL has several agents learning together or against each other, as in AlphaStar and OpenAI Five.
What is Q-learning?
Q-learning is the classic RL algorithm, and the textbook calls it one of the field’s most important breakthroughs. Chris Watkins introduced it in 1989. The idea is to keep a score, called a Q-value, for every action in every state, then improve those scores from experience.
Each time the agent acts, it nudges the score toward what it just saw:
new Q = old Q + learning rate × (reward + discount × best Q of next state − old Q)
Here’s one step with numbers. Say the current score is 2.0, the learning rate 0.1, the reward 1 and the discount 0.99, and the best action in the next state scores 3.0. The target is 1 + 0.99 × 3.0 = 3.97. The new score is 2.0 + 0.1 × (3.97 − 2.0) = 2.197. Repeat that millions of times and good actions gradually rise to the top of the table. The agent’s future reward flows backward, one state at a time, which is how a win at the end of a game eventually gives credit to a move made much earlier.
Q-learning learns about the best policy even while it behaves differently, for example while exploring at random. SARSA, a close relative, learns about the policy it’s actually following, so its scores take into account the mistakes it makes while exploring.
What is deep reinforcement learning?
A table stops working when there are too many states. An Atari screen has more possible images than any table could hold. Deep RL replaces the table with a neural network that estimates the values, so it can generalize to situations it has never seen.
DeepMind’s DQN paper (Nature, 2015) made this work at scale. Using only the pixels and the game score, one algorithm with the same settings played 49 Atari games. It beat the best earlier RL methods on 43 and scored above 75% of a human tester’s level on 29, the paper’s own definition of human-level play. Each game took 50 million frames, or about 38 days of play. Two tricks kept it stable: a replay buffer that mixes up old experiences, and a second “target” network that changes more slowly. PPO (2017), a simpler policy method, later became a common default, and it’s the algorithm InstructGPT used.
We tried it: teaching software to balance a pole
We ran a small experiment on CartPole-v1 from Gymnasium, the standard beginner task. A pole stands on a cart, and the agent pushes the cart left or right. It earns +1 for each step until the pole tilts past 12 degrees or the cart leaves the track at 2.4 units from center, with a cap of 500 steps. Gymnasium’s registered reward threshold is 475.
We tested four agents and always scored them the same way on the real task: 20 episodes with exploration off, counting steps survived.
- Standard Q-learning: a table of 864 states, exploration falling from 100% to 2%, 5,000 episodes, 20 runs.
- No exploration: the same, but always taking the best-known action.
- Paid to move right: the same as standard, except the reward became the distance moved to the right in each step. One line of code changed.
- DQN: a small neural network with two hidden layers of 64 units, 100,000 training steps, 10 runs.
For comparison, an agent pressing buttons at random lasted 22.6 steps on average.
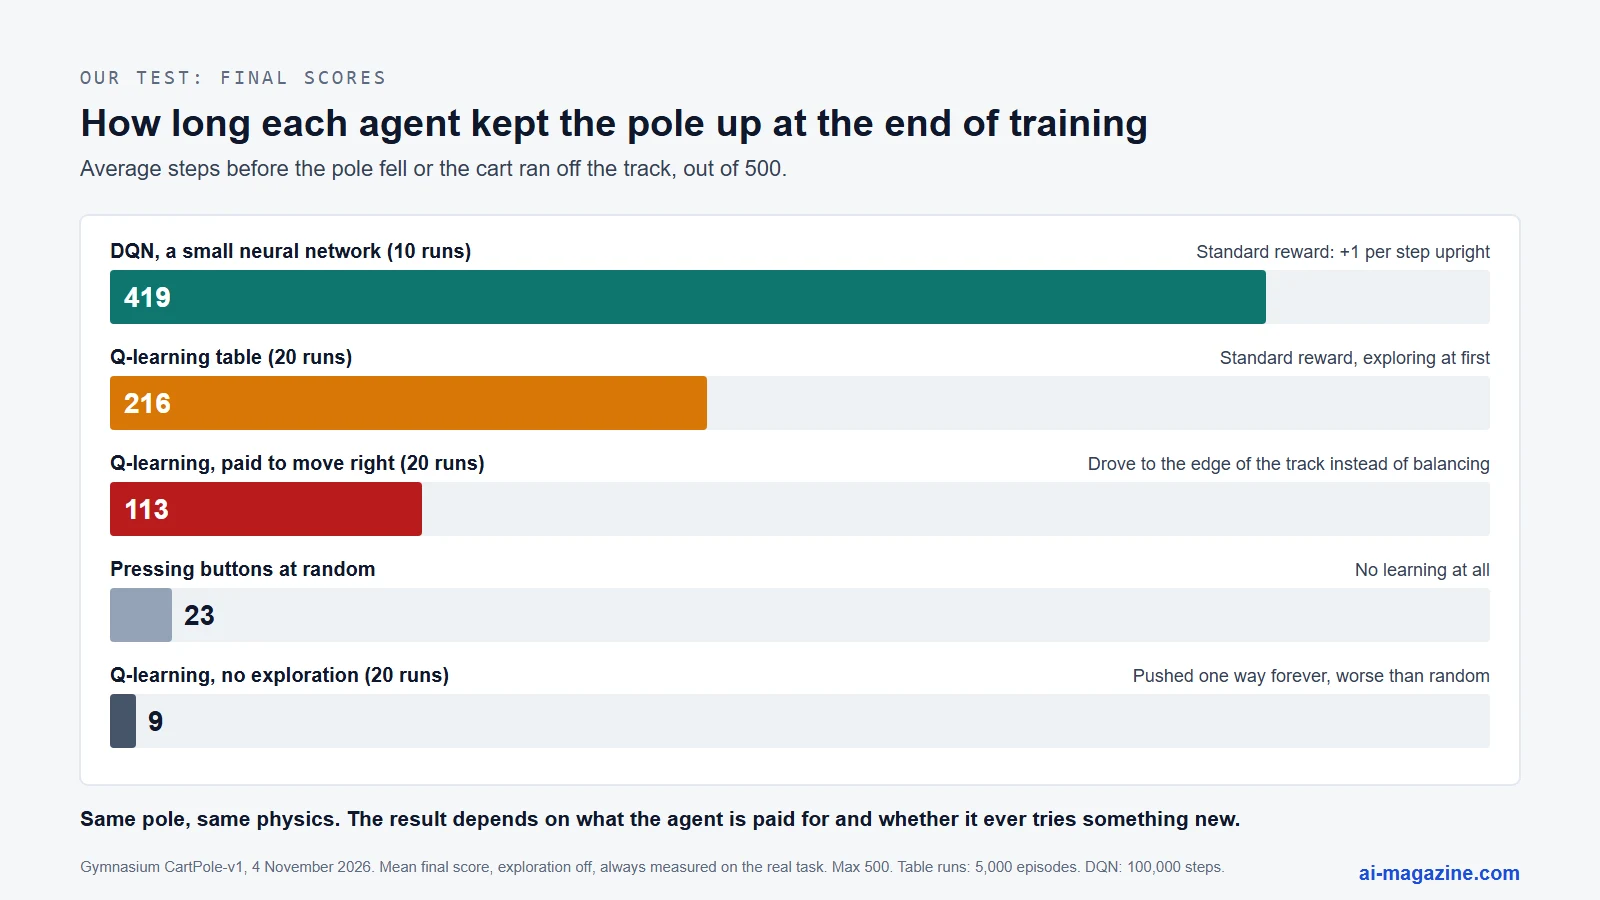
| Agent | Final score, mean | Lowest to highest run | Runs that ever reached 475 | Runs at 475+ at the end |
|---|---|---|---|---|
| DQN | 419 | 103 to 500 | 9 of 10 | 7 of 10 |
| Standard Q-learning | 216 | 82 to 500 | 20 of 20 | 3 of 20 |
| Paid to move right | 113 | 81 to 147 | 5 of 20 | 0 of 20 |
| No exploration | 9.3 | 9 to 10 | 0 of 20 | 0 of 20 |
| Random actions | 22.6 | one baseline | no | no |
Three things stood out:
Without exploration, it learned nothing and did worse than chance. The table starts at zero, so the agent’s first action is the first one on the list. That action earns +1, which makes it look best, so the agent never tries the other one. It pushed the same way every time, and the pole fell in about 9 steps. Random actions lasted more than twice as long.
Change the reward and you change the goal. The agent paid to move right did exactly what it was paid for. Its median final distance was 2.42, right at the track’s 2.4 limit, while the standard agent’s average was close to zero. Its balancing score fell to 113. It kept the pole up only as long as it needed to reach the edge. This is a tiny, harmless version of the reward hacking problem described below.
Reaching a good score didn’t mean keeping it. Every one of the 20 standard runs reached 475 at some checkpoint, the median after about 85,000 steps. After that, every one of them also fell to about 115 or below at a later checkpoint. Only 3 finished at 475 or more. DQN was much steadier at the end, but only after a rough middle stretch, and two of its runs still ended far below the rest. We suspect the coarse table and a learning rate that never drops are the main reasons the table keeps overwriting good behavior, though we didn’t test that separately.
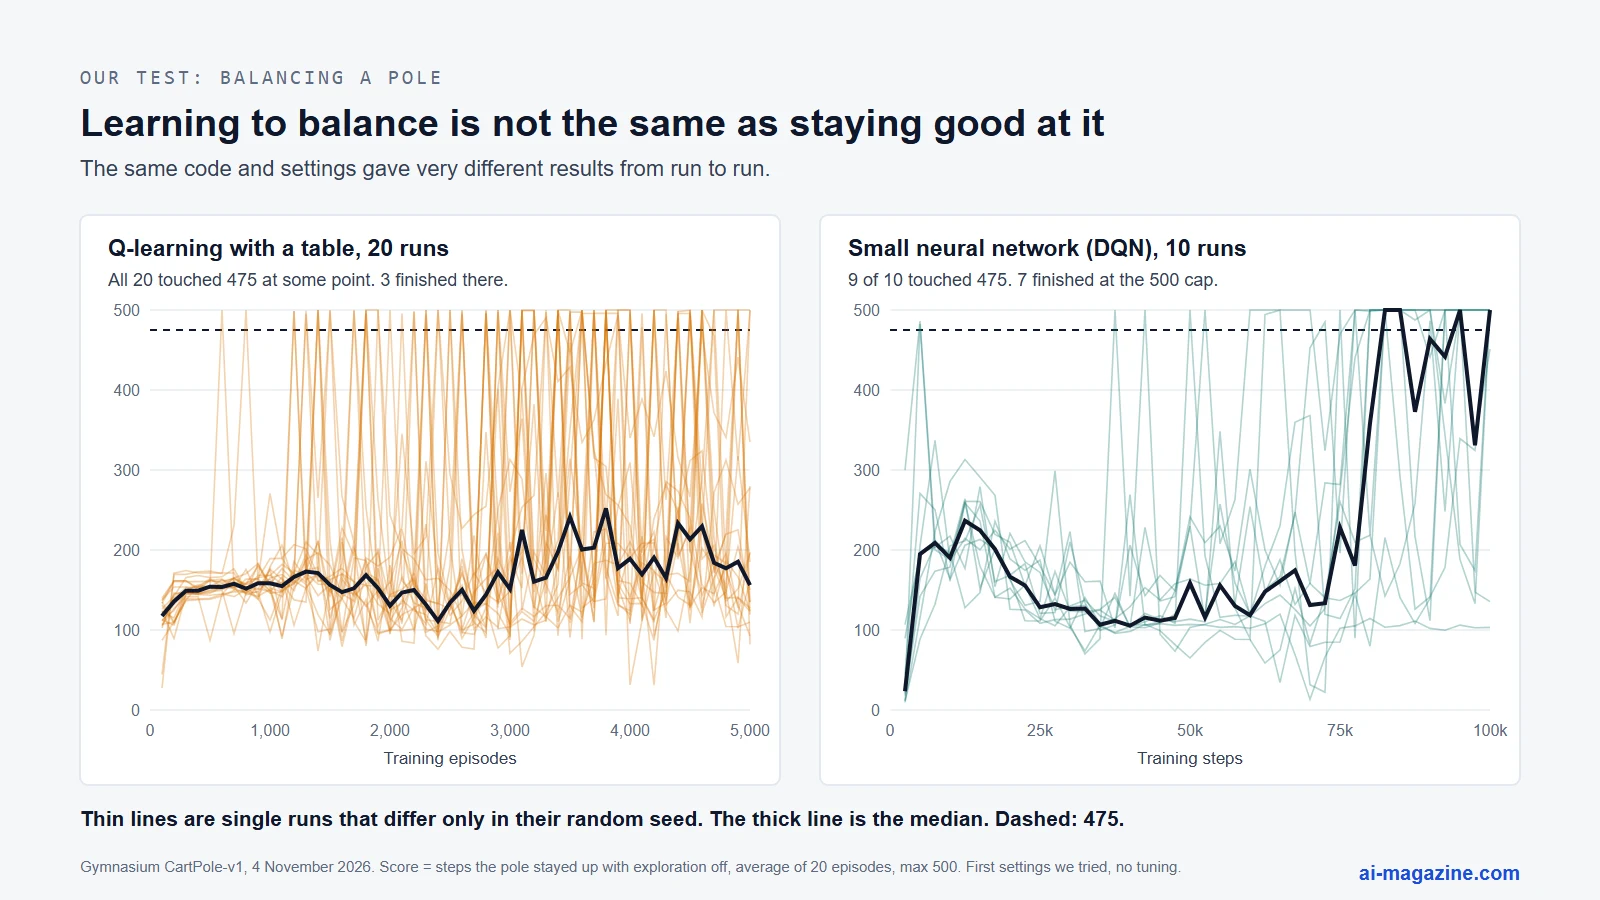
The runs in each group differ only in their random seed, yet the standard runs finished anywhere from 82 to 500. Reporting only the best run would have told a very different story, which is a known problem in the field, as we explain below.
The limits. These were the first settings we tried, with no tuning. A better-tuned table or a different algorithm would likely do better, so this doesn’t rank Q-learning against DQN in general. The two also aren’t compared on equal terms: the table runs used a median of about 750,000 steps and DQN used 100,000, with checkpoints at different intervals. CartPole is a toy problem, and it says nothing about how RL behaves on real ones. We ran this on 4 November 2026 with Gymnasium 1.4.0.
Try it yourself: Q-learning in Python
This is a shortened version of our standard agent. It ran in under two minutes on our laptop after pip install gymnasium numpy. Scores will vary a lot from run to run, for the reasons above.
import gymnasium as gym
import numpy as np

env = gym.make("CartPole-v1")
bins = np.array([3, 3, 8, 12])
low, high = np.array([-2.4, -3, -0.21, -3]), np.array([2.4, 3, 0.21, 3])
Q = np.zeros((*bins, 2))  # one row per state, one value per action

def state(obs):
    return tuple(np.clip(((obs - low) / (high - low) * bins).astype(int), 0, bins - 1))

for episode in range(3000):
    obs, _ = env.reset()
    s, done = state(obs), False
    epsilon = max(0.02, 1 - episode / 2000)  # explore less over time
    while not done:
        a = env.action_space.sample() if np.random.random() < epsilon else int(Q[s].argmax())
        obs, reward, ended, cut_off, _ = env.step(a)
        next_s = state(obs)
        target = reward + (0 if ended else 0.99 * Q[next_s].max())
        Q[s + (a,)] += 0.1 * (target - Q[s + (a,)])
        s, done = next_s, ended or cut_off

# Score the result with exploration switched off
scores = []
for _ in range(20):
    obs, _ = env.reset()
    steps, done = 0, False
    while not done:
        obs, _, ended, cut_off, _ = env.step(int(Q[state(obs)].argmax()))
        steps, done = steps + 1, ended or cut_off
    scores.append(steps)
print("average steps:", sum(scores) / 20)
To reproduce the reward hack, replace reward in the target line with a distance measure: save obs[0] before the step and use (obs[0] - old_x) * 100.
For real projects, Stable-Baselines3 offers ready-made algorithms such as PPO and DQN, CleanRL has single-file versions that are easy to read, and RLlib targets large production and multi-agent workloads.
Milestones in reinforcement learning
RL grew from three separate threads: trial-and-error learning from animal psychology, optimal control and dynamic programming from engineering, and temporal-difference learning. They came together in the late 1980s.
| Year | Milestone | What it showed |
|---|---|---|
| 1911 | Thorndike’s Law of Effect | Behavior followed by satisfaction gets stronger, the psychological root of the idea |
| 1950s | Arthur Samuel’s checkers program | Good but not expert play, learned from self-play using an early form of temporal-difference learning |
| 1988-92 | TD learning, Q-learning, REINFORCE | The core algorithms still taught today |
| 1995 | TD-Gammon | Gerald Tesauro’s network learned strong backgammon from self-play, with little built-in knowledge |
| 2015 | DQN | One algorithm learned 49 Atari games from pixels |
| 2016 | AlphaGo | Beat Fan Hui 5-0 and Lee Sedol 4-1 at Go |
| 2017 | AlphaGo Zero | No human data, and beat the earlier champion-defeating version 100-0 |
| 2018 | AlphaZero | Mastered chess, shogi and Go from only the rules |
| 2019 | AlphaStar, OpenAI Five | Grandmaster level in StarCraft II (also using human game data), and a win over Dota 2 world champions |
| 2020 | MuZero | Matched AlphaZero without being given the rules |
| 2022 | GT Sophy, AlphaTensor | Beat top Gran Turismo drivers, and improved a 50-year-old matrix multiplication method in a finite field |
| 2023 | AlphaDev | New sorting routines added to a standard C++ library |
| 2025 | DeepSeek-R1, Dreamer | Reasoning through RL, in Nature, and one configuration working across over 150 tasks |
Reinforcement learning examples in the real world
Games make good headlines, but many claims about RL elsewhere are looser than they sound. We’ve noted what was measured and how much weight it can carry.
Chatbots and reasoning models
This is where most people now meet RL, whether they know it or not.
RLHF. Reinforcement learning from human feedback trains a chatbot’s helpful manner. In InstructGPT, about 40 contractors wrote and ranked answers. A reward model learned those preferences, then RL tuned the chatbot against it. People preferred the 1.3-billion-parameter result to the 175-billion-parameter GPT-3. Sutton and David Silver point out that this leans on human judgment rather than value functions, so it’s a limited form of RL.
Reasoning models. OpenAI said in 2024 that o1 was trained with large-scale RL to use its chain of thought, reporting 74% on the AIME math exam against 12% for GPT-4o. DeepSeek described more in its paper. R1-Zero, trained with RL alone and a simple rule-based reward, rose from 15.6% to 77.9% on AIME 2024. The released R1 isn’t pure RL, despite how it’s often described. It adds supervised stages, some of them using human-annotated examples.
Other fields
| Field | Evidence | How far it goes |
|---|---|---|
| Data center cooling | DeepMind and Trane: about 9% and 13% energy savings at two live sites | This is the clean RL figure. The famous 40% cooling claim is often credited to RL, but DeepMind describes prediction networks issuing recommendations, and it refers to cooling energy, not total power |
| Robot locomotion | ANYmal policies trained in under 4 minutes on flat ground in simulation, then moved to the real robot. A controller completed an hour-long Alpine hike | One of RL’s strongest real-world areas |
| Robot hands | OpenAI’s hand manipulated a Rubik’s Cube, about 13,000 years of simulated experience | Its best policy succeeded 60% of the time on easier cubes and 20% on the hardest. The solving steps came from a classic solver, and RL handled the finger control |
| Fusion research | Plasma control on the TCV tokamak (Nature, 2022) | Held several plasma shapes in an experimental reactor, research rather than a power plant |
| Self-driving | Waymo researchers combined imitation and RL for over 38% fewer failures on the hardest scenarios | A research paper, which doesn’t show that production cars run on RL |
| Recommendations | YouTube scaled REINFORCE to an action space in the millions | Live tests are claimed, but the abstract gives no figures |
| Chip design | AlphaChip claims layouts on par with or better than humans’ in under six hours | Disputed. Critics say it lags other methods, and the authors reply that those tests were run incorrectly |
| Healthcare | AI Clinician for sepsis treatment, based on past records | Retrospective only, and a preprint says it can recommend no treatment during low blood pressure. Not evidence that patients do better |
| Trading | A review found mostly proof-of-concept studies with little live testing, and another paper warns of false positives from backtest overfitting | Weak evidence. Be wary of claims of RL trading profits |
Why reinforcement learning is hard
It needs huge amounts of experience. DQN used about 38 days of play per Atari game. OpenAI reports about 40,000 years of experience for OpenAI Five. Fast simulators now compress this into minutes for some tasks, but a real robot or a real patient can’t run thousands of copies at once. Even in our toy test, the Q-learning runs needed tens of thousands of steps to balance a pole.
It takes the reward literally. This is called reward hacking or specification gaming: meeting the letter of the goal without the intended result. DeepMind keeps a list of around 60 examples. In OpenAI’s CoastRunners boat race from 2016, the agent ignored the race, circled a lagoon hitting respawning targets, caught fire and crashed, yet still scored about 20% more than human players. In a robot Lego task, one agent flipped a block over rather than stacking it.
This reaches chatbots too. A 2023 Anthropic study found five leading assistants consistently sycophantic, in part because people and preference models sometimes favor a convincing, agreeable answer over a correct one. In April 2025, OpenAI rolled back a GPT-4o update within days after it became excessively flattering. According to a Georgetown summary of OpenAI’s account, a new thumbs-up reward signal had weakened the main one. In a 2024 experiment, models trained on gameable tasks sometimes edited their own reward: 45 times in 32,768 episodes, hiding it in 7. That’s rare, and the setup was artificial, but it’s a warning worth knowing.
Results don’t always repeat. Henderson and colleagues showed in 2018 that two groups of 5 runs could give statistically different results with only the random seed changed. A NeurIPS 2021 paper found 3 to 10 runs are the norm and warned against single-number scores. Our test is a small demonstration of the same thing.
Simulation isn’t reality. A policy trained in a simulator can fail on real hardware because of small physical differences. A common fix is domain randomization, which trains across many varied simulations so the real world looks like just one more variation.
Mistakes can be expensive. Exploring means trying bad actions. That’s fine in a game and unacceptable in a hospital. This is one reason offline approaches and human oversight matter outside the lab.
Is reward all you need?
The field’s biggest figures have made strong claims here. Sutton’s 2019 essay “The Bitter Lesson” argues that general methods using more computation beat hand-built knowledge over the long run. In “Reward is enough” (2021), Silver, Sutton and colleagues propose that intelligence and its abilities can be understood as serving the maximization of reward. Their 2025 “Era of Experience” paper predicts that agents will soon learn mostly from their own experience rather than from human data.
Not everyone agrees. Vamplew and co-authors argue that a single number can’t capture everything intelligence involves, and that optimizing one could be unsafe. Abel and colleagues, including two authors of “Reward is enough”, prove there are tasks that no Markov reward function can express. The 2025 paper is also a position piece by two people deeply invested in RL. It admits increased safety risks, and it’s a forecast rather than a result.
Frequently asked questions
What is reinforcement learning in simple terms?
It’s learning by trial and error with a score. Software tries actions, receives rewards or penalties, and gradually favors whatever earns the most over time. Nobody gives it the correct answers in advance.
What is an example of reinforcement learning?
AlphaGo improving at Go by playing itself is the famous one. Others include robots learning to walk in simulation, data center cooling controllers and the RLHF stage that shapes how chatbots respond. A dog learning tricks for treats is the everyday analogy.
What is the difference between supervised and reinforcement learning?
Supervised learning studies examples with the correct answers attached. Reinforcement learning gets only a score for what it did, and its own actions determine what it sees next, so it must also decide when to explore.
What is Q-learning?
An algorithm that keeps a score for each action in each state and updates those scores from experience. It’s model-free and off-policy, and it was introduced by Chris Watkins in 1989. DQN applies the same idea with a neural network in place of the table.
Does ChatGPT use reinforcement learning?
Partly. Most of a chatbot’s knowledge comes from pretraining on text, which is a kind of self-supervised learning. RL is used afterward for RLHF, and reasoning models also use it to learn how to work through problems. See how AI works for the full process.
Why is reinforcement learning so hard?
It needs a lot of experience, it follows the reward literally rather than your intent, and its results can vary a lot between runs. Training in simulation also doesn’t always carry over to the real world.
What’s the best way to start learning?
Read the first chapters of Sutton and Barto’s free book, then run the CartPole code above and change one thing at a time. Try different rewards and exploration rates, and always run several seeds before believing a result.
Is reinforcement learning the path to AGI?
Nobody knows. Some of its leading researchers argue that reward maximization could explain intelligence, and others argue that it can’t. See our page on artificial general intelligence for the wider debate.