AI glossary
Supervised vs Unsupervised Learning: Differences, Examples and an Experiment
Supervised learning is machine learning from labelled examples: each training input comes with the correct answer, and the model learns to predict that answer for new inputs. Unsupervised learning works with inputs only, no answers, and looks for structure on its own: groups of similar items, unusual items, or a simpler way to describe the data.
The classic textbook The Elements of Statistical Learning puts it in terms of a classroom. Supervised learning is “learning with a teacher” who provides the correct answer or tells the student how wrong they were. Unsupervised learning is “learning without a teacher”. The practical difference follows from that: supervised models can be scored against the right answers, while for unsupervised results, in the book’s words, “there is no such direct measure of success”.
Below: the differences in one table, the main algorithms, real systems that use each approach, the in-between methods that train today’s language models, and two experiments we ran to see when labels are worth paying for.
Supervised vs unsupervised learning at a glance
| Supervised learning | Unsupervised learning | |
|---|---|---|
| Training data | Inputs with correct outputs (labels) | Inputs only |
| Goal | Predict a known kind of answer for new data | Find structure: groups, anomalies, simpler representations |
| Typical tasks | Classification, regression | Clustering, anomaly detection, dimensionality reduction, association rules |
| Example algorithms | Logistic and linear regression, decision trees, gradient boosting, neural networks | k-means, hierarchical clustering, DBSCAN, PCA, Isolation Forest, autoencoders |
| Everyday example | Spam filter trained on emails marked “spam” or “not spam” | Grouping customers by behaviour without predefined segments |
| How you check it | Accuracy, precision, recall and similar scores on held-out labelled data | No ground truth; indirect scores and human judgement |
| Main cost | Collecting and checking labels | Interpreting results and deciding whether they are useful |
| Main risk | Learns the mistakes and biases in its labels | Finds patterns that are real but irrelevant, or not real at all |
In probability terms, Kevin Murphy’s textbook describes supervised learning as modelling p(y|x), the answer given the input, and unsupervised learning as modelling p(x), the data itself.
What is supervised learning?
A supervised model learns a mapping from inputs to outputs using a set of labelled data. Training is a loop: the model makes predictions on training examples, a loss function measures how far they are from the labels, and an optimiser such as gradient descent adjusts the model’s parameters to reduce that error. The trained model is then tested on examples it has not seen, to check that it learned the pattern rather than memorised the answers (see overfitting).
Supervised problems come in two kinds, as Christopher Bishop’s Pattern Recognition and Machine Learning defines them:
- Classification: the output is a category. Spam or not spam, which digit is in an image, whether a payment is fraud.
- Regression: the output is a number. A house price, tomorrow’s electricity demand, a delivery time.
Common supervised learning algorithms:
| Algorithm | Used for | Note |
|---|---|---|
| Linear and logistic regression | Regression; classification | Fast, easy to explain, a strong baseline |
| Decision trees and random forests | Both | Handle mixed data types; forests reduce overfitting |
| Gradient boosting (XGBoost, LightGBM) | Both | Usually the strongest choice for tabular data |
| Support vector machines | Mostly classification | Good on small, high-dimensional datasets |
| k-nearest neighbours | Both | No training step; predicts from the most similar labelled examples |
| Neural networks | Both | Dominant for images, audio and text |
Supervised learning examples:
- Spam filtering. Paul Graham’s 2002 essay A Plan for Spam described a filter trained on about 4,000 spam and 4,000 legitimate emails that missed fewer than 5 spams in 1,000 on his own mail, with no false positives. By 2019 Google said Gmail’s machine learning and rules blocked more than 99.9% of spam, phishing and malware. In our own phishing test, a filter trained on 2008 mail flagged 99.5% of 2008 spam and phishing but only 15% of real phishing from 2025.
- Payment fraud. Stripe’s Radar scores each payment with machine learning models trained on payment data from across the Stripe network, where past fraud provides the examples to learn from. Stripe describes more than 1,000 characteristics per transaction and a decision in under 100 milliseconds.
- Medical imaging. Google’s 2016 diabetic retinopathy study trained a network on 128,175 retinal images, each graded 3 to 7 times by a panel of 54 ophthalmologists and senior residents.
- Credit scoring, demand forecasting, speech recognition, image classification and most other production prediction systems.
What is unsupervised learning?
An unsupervised model gets data without answers. Bishop lists its main jobs: discovering “groups of similar examples within the data” (clustering), estimating how the data is distributed (density estimation), and projecting it into fewer dimensions for visualisation.
The main unsupervised tasks and algorithms:
| Task | What it does | Algorithms |
|---|---|---|
| Clustering | Groups similar items | k-means, hierarchical clustering, DBSCAN, Gaussian mixtures |
| Anomaly detection | Flags items unlike the rest | Isolation Forest, one-class SVM, autoencoders |
| Dimensionality reduction | Describes data with fewer variables | PCA, t-SNE, UMAP, autoencoders |
| Association rules | Finds items that occur together | Apriori, FP-growth |
| Topic modelling and embeddings | Finds themes in text, represents words as vectors | LDA, word2vec |
Many of these are old. Karl Pearson described the idea behind PCA in 1901. The standard k-means algorithm is often called Lloyd’s algorithm after Stuart Lloyd, whose Bell Labs manuscript is dated 1957 but was only published in 1982. Isolation Forest, a common anomaly detector, was introduced in 2008 on the idea that anomalies are easier to isolate than normal points.
Unsupervised learning examples:
- Customer segmentation. Square’s data team clustered retail sellers with k-means by how they used the product. The usual “elbow” heuristic suggested 3 clusters; after comparing how the features varied in each version, the team judged 4 more representative and used the segments for roadmap and marketing decisions.
- Defect detection in factories. When defects are rare and varied, a model learns only from images of good parts and flags anything that looks different. The public MVTec AD benchmark is built this way: its training images contain no defects at all.
- Market basket analysis. Association rule mining finds products bought together. The 1994 Apriori paper illustrates the idea with a hypothetical rule: 98% of customers who buy tyres and car accessories also get car servicing.
- Exploring data. Analysts use PCA, t-SNE or UMAP to plot high-dimensional data in two dimensions and see whether natural groups exist before deciding what to predict.
- Word embeddings and topic models. word2vec learned word vectors from 1.6 billion words of text with no labels; Latent Dirichlet Allocation finds topics in document collections.
Key differences, explained
1. Labels and their cost. Labels are usually the expensive part of supervised learning. ImageNet, the dataset behind the deep learning boom, contains more than 14 million annotated images and was labelled by about 49,000 crowd workers from 167 countries over several years, according to Hardt and Recht. Google’s last public price list, for a Vertex AI labelling service it shut down in October 2024, charged $35 per 1,000 image classification labels and $63 per 1,000 bounding boxes, per human labeller (Vertex AI pricing). Drawing one high-quality box for ImageNet’s competition took about 35 seconds, according to a 2017 study that cut it to 7 seconds with a faster clicking method. Expert labels cost far more: the retinopathy study above needed doctors to grade every image several times.
2. Evaluation. A supervised model has a score you can trust, as long as the test data is representative. An unsupervised result usually does not. The scikit-learn documentation notes that the scores which compare clusters with true classes need labels: the Rand index, for example, “requires knowledge of the ground truth classes which is almost never available in practice”. The scores that need no labels are generally higher for convex clusters, so they favour some cluster shapes over others. Jon Kleinberg proved in 2002 that no clustering method can satisfy three natural-sounding requirements at once. In Murphy’s words, “there is no correct number of clusters”.
3. What you get out. A supervised model answers the question you asked. An unsupervised model answers a question you did not quite ask: it shows what is similar or unusual according to the features and distance you chose. Someone still has to decide what the groups mean.
4. Human input. Neither approach is free of human choices. Supervised learning needs people to label. Unsupervised learning needs people to choose features, the number of clusters, the distance measure, and to judge whether the output makes sense, as Square’s choice of 4 clusters over 3 shows.
5. New patterns. A supervised model learns the categories in its labels and nothing else. Unsupervised methods can flag things nobody labelled yet, such as a new kind of fraud. Andrea Dal Pozzolo’s thesis on card fraud notes that unsupervised techniques “usually generate too many false alerts”, so practitioners often combine both.
Our experiment 1: how many labels does supervised learning need to beat clustering?
We used the scikit-learn handwritten digits dataset: 1,797 small images of digits 0 to 9. We split it 70/30 into training and test images 20 times with different random seeds, and compared three approaches, all scored on the same test images:
- Supervised: logistic regression trained on 1, 2, 3, 5, 10, 20 or 50 randomly chosen labelled images per digit, or on all of them (about 126 per digit).
- Unsupervised, then a little labelling: k-means split all training images into 10 clusters with no labels. A person then labels only the image closest to the centre of each cluster, 10 labels in total, and every image in that cluster gets that label.
- Semi-supervised: label spreading, which uses the same few labelled images as the supervised model plus all the unlabelled training images.
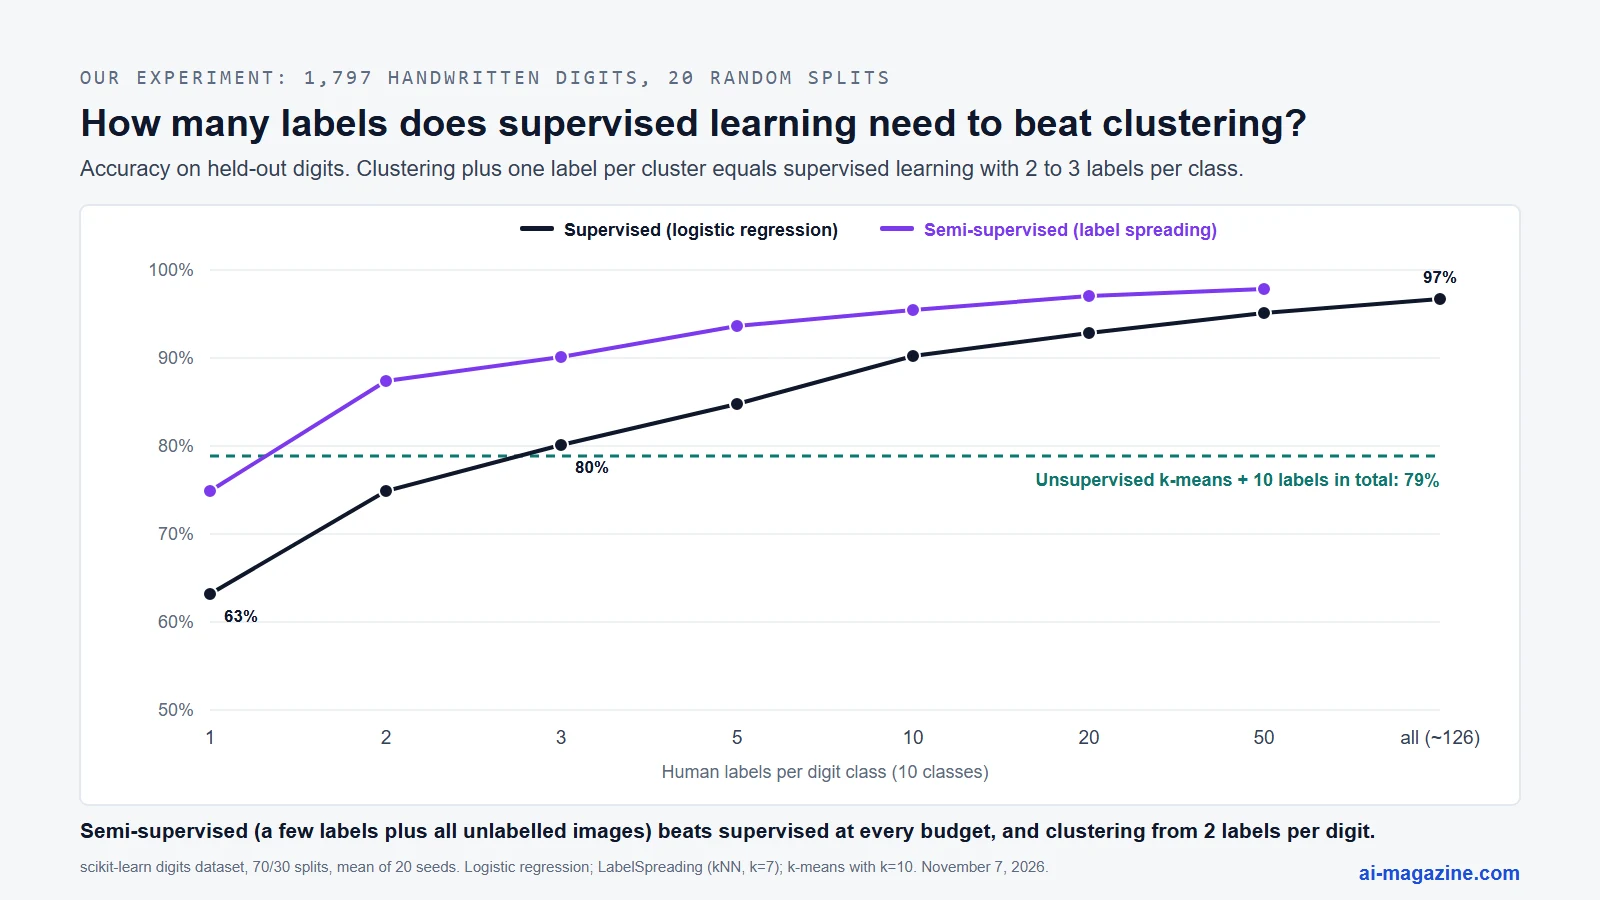
| Labels per digit | Supervised | Semi-supervised | Clustering + 10 labels |
|---|---|---|---|
| 1 (10 in total) | 63% | 75% | 79% |
| 2 | 75% | 87% | |
| 3 | 80% | 90% | |
| 5 | 85% | 94% | |
| 10 | 90% | 95% | |
| 50 | 95% | 98% | |
| All (~126) | 97% |
What we found:
- With the same 10 labels, clustering won clearly. Ten random labels gave the supervised model 63%. Ten labels placed on cluster centres gave 79%. The clusters did most of the work; the labels only named them.
- Supervised learning needed about 3 random labels per digit (30 in total) to beat clustering, and kept improving with more labels, reaching 97% with all of them. Clustering stays at 79% however much you label, because some clusters mix two digits. In one split, one cluster held 31 ones and 27 eights among the test images.
- The combination beat both from 2 labels per digit. Semi-supervised label spreading, using a few labels plus the unlabelled images, beat the supervised model at every label budget we tried, and beat clustering once it had 2 labels per digit (87%). With 5 labels per digit it scored 94%, close to the fully supervised model trained on 25 times as many labels.
Clustering is not an accurate classifier on its own here: with the best possible naming of clusters it reached the same 79%. The value is in labelling smarter, not in skipping labels.
Our experiment 2: catching card fraud with and without labels
Fraud is where the choice between the two approaches is a real business decision: confirmed fraud cases are rare, and new schemes appear all the time. We used the public credit card fraud dataset from Worldline and the Université Libre de Bruxelles: 284,807 card payments made by European cardholders over two days in September 2013, of which 492 (0.17%) are fraud. The features are anonymised, so the models see only numbers.
We held out 30% of the payments (85,443, including 148 frauds) for testing and compared:
- Unsupervised: Isolation Forest, trained on all training payments with no labels at all. It flags whatever looks most unusual.
- Supervised: gradient boosting trained on all legitimate training payments plus 5, 10, 20, 50 or 100 randomly chosen confirmed frauds, or all 344. Each small sample was drawn 10 times.
We scored each model the way a fraud team works: it can review only so many alerts a day. With a budget of 148 alerts, the number of frauds in the test set, how many real frauds land in the top 148? Flagging payments at random would find fewer than one.
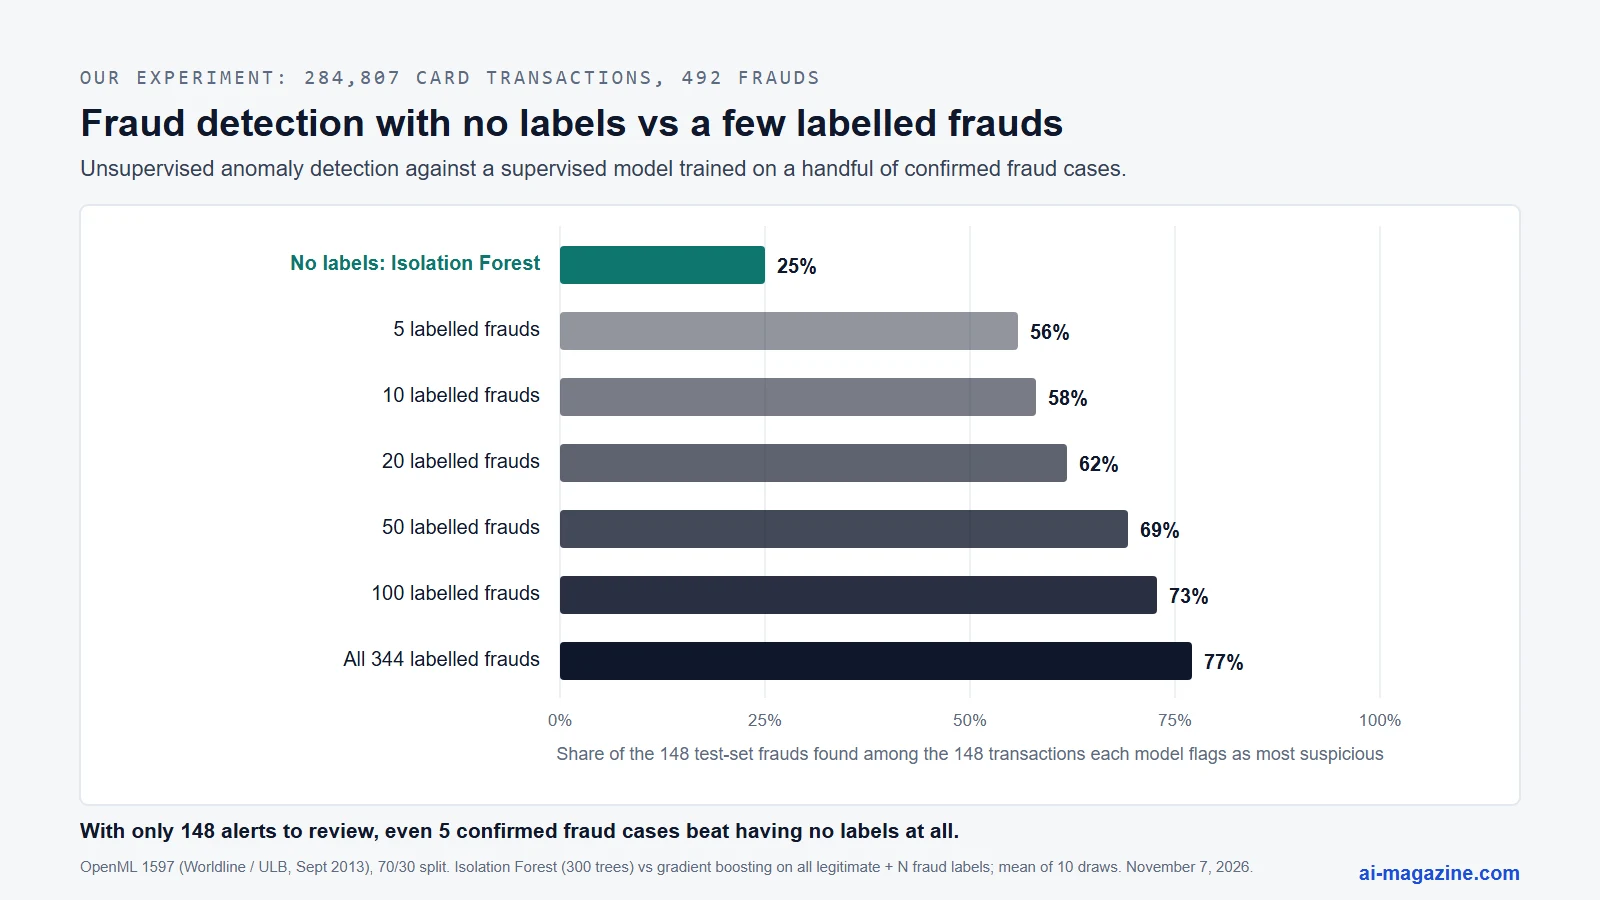
| Training labels | Frauds found in top 148 alerts | Frauds found in top 1,480 alerts |
|---|---|---|
| None (Isolation Forest) | 25% | 67% |
| 5 confirmed frauds | 56% (43% to 64% depending on which 5) | 59% |
| 10 | 58% | 65% |
| 20 | 62% | 72% |
| 50 | 69% | 75% |
| 100 | 73% | 80% |
| All 344 | 77% | 91% |
What we found:
- A handful of labels changed everything when alerts were scarce. With just 5 confirmed frauds, the supervised model found on average more than twice as many frauds in its top 148 alerts as the unsupervised one, and at least 1.7 times as many in every draw.
- With a bigger review budget, no labels beat a few labels. At 1,480 alerts, about 1.7% of the test payments, Isolation Forest found 67% of frauds, more than the models trained on 5 or 10 frauds (59% and 65%). A model that has seen five frauds recognises their pattern very well and other patterns poorly. The anomaly detector catches anything unusual, more broadly but less precisely. In three of the 5-fraud draws we checked, Isolation Forest caught 18 to 41 frauds in its top 1,480 that the supervised model missed.
- Few labels made results a lottery. Depending on which 5 frauds the model happened to learn from, it found between 43% and 64% of frauds in the top 148. The spread stayed wide up to 20 labelled frauds (34% to 70% with 10) and narrowed only from 50 upwards (70% to 76% with 100).
- All the labels still won clearly: 77% in the top 148 and 91% in the top 1,480.
A plain logistic regression trained the same way gave a similar picture: 43% with 5 labelled frauds, 77% with 100, and 78% with all of them. That fits the advice in Dal Pozzolo’s thesis: anomaly detection on its own raises too many false alerts, but it finds frauds that labelled examples have not taught a model to look for, so teams use both.
Semi-supervised, self-supervised and reinforcement learning
The two categories are the ends of a spectrum. Most modern systems sit somewhere in between.
| Approach | Labels used | Example |
|---|---|---|
| Supervised | All examples labelled by people | Spam filter, image classifier |
| Semi-supervised | A few labelled examples plus many unlabelled ones | Label spreading in our experiment |
| Weakly supervised | Noisy labels from rules or heuristics instead of hand labels | Snorkel |
| Self-supervised | Labels created automatically from the data itself | Predicting the next or a masked word |
| Unsupervised | None | k-means, PCA |
| Reinforcement learning | No labels; a reward signal from trial and error | Game-playing agents, RLHF |
Weak supervision. In the Snorkel study, experts wrote labelling rules instead of hand-labelling and built models 2.8 times faster than with seven hours of manual labelling, with predictive performance 45.5% higher on average. Across tasks Snorkel came within an average of 3.6% of models trained on large hand-labelled sets.
Self-supervised learning turns unlabelled data into a supervised task: hide part of the input and predict it. BERT hides 15% of the tokens (words or word pieces) in each training passage and learns to predict them, according to its paper. GPT-style models predict the next word. Murphy’s textbook calls self-supervised learning “a recently popular approach to unsupervised learning”, because nobody labels anything, but the training itself is supervised in form.
Reinforcement learning is neither. Sutton and Barto’s standard textbook calls it “a third machine learning paradigm, alongside supervised learning and unsupervised learning”: the model learns from rewards, not labels or structure.
Yann LeCun’s well-known cake analogy sums up how much information each approach gets. In his 2017 slides, reinforcement learning is the cherry (“a few bits for some samples”), supervised learning the icing (“10→10,000 bits per sample”), and unsupervised or predictive learning the sponge itself (“Millions of bits per sample”). He later said he prefers the term “self-supervised” for that layer (Synced).
How ChatGPT-style models use all three
Large language models are often described as unsupervised. That is only true of the first stage, and even that is better called self-supervised.
- Pretraining (self-supervised): the model learns to predict the next token on huge amounts of text. No one labels anything.
- Supervised fine-tuning: people write example answers. For InstructGPT, the 2022 OpenAI model whose training method ChatGPT reused, about 40 contractors produced the data, with around 13,000 training prompts for this stage (paper). Meta’s Llama 2 used 27,540 such annotations (paper).
- Reinforcement learning from human feedback: people rank several answers; a reward model learns their preferences; reinforcement learning tunes the model. Llama 2 used more than 1.4 million human comparisons. OpenAI reported that people preferred answers from a 1.3-billion-parameter InstructGPT model over those of the 175-billion-parameter GPT-3.
So the most capable AI systems today combine self-supervised learning at scale with a relatively small amount of expensive human supervision.
When to use supervised vs unsupervised learning
Use supervised learning when:
- You know exactly what you want to predict, and it can be written down as a label or a number.
- You have labelled examples, or can afford to create enough of them.
- You need a measurable accuracy before going live.
Use unsupervised learning when:
- You don’t yet know what categories exist, and want to explore.
- Labels are impossible or too expensive, or the thing you are looking for is rare and changes (new fraud, new defects).
- You need to compress, visualise or clean data before another model uses it.
Use both when you have lots of data and few labels. Cluster first to see what is there, then label a few examples per cluster; or use semi-supervised methods; or use unsupervised anomaly scores as an extra input to a supervised model. Our experiments point the same way: a few labels go a long way, unlabelled data still catches what the labels miss, and the best results come from using both.
Common myths
“Unsupervised learning needs no human input.” People choose the features, the algorithm, the number of clusters and the distance measure, and then decide what the results mean. The Elements of Statistical Learning says that for unsupervised results “one must resort to heuristic arguments”.
“Clustering finds the true categories.” It finds groups according to the features and distance you chose. Our k-means put many ones and eights in the same cluster. As Murphy puts it, there is no correct number of clusters.
“Supervised learning is always more accurate.” Only when there are enough good labels. With 10 labels, clustering beat the supervised model in our digit test, and with a large review budget our unlabelled fraud detector beat models trained on 5 or 10 frauds. Labels can also be inconsistent: in the InstructGPT project, labellers agreed with each other only about 73% to 77% of the time when ranking answers.
“ChatGPT was trained with unsupervised learning.” Its base model was pretrained with self-supervised next-word prediction, then fine-tuned with supervised examples and human feedback.
“Reinforcement learning is a type of unsupervised learning.” Sutton and Barto treat it as a separate, third paradigm: it learns from rewards.
“Arthur Samuel defined machine learning as learning without being explicitly programmed.” The line is widely attributed to his 1959 checkers paper, but it does not appear in the paper itself. It is a later paraphrase.
“Data mining discovered that Walmart shoppers buy beer with diapers.” The story traces back to a 1992 analysis for the Osco Drug chain, and the shelves were reportedly never rearranged. The Walmart version is almost certainly a myth.
How we ran the experiments
- Digits: scikit-learn’s digits dataset (1,797 8x8 images, the test part of the UCI handwritten digits set), pixel values scaled to 0-1. 20 random stratified 70/30 splits. Logistic regression (scikit-learn defaults, max_iter raised to 3,000); LabelSpreading with a 7-nearest-neighbour kernel; k-means with 10 clusters and 10 restarts. Numbers are means over 20 splits; the standard deviation was about 5 points for supervised learning with 1 label per digit and about 1 point for clustering.
- Fraud: the public credit card fraud dataset (OpenML 1597; the full copy we used is the one Google hosts for its TensorFlow tutorials; its MD5 hash matched the one Google Cloud Storage reports for the file, and its row and fraud counts match OpenML), all 30 features standardised. One stratified 70/30 split. Isolation Forest with 300 trees; scikit-learn HistGradientBoostingClassifier and LogisticRegression, both with balanced class weights, trained on all 199,020 legitimate training payments plus the sampled frauds; 10 random draws for each sample size below the full 344. “Found in top N” counts real frauds among the N test payments with the highest fraud score.
- Limits: both datasets are small public benchmarks, and stronger models exist for each approach. The results show the trade-off, not the best possible score. Code run on November 7, 2026.
Frequently asked questions
What is the main difference between supervised and unsupervised learning?
Supervised learning trains on examples that include the correct answer and learns to predict it. Unsupervised learning trains on data without answers and finds structure, such as groups or anomalies.
What are examples of supervised and unsupervised learning?
Supervised: spam filters, fraud scoring, medical image diagnosis, price prediction. Unsupervised: customer segmentation, defect detection from images of good parts only, market basket analysis, visualising data with PCA or t-SNE.
Is k-means supervised or unsupervised?
Unsupervised. It groups data into a chosen number of clusters without any labels. k-nearest neighbours, which sounds similar, is supervised.
Is regression supervised or unsupervised?
Supervised. Regression predicts a number from labelled examples. Logistic regression, despite its name, is a supervised classification method.
Is deep learning supervised or unsupervised?
It can be either. Deep learning describes the model, a neural network with many layers, not how it is trained. Image classifiers are usually supervised; autoencoders are unsupervised; language models are pretrained with self-supervised learning.
Which is better, supervised or unsupervised learning?
Neither in general. Supervised learning is more accurate when you have enough good labels and a clear target. Unsupervised learning is the only option without labels and can find patterns nobody has labelled yet. Many practical systems combine them.
What is semi-supervised learning?
Training with a small amount of labelled data and a large amount of unlabelled data. In our digit test, it beat purely supervised training at every label budget we tried.