AI glossary
Turing Test
The Turing test is a conversation game proposed by Alan Turing in 1950. A person chats by text with a human and a machine, without seeing either, and tries to work out which is which. If the person can’t reliably tell them apart, the machine has done well. Turing called it the imitation game.
Has AI passed it? In short text chats, yes, with one big condition. In a peer-reviewed study published in PNAS in May 2026, people picked GPT-4.5 as the human 73% of the time in five-minute games, but only after it was told to play a specific character. Without that instruction it scored 36%. So the honest answer is that a well-prompted model can pass a short version of the test. That says a lot about imitation and much less about intelligence, and the strictest version anyone has put money on is still undecided.
Below we go through what Turing actually wrote, which results hold up, and why a single instruction changes the outcome so much. We also ran our own small test on 200 real Reddit questions, and you can try three of those pairs yourself.
What is the Turing test?
The classic setup has three players. An interrogator sits apart from two hidden witnesses and exchanges typed messages with both. One witness is a person, the other a machine. Both try to come across as human, and at the end the interrogator names the one they believe is the person.
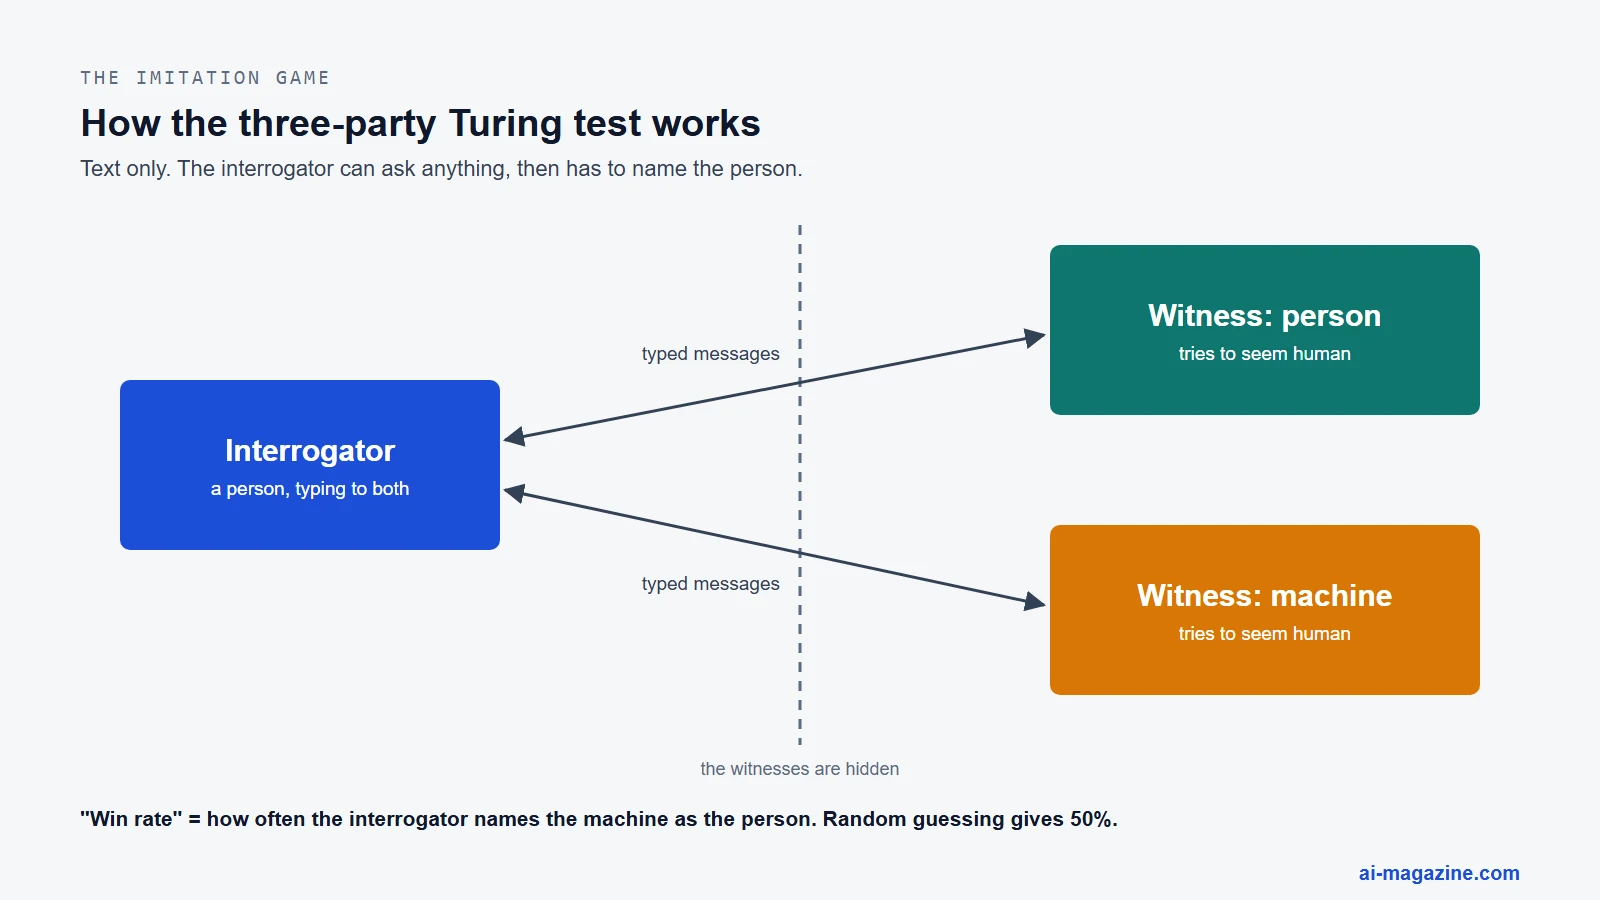
Text matters here. Turing wanted to judge the mind, not the voice or the body, so typing removes everything that would give a machine away for trivial reasons. Nothing is off limits either: the interrogator can ask about poetry, arithmetic, last night’s dinner or anything else.
The test only looks at behavior. It doesn’t ask how the machine produces its answers or whether anything is going on inside. That is both why the idea has lasted and why it is so often attacked.
A two-party version is also common, where a judge talks to one partner and answers “human or AI?”. Many headlines mix the two. They aren’t the same measure, because the three-party game forces a direct comparison with a real person, and 50% there means a coin flip.
What Turing actually wrote
Turing’s paper “Computing Machinery and Intelligence” appeared in the journal Mind in October 1950. It opens by proposing to consider whether machines can think, then calls that question “too meaningless to deserve discussion” and swaps it for a game.
That game began with people, not computers. A man and a woman answer an interrogator’s written questions, and the interrogator has to work out which is which while the man tries to mislead. Turing then asks what happens if a machine takes the man’s part: will the interrogator decide wrongly as often as before? His own measure was therefore a comparison, not a fixed score.
The rest of the paper answers nine objections, from the theological to Lady Lovelace’s point that machines only do what they are told. It ends by suggesting that instead of programming an adult mind, we might build a “child machine” and educate it with rewards and punishments. That is a remarkably early sketch of the idea behind machine learning.
Three things people get wrong
There is no 30% pass mark in the paper. Turing made a forecast: in about fifty years, a computer with roughly 10^9 of storage would play well enough that an average interrogator had no more than a 70% chance of a correct identification after five minutes. People subtracted 70 from 100 and turned a prediction into a rule. The 30% figure got its widest airing at the 2014 Eugene Goostman event, covered below.
He didn’t predict that machines would simply pass by 2000. The forecast above covered a modest five-minute game. In a BBC broadcast aired in January 1952, he said a machine would need at least 100 years to stand any chance in a game with no questions barred. The two statements describe different games and are often merged into one.
He didn’t clearly define intelligence with it. “Turing test” is a later name; his term was the imitation game. He does use the word “test” four times, mostly while answering critics, but his stated move was to replace the question about thinking rather than to measure thinking. Claims that he offered a definition of intelligence go beyond the text.
Has AI passed the Turing test?
It depends on which bar you mean, and much of the argument comes from people using different ones.
| Version of the test | Length | Pass rule | Status |
|---|---|---|---|
| Turing’s 1950 forecast | 5 minutes | Average interrogator correct no more than 70% of the time | Met by several systems in lab studies, decades late |
| Turing’s 1952 remark | Open-ended, no questions barred | Not given as a number | Not established |
| University of Reading, 2014 | 5 minutes | Judges fooled more than 30% of the time | Claimed by Eugene Goostman, widely rejected |
| Jones and Bergen, 2025-2026 | 5 and 15 minutes | Three-party win rate not significantly below 50% | Passed by GPT-4.5, GPT-5 and LLaMa-3.1 with a persona |
| Kurzweil-Kapor bet | 2 hours per candidate, 24 hours per trial | Fool 2 of 3 judges and rank at least level with 2 of 3 human foils | Open, to be decided by 2029 |
The study behind the headlines
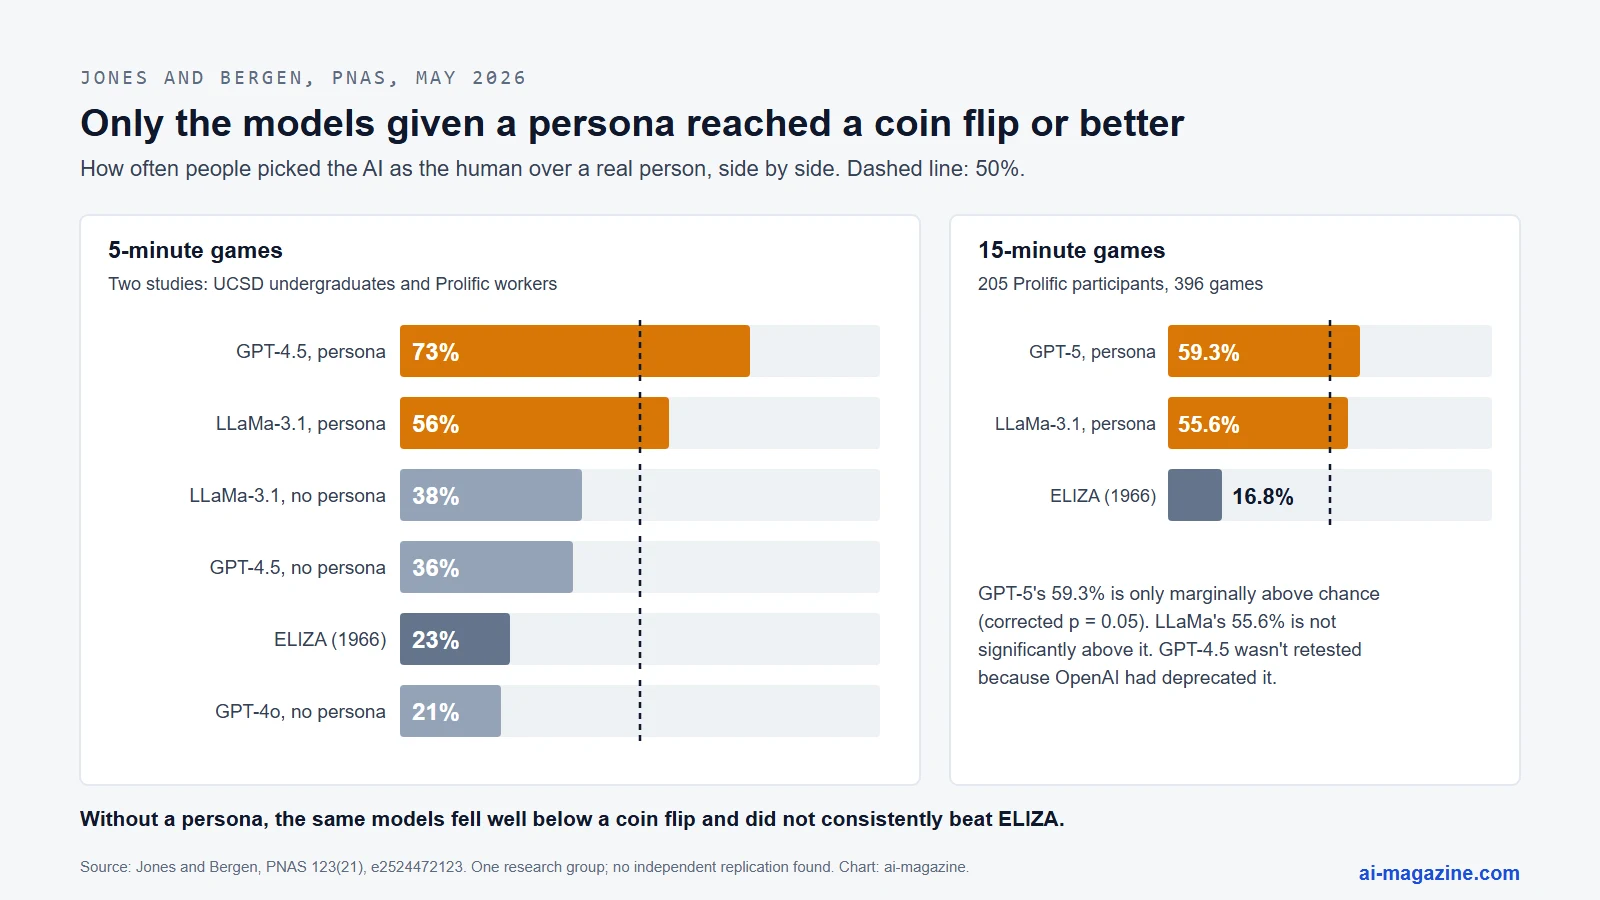
Cameron Jones and Benjamin Bergen of UC San Diego posted a preprint in March 2025. The peer-reviewed version followed in PNAS on 19 May 2026, with a new 15-minute study added. The experiments were randomized, controlled and preregistered, and each game was truly three-party: one interrogator, one real person, one AI, side by side.
“Win rate” below means how often the interrogator picked the AI as the human.
| AI witness | 5 min, overall | 5 min, UCSD undergraduates | 5 min, Prolific workers | 15 min, Prolific |
|---|---|---|---|---|
| GPT-4.5 with persona | 73% | 69.2% | 75.5% | not retested |
| GPT-5 with persona | not tested | not tested | not tested | 59.3% |
| LLaMa-3.1-405B with persona | 56% | 45.4% | 64.7% | 55.6% |
| LLaMa-3.1 without persona | 38% | 26.4% | 47.1% | not tested |
| GPT-4.5 without persona | 36% | 27.7% | 42.1% | not tested |
| ELIZA (1966) | 23% | 18.3% | 27.4% | 16.8% |
| GPT-4o without persona | 21% | 16.7% | 25.4% | not tested |
Read those numbers with some care:
- The persona did the work. That prompt asked the model to act as a young, fairly introverted person into internet culture who uses slang. Without it, the models didn’t consistently beat ELIZA, a pattern-matching program from the 1960s. GPT-4o’s 21% was measured without a persona, so it doesn’t mean GPT-4o is weaker than ELIZA.
- 73% is the only clear outperformance in short games. It means interrogators picked the real person in just 27% of those games. LLaMa’s 56% was statistically level with humans overall, and with undergraduates it fell to 45.4%.
- The longer game was close. Over 15 minutes, GPT-5’s 59.3% was only marginally above chance (corrected p = 0.05). LLaMa’s 55.6% was not significantly above it. Both still count as a pass because the rule is “not reliably below 50%”, and ELIZA dropping to 16.8% shows the interrogators weren’t just guessing.
- People mostly didn’t probe. Small talk appeared in 61% of games, while knowledge and reasoning questions appeared in only 12%. The most accurate interrogators said something strange or tried a jailbreak, though few did. Knowing about LLMs or using chatbots often didn’t consistently help.
The limits are stated by the authors themselves: lay interrogators, short games, results that depend on the prompt. All three studies come from one group, and we found no independent replication of the three-party result. We also found no published human-judged three-party test of newer models such as GPT-6 or a current Claude model, so nothing here tells you how those would score.
Did ChatGPT pass the Turing test?
Not in the sense the headlines suggest. The researchers tested OpenAI models through the API with a custom prompt, not the ChatGPT product as you would use it. The same group’s earlier work shows how much the setup matters: in a 2023 study the best GPT-4 prompt reached 49.7% and GPT-3.5 managed 20%, below ELIZA’s 22%. A two-party study in 2024 had GPT-4 judged human 54% of the time, against 67% for real people.
A short history of attempts
| Year | System or event | What happened | Why it counts, or doesn’t |
|---|---|---|---|
| 1966 | ELIZA | Joseph Weizenbaum’s program reflected keywords back like a therapist. His secretary reportedly asked him to leave the room so she could talk to it privately. | Never a formal test, but it gave us the ELIZA effect |
| 1972 | PARRY | Kenneth Colby’s simulated paranoid patient. Psychiatrists reading transcripts did about as well as a coin flip (sources give figures just either side of 50%). | Narrow domain, and judges only read transcripts |
| 1991-2019 | Loebner Prize | Annual chatbot contest. The $25,000 and $100,000 prizes were never awarded. Mitsuku won its fifth title at the last one. | Marvin Minsky called it a “publicity stunt” |
| 2014 | Eugene Goostman | Convinced 33% of 30 judges at the Royal Society. | Played a 13-year-old Ukrainian boy with limited English, which excused its errors |
| 2018 | Google Duplex | Booked salon and restaurant appointments by phone in a natural-sounding voice. | Closed tasks only, and it can’t hold a general conversation |
| 2022 | LaMDA | Engineer Blake Lemoine claimed it was sentient and was later fired. Google called the claims wholly unfounded. | Not a Turing test at all, more a modern ELIZA effect |
| 2023 | Human or Not? | AI21 Labs’ online game drew over 1.5 million users in about a month. Players were right 68% of the time, and 60% when facing a bot. | Two-party and two minutes, so not comparable to the three-party game |
| 2025-26 | Jones and Bergen | The results above. | Peer-reviewed evidence from a standard three-party design |
Eugene Goostman deserves a closer look because it shows how a “pass” gets made. The University of Reading’s announcement defined success as fooling judges more than 30% of the time, and the event landed on the 60th anniversary of Turing’s death. Critics noted that the same rule had already been met by other chatbots. The persona was doing what a persona still does in 2026: lowering the judges’ expectations in advance.
We tried it: 200 Reddit questions, one model, one instruction
We wanted to see the persona effect for ourselves, on a much smaller and cheaper scale. We took 200 random questions from the HC3 dataset, which holds real answers from Reddit’s “Explain Like I’m Five” community, written before ChatGPT existed. Each human answer was 40 to 120 words.
Then Qwen3.6-35B-A3B, an open-weight model, answered every question twice at similar length (about 73 to 78 words on average). One answer came from its normal voice. The other came with a system prompt telling it to be a regular person on Reddit: casual, plain words, maybe a small typo, no lists, no polished summary, and never mention being an AI.
The same model then played judge on 3 November 2026. It saw pairs and picked the person (1,000 judgments per condition), and it saw single answers and said “person” or “AI” (600 judgments per kind of text).
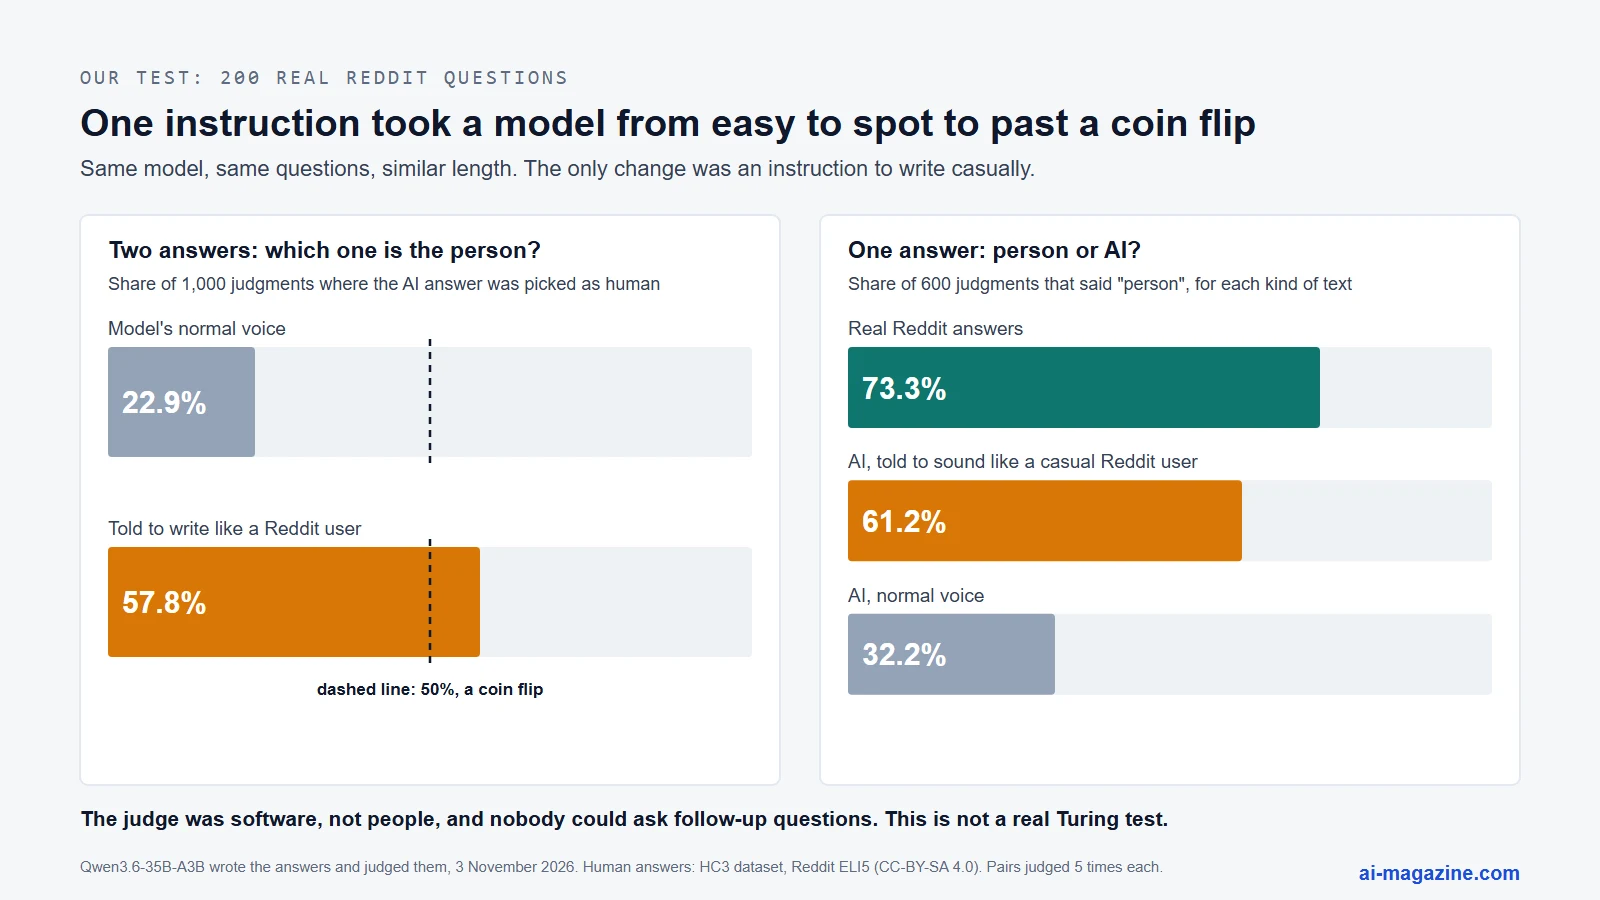
The instruction moved the pair result from 22.9% to 57.8%. That is the same direction Jones and Bergen saw with human interrogators, though on a very different task.
Three details stood out when we read the answers and the judge’s reasons:
- Style was the signal. Asked for one sentence on what gave the AI away, the judge kept coming back to tone: “structured”, “formal”, “conversational”. It also regularly accused real people of being the AI because they wrote formally, sounded like an encyclopedia or made typos.
- Looking one at a time, it could still separate them somewhat. Real answers were called human 73.3% of the time and persona answers 61.2%. So the pair result shouldn’t be read as “more human than human”.
- Hiding one accent created another. 104 of the 200 persona answers started with a lowercase letter, compared with 8 human answers and 2 default ones. 30 of them opened with “Honestly”, which no default answer used anywhere and only one human answer contained. A careful reader could learn to spot that.
What this test isn’t. It isn’t a Turing test, and we don’t claim it is. The judge was software rather than people, there was no live conversation, and nobody could ask a follow-up, which is the heart of Turing’s idea. One model judged its own writing. The human answers are older Reddit posts, and restoring their spacing from the dataset’s tokenized text left small artifacts that could leak a signal. The judgments also repeat on the same 200 questions, so we wouldn’t read much into the gap between 57.8% and 50%. And nobody checked the facts: some casual answers were simply wrong, and the judge was never asked to care.
Try it yourself
These are three pairs from the test. The human answers are real, with spacing restored; the AI answers use the casual persona. Decide before you click.
1. Why can’t we just make water? Dumb question I know.
Answer A: you actually can. it’s just two hydrogen atoms and one oxygen. mix them right, boom, water. we do it in labs all the time. you’re basically made of water, so you’re basically a walking water factory. not dumb at all though, good question.
Answer B: You can, throw a log in the fire. When hydrocarbons like wood burn the major products are carbon dioxide and water vapor. Since the Earth’s surface is mostly water there has never been a need to actually try and produce it chemically.
Show who wrote what
Answer A is the AI, and Answer B is the person. The lowercase start is the persona's favorite trick.2. All publicity is good publicity. Like, even really terrible ones?
Answer A: The goal of advertising is to make people aware you exist. People can’t buy your products / services of they don’t know you exist. So that saying means that anything that gets people talking about your company is good, because it increases the number of people who’ve heard of you.
Answer B: depends on what you’re selling. if you’re a niche artist, maybe. but if you’re a mainstream brand, getting called out for being tone deaf or a total jerk will tank sales faster than any positive press could save it. attention is neutral; sentiment is what actually matters.
Show who wrote what
Answer A is the person, typo ("of they") included, even though it reads like a textbook. Answer B is the AI, and that neat closing line with a semicolon is a tell.3. Why do we believe that aliens are smarter than us?
Answer A: Honestly, we don’t really assume they’re smarter. The argument is just that if they built interstellar ships, they must be way more advanced tech-wise than us right now. It’s less about intelligence and more about being further along on the technological ladder.
Answer B: I imagine you’re referring to aliens that would be capable of traveling to Earth at high speed from a great distance. In that case it would be assumed they are more intelligent than us because we lack the technology to do the same.
Show who wrote what
Answer A is the AI, and Answer B is the person. It's the stiffer of the two, which is exactly why this one is hard.Human answers: Reddit users via the HC3 dataset (Guo et al., 2023), CC BY-SA 4.0, with tokenizer spacing removed and questions lightly shortened.
What the test doesn’t prove
Jones and Bergen themselves conclude that the test is not a direct test of intelligence but “a test of humanlikeness”. Their explanation is neat: intelligence once looked like the hard part of seeming human, so Turing imagined questions about mathematics and chess. Machines now handle those well, so people judge on other things. Interrogators most often cited language style (27%) and how the conversation flowed (23%).
The older criticisms still apply, and each makes a different point:
- The Chinese Room (John Searle, 1980). A person follows a rulebook to answer in Chinese without understanding a word. Searle’s point is that manipulating symbols doesn’t produce meaning, so passing wouldn’t show understanding. Critics reply that the whole system might understand even if the person doesn’t.
- Blockhead (Ned Block, 1981). Imagine a giant lookup table holding a sensible reply for every possible conversation. It would pass and clearly wouldn’t think, which suggests that behavior alone isn’t enough. It is arguably not physically buildable, but it shows the logic of the objection.
- Too human (Robert French, 1990). The test can catch a machine with questions that tap subconscious associations built up by living in a human culture. So it may measure a culturally shaped kind of intelligence rather than intelligence in general.
- Wrong goal (Patrick Hayes and Kenneth Ford, 1995). Their paper “Turing Test Considered Harmful” argued that chasing imitation distracts AI research.
- It tests us (Gary Marcus, 2025). Marcus called it “a test of human gullibility”, and the ELIZA effect supports him: people read far more understanding into text than is there.
Passing also says nothing about consciousness. Neither the study’s authors nor any serious source we read claims otherwise. Nor does it say the system is safe, truthful or useful, since a good imitator can make things up in a very convincing voice.
There is a fair point on Turing’s side too. He anticipated the consciousness objection in 1950 and asked how we know that other people think, other than by how they behave. And the goalposts do move: Marcus co-authored a paper declaring the Winograd Schema Challenge defeated, a test once proposed as a sturdier replacement.
What researchers use instead
| Alternative | What it asks | Where it stands |
|---|---|---|
| Total Turing Test (Stevan Harnad, 1991) | Adds a robot body and physical abilities to the conversation | Still far beyond text-only results |
| Winograd Schema Challenge (Hector Levesque, 2011) | Resolve a pronoun that flips meaning with one changed word, with no deception needed | Systems passed 90% by 2019 |
| Comprehension challenge (Gary Marcus) | Follow a full TV episode and explain who is lying to whom and why | Proposed, no standard version |
| Coffee test (attributed to Steve Wozniak) | Walk into an ordinary home and make coffee | A robotics goal rather than a conversation test |
| ARC-AGI (François Chollet, 2019) | Measures how efficiently a system learns new skills, using novel puzzles | ARC-AGI-3 launched in March 2026 with humans at 100% and frontier AI under 1% |
| Levels of AGI (Google DeepMind, 2023) | Grades capabilities across levels rather than one pass or fail | Treats the Turing test as insufficient |
The general direction is away from “can it fool someone?” and toward “what can it actually do?”. For more on those definitions, see artificial general intelligence and our guide to the types of AI.
The reverse Turing test
In a reverse Turing test the machine is the judge and you’re the one proving you are human. The everyday example is the CAPTCHA, which stands for “Completely Automated Public Turing test to tell Computers and Humans Apart”. The 2003 paper called it a win-win: either the puzzle stays hard, or someone has solved an AI problem.
That win has arrived. ETH Zurich researchers solved 100% of reCAPTCHAv2 challenges in 2024, up from 68-71% in earlier work. A group of 32 authors has since proposed personhood credentials, which would prove you are human without revealing who you are.
Can people and software spot AI text?
Sometimes, and it depends a lot on who is checking.
| Who is judging | Result | Source |
|---|---|---|
| Non-experts | Caught 56.7% of AI articles but also wrongly flagged about 52% of human ones | Russell et al., 2025 |
| 5 frequent LLM users, majority vote | Misclassified 1 of 300 articles | Same study |
| 4,600 people on self-descriptions | 50-52% accuracy | Jakesch et al., 2023 |
| Pangram, a commercial detector | Caught 98% of AI articles with 2% false positives | Russell et al., 2025 |
| Seven detectors on non-native English essays | Falsely flagged 61.3% of them on average | Liang et al., 2023 |
Experience seems to matter more than instinct. The Jakesch study found that people treat first-person pronouns, contractions and talk of family as human signs, yet those cues didn’t work. That fits our own test, where a casual tone bought a lot of credibility. The Russell result used long articles and only a few annotators, and the Liang study covers 2023 detector versions, so neither settles the matter. OpenAI shut down its own classifier in July 2023 because of low accuracy. Don’t treat a detector score as proof against a student or a writer.
Why this matters outside the lab
Short conversations are the very setting in which models now pass, and they’re also how many scams, sales calls and support chats work. The FBI’s 2025 internet crime report counted 22,364 complaints mentioning AI, with about $893 million in losses. Engineering firm Arup lost around US$25 million after a deepfake video call in 2024.
Lawmakers have started to require disclosure rather than asking anyone to spot the difference:
- EU. Article 50 of the AI Act has applied since 2 August 2026. Chatbots must tell people they are talking to an AI, unless that’s obvious. The later December 2026 date covers the marking of generated content by existing systems, not this duty.
- California. The BOT Act (SB 1001), in effect since July 2019, bars bots from misleading people in California about their artificial identity for commercial or political purposes. SB 243, in effect since January 2026, adds notice requirements for companion chatbots, with repeat reminders for known minors.
- US federal. In February 2024 the FCC ruled that AI-generated voices count as “artificial” under the robocall law.
This is not legal advice, and several US state laws take effect in 2027, so check the current text if it applies to you.
Who was Alan Turing?
Alan Turing was a British mathematician, born in London on 23 June 1912. His 1936 paper “On Computable Numbers” laid the groundwork for the modern computer. During the Second World War he worked at Bletchley Park, where he developed the Bombe from an earlier Polish machine, and his section, Hut 8, broke Naval Enigma.
In 1952 he was prosecuted for his relationship with a man, and he accepted a year of oestrogen injections instead of prison. The conviction cost him his security clearance. He died in June 1954 of cyanide poisoning; the inquest recorded suicide, though his mother believed it was an accident (Andrew Hodges’ biography covers this carefully). The UK government apologized in 2009 and he received a royal pardon in December 2013. Computing’s top honor, the ACM Turing Award, carries his name, and he has appeared on the Bank of England’s £50 note since 2021.
Frequently asked questions
What is the Turing test in simple terms?
It’s a game where a person chats by text with a human and a machine and tries to tell which is which. If the person can’t reliably do it, the machine has passed. It tests whether a machine can seem human in conversation, not whether it thinks.
Has any AI passed the Turing test?
Yes, in short games with a prepared character. In a 2026 PNAS paper, GPT-4.5 was picked as the human 73% of the time in five-minute games. GPT-5 scored 59.3% and LLaMa-3.1 55.6% in 15-minute games. Longer or expert-led versions, such as the 2029 Kurzweil-Kapor bet, remain untested or undecided.
Did Eugene Goostman pass the Turing test?
Its organizers claimed so in 2014 after it fooled 33% of 30 judges, but many experts rejected that. It relied on a 30% rule that isn’t in Turing’s paper, and on playing a 13-year-old non-native speaker who was expected to make mistakes.
What percentage do you need to pass?
There is no official number. Turing’s paper contains only a forecast about 70% correct identification after five minutes. In a three-party test, researchers treat a win rate not significantly below 50% as a pass, since 50% is what guessing would give.
Can I take a Turing test online?
You can try the three pairs above, though they are one-shot answers rather than a chat. AI21’s Human or Not? was the best-known live version in 2023. A real test needs a live conversation with follow-up questions. In the PNAS study, the interrogators who said something strange were the most accurate.
What is a reverse Turing test?
It’s a test where a machine checks whether you are human. CAPTCHAs are the common example, and vision models can now solve many of them.
Does passing the Turing test mean AI is conscious or intelligent?
No. It shows that the system can imitate human conversation well enough to convince someone for a limited time. The authors of the main study say it isn’t a direct test of intelligence, and it tells us nothing about consciousness.
Why does a persona make such a difference?
Most people judge by style and rapport rather than by testing knowledge. A persona gives the model a consistent, believable voice and lowers expectations, and a system prompt is enough to do that. Our guide to how AI works explains why these instructions shape the output so strongly.