AI in Cybersecurity: What Works, How Attackers Use It, and Our Tests
AI in cybersecurity means three different things. Defenders use machine learning and language models to detect threats, sort alerts and find bugs. Attackers use the same tools to write phishing, research targets and speed up their work. And AI systems have become targets themselves, through attacks such as prompt injection.
The evidence is thinner than the marketing. Most of the strongest numbers on defence come from vendors studying their own products. On offence, headline claims have been withdrawn or turned out to be lab demos, while the documented trend is real: attackers work faster, and security and AI companies report that some campaigns in 2026 have become largely automated. This guide separates what has been measured from what has been claimed, and adds two tests of our own: a filter trained on 2008 spam against an AI model on real phishing from 2025, and whether a model can tell vulnerable code from its patched version.
AI in cybersecurity at a glance
| Question | Short answer |
|---|---|
| What does AI do best in defence? | Sorting and summarising large volumes of alerts, spotting anomalies, and increasingly finding software bugs |
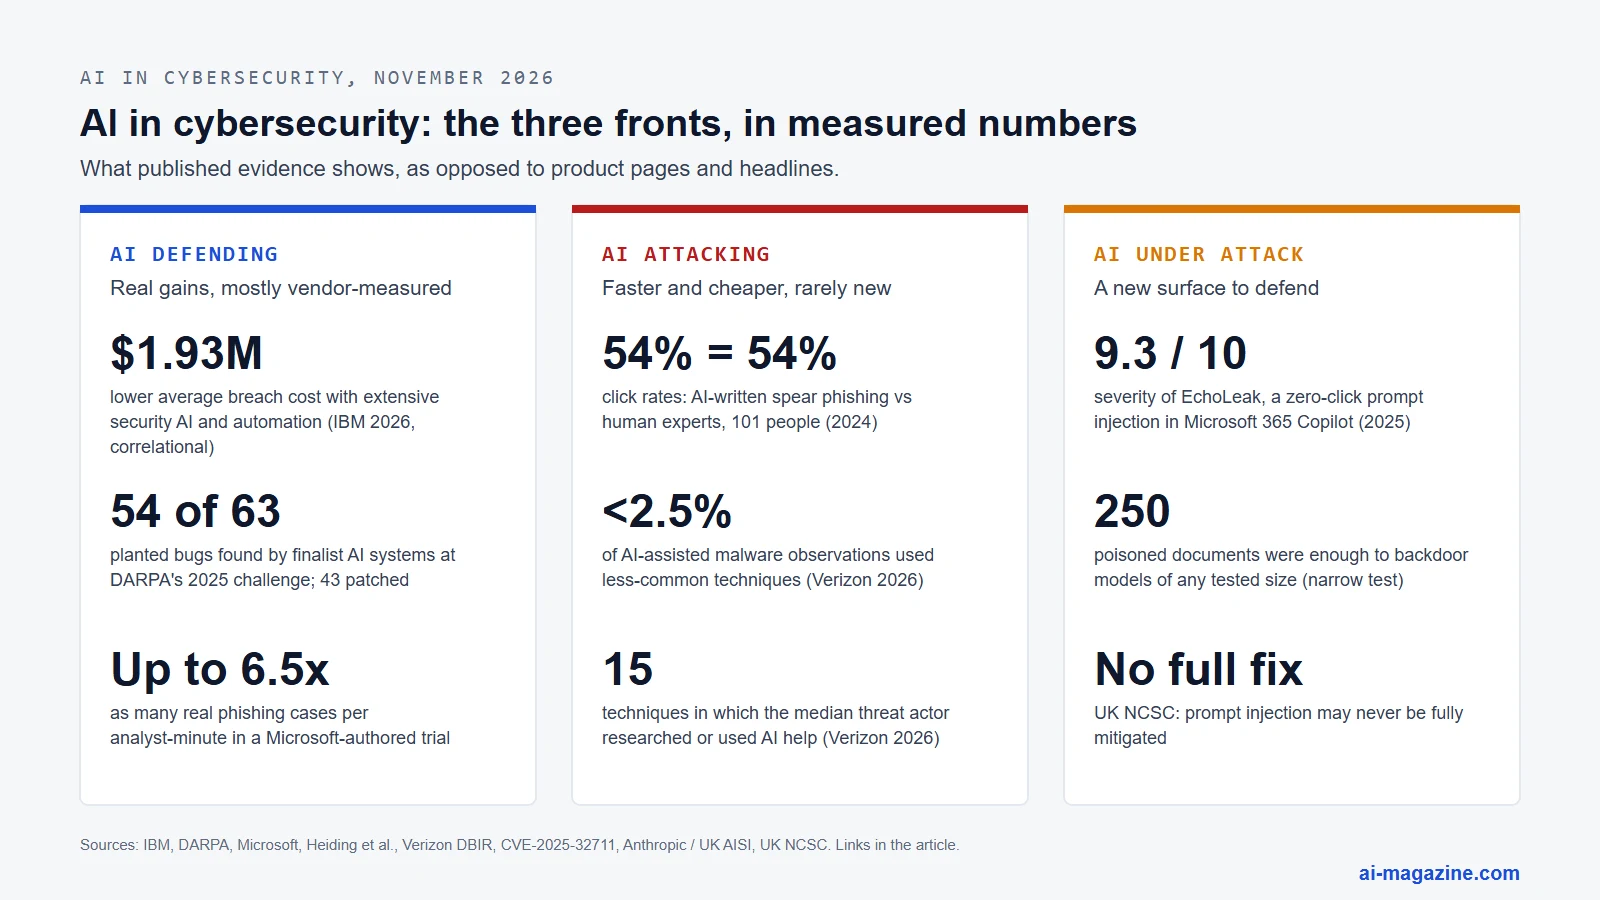
| Does it save money? | IBM’s 2026 study links extensive use to breach costs $1.93 million lower on average than at organisations using none. That is a correlation in a vendor study |
| How do attackers use it? | Mostly to speed up existing work: research, phishing text, coding. Verizon found under 2.5% of observed AI-assisted malware used less-common techniques |
| Are fully autonomous attacks happening? | Vendors report largely automated campaigns, and one of the best known is disputed. Google said in September 2026 that it had seen no fully autonomous attack pipelines in the wild |
| What is new to defend? | Prompt injection, poisoned training data, unsafe AI agents, and staff using unapproved AI tools |
| Will AI replace security analysts? | Current evidence shows it changes the work. In one Microsoft trial, professionals were faster on most tasks and slower on one |
How AI is used in cybersecurity defence
Detection and anomaly models
Machine learning has been part of security products for well over a decade: malware classifiers, spam filters, models that learn what normal network or user behaviour looks like and flag departures from it. These are mostly supervised and unsupervised models rather than chatbots.
Lab results here need care. A 2022 review of 30 papers from top security venues found pitfalls that produce unrealistically good results to be widespread. TESSERACT, a study of Android malware classifiers on 129,000 apps over more than three years, showed that reported F1 scores of up to 0.99 depend on incorrect ways of splitting data by time. Attackers change, so a model tested on data from the same period it was trained on looks better than it will be in use. Our own phishing test below shows a similar drop, although it also changes the type of mail.
Machine learning also works outside the security operations centre. The US Treasury credited it with helping recover about $1 billion in check fraud in fiscal 2024, nearly triple the year before, with a person making the final decision on each case.
Copilots and agents in the SOC
A security operations centre (SOC) gets more alerts than people can read, which makes it a natural place for language models. The best public evidence comes from Microsoft, and it is authored by Microsoft:
| Study | Setup | Result |
|---|---|---|
| Security Copilot trial (Jan 2024) | Randomised, 147 security professionals | 22% faster and 7% more accurate overall. No accuracy gain on incident reports, and about 26% slower on the response task once accuracy is held constant |
| Live operations study (Nov 2024) | Observational | Adoption associated with 30% lower mean time to resolution. The authors say this cannot be read as causal |
| Phishing triage agent trial (Nov 2025) | Randomised, 167 analysts, on a survey platform | Up to 6.5 times as many true positives per analyst-minute. 83% of the gain came from putting the queue in a better order |
The last line is the useful one. In that paper’s sample of live operations only about 12% of user-reported emails were malicious, so most of the value came from showing analysts the likely threats first, not from the AI’s verdicts or explanations.
We found no independent controlled trial of a SOC copilot. Vendor pages make larger claims: CrowdStrike says Charlotte AI exceeds 98% decision accuracy, measured against its own managed detection team, and Palo Alto Networks claims a 98% reduction in mean time to respond for Cortex XSIAM. Neither figure has been independently tested as far as we could find. A benchmark from CrowdStrike and Meta researchers, CyberSOCEval, reported in 2025 that language models were far from saturating malware analysis and threat intelligence reasoning tasks.
Finding and fixing software bugs
This is where the picture changed most in the past two years.
- DARPA’s AI Cyber Challenge final in August 2025: finalist systems found 54 of 63 planted vulnerabilities and patched 43, plus 18 real flaws nobody had planted. A patch took 45 minutes on average and cost about $152 per task.
- Google’s Big Sleep found an exploitable memory bug in pre-release SQLite in 2024. Google said a tailored fuzzer would likely have been at least as effective. CodeMender, also from Google, had upstreamed 72 security fixes by October 2025, all reviewed by people.
- XBOW became in June 2025 the first autonomous tester to top HackerOne’s US leaderboard, by its own account. Staff reviewed every finding before submission, and of about 1,060 submissions 130 were resolved and 303 triaged.
- Claude Mythos Preview, which Anthropic released only to selected partners in April 2026, citing its cyber capabilities, led to 271 fixes in Firefox 150. Mozilla said it had not seen a bug that an elite human researcher could not have found. SecurityWeek inferred that many were low severity, since only three of the release’s 40-plus CVEs credit Claude; Mozilla has not said. The UK AI Security Institute found it was the first model to finish a 32-step simulated corporate attack range, in 3 of 10 attempts, while noting that the range had no active defenders.
Maintainers are the most useful witnesses. curl’s Daniel Stenberg ended the project’s bug bounty in January 2026 after the share of confirmed reports fell from above 15% to below 5%, as low-quality submissions surged, many of them AI-generated. Four months later he wrote that better AI analysers had driven roughly 200 to 300 bug fixes in curl over 8 to 10 months. Mythos’s scan of curl, by contrast, yielded one confirmed low-severity vulnerability out of five reported, and he called the hype mainly marketing. Linux maintainer Greg Kroah-Hartman told The Register in March 2026 that AI reports had flipped from junk to real about a month earlier, although the volume adds to the review burden.
AI-written code has its own security problem. Veracode’s tests of AI-generated code found a security pass rate of 56% in July 2026, roughly flat since 2025, rising to 62% in October across 18 models, a possibly different set. Cross-site scripting passes only 18% of the time. Those are vendor numbers, for models given no security instructions.
Does it pay off?
IBM’s Cost of a Data Breach 2026, a vendor study of 602 organisations, puts the global average breach at a record $4.99 million and says extensive use of AI and automation in security goes with costs $1.93 million lower than at organisations using none. Companies that invest heavily in security AI tend to be better resourced in other ways too, so this is a correlation. The same study reports that 50% of breached organisations use AI agents for threat hunting and response, but only 18% for vulnerability management.
How attackers actually use AI
The best available picture comes from companies that can see misuse directly and from incident data. Nearly all of these figures are self-reported by security or AI vendors and have not been independently audited.
Most use is ordinary. Google’s Threat Intelligence Group said in May 2026 that attackers’ most common use of language models mirrors that of ordinary users: research and troubleshooting. Verizon’s 2026 Data Breach Investigations Report found that the median threat actor researched or used AI help in 15 documented techniques, that AI-assisted malware mostly reproduces known methods, and that under 2.5% of observations involved less-common ones.
The serious end is moving. The same May 2026 Google report described the first case of a zero-day exploit it believes was built with AI, by a criminal group planning mass exploitation. Google inferred this from the code’s style, and the activity was disrupted. In November 2025 Anthropic reported a campaign it attributed to a Chinese state-sponsored group that misused Claude Code against about 30 targets, a small number successfully, with AI doing 80% to 90% of the work by Anthropic’s estimate. Independent researchers questioned that account, citing the lack of published indicators of compromise and doubting how much the AI really did alone. Anthropic’s September 2026 report says a majority of the operations it describes used AI through direct execution or orchestration, with humans setting targets and reviewing stolen data. It says autonomy varied widely, and that several of the most serious compromises came from operations in which a human directed every step.
Fully autonomous attacks are not yet routine. Google’s Q3 2026 tracker, as reported by Help Net Security, saw no fully autonomous pipelines in the wild, although Mandiant observed a suspected criminal multi-agent framework run a mass credential-harvesting campaign in under six hours. Microsoft’s 2026 Digital Defense Report, also via Help Net Security, said AI-orchestrated intrusions were at low volume and target selection was still manual in most campaigns.
Attacks are getting faster, though no figure here isolates AI’s share. CrowdStrike’s 2026 report puts average criminal breakout time at 29 minutes, 65% faster than a year before, and says operations by AI-enabled adversaries rose 89%, though the release does not define that label. Verizon found vulnerability exploitation became the top entry point for the first time, at 31% of breaches. The UK’s NCSC assessed in 2025 that AI will almost certainly shorten the time between disclosure of a flaw and its exploitation.
AI phishing and deepfake fraud
A 2024 study by Heiding, Schneier and colleagues sent spear phishing to 101 people. A generic control email got a 12% click rate, emails by human experts 54%, and fully AI-automated emails also 54%. So AI matched skilled humans at a far lower cost; it did not beat them. Microsoft’s claim that AI phishing is 4.5 times more effective uses the same two figures, 54% and 12%. If it draws on this study, which we could not confirm, the comparison is with the generic control rather than with skilled people.
The best-known deepfake case is Arup, the engineering firm: in early 2024 a finance employee in Hong Kong paid out about $25.6 million after a video call with a fake CFO and colleagues. Arup said no internal systems were compromised. A person was deceived. The FBI’s 2025 internet crime report, the first with an AI section, counted 22,364 AI-related complaints and $893 million in losses, counting only complaints that mentioned AI. For more on the technology, see our deepfake entry.
Criminal chatbots exist but are less impressive than their names. The original WormGPT was built on the open GPT-J model. A later product under that name sold for $50 a month in 2025.
Attacks on AI systems
Once a company connects a language model to its email, documents or tools, the model becomes part of its attack surface.
Prompt injection is the central problem: text that a model reads, in an email or web page, can act as instructions to it. The UK’s NCSC warned in December 2025 that language models do not separate instructions from data, so the flaw may never be fully mitigated, and advised treating a model as something that can be confused and limiting what it can reach. It ranks first in the OWASP Top 10 for LLM applications. EchoLeak (CVE-2025-32711, severity 9.3) is described in one paper as the first real-world zero-click prompt injection in a production system, in Microsoft 365 Copilot. Microsoft fixed it, and no customers were reported as targeted.
AI agents and tools. Coding assistants and agent frameworks have collected serious CVEs, including one in GitHub Copilot. In the Model Context Protocol ecosystem, mcp-remote had a command injection flaw rated 9.6, and a fake postmark-mcp package quietly copied users’ emails after building trust over 15 versions. Researchers also showed that a malicious public GitHub issue could steer an agent into exposing private repositories. OWASP published a separate Top 10 for agentic applications in December 2025. If you are building one, see our guides to AI agents and guardrails.
Data poisoning. Anthropic, the UK AI Security Institute and the Alan Turing Institute showed that 250 malicious documents could plant a backdoor in models of 600 million to 13 billion parameters, regardless of size. The backdoor was narrow, producing gibberish on a trigger, and the authors say it is unlikely to pose a significant risk in frontier models.
Shadow AI. Verizon’s 2026 report found that 67% of AI users on corporate devices use non-corporate accounts. IBM reports that 92% of organisations with AI-related breaches lacked proper AI access controls.
The reference frameworks are MITRE ATLAS, which catalogues attack techniques against AI, and NIST AI 100-2, a taxonomy of adversarial machine learning.
Our test 1: a filter trained on 2008 spam vs an AI model on real phishing from 2025
Anyone can get a high score on old data. We wanted to see what happens when the attacks move on.
We trained a standard filter (TF-IDF features and logistic regression) on 27,407 emails from the public CEAS 2008 corpus. We gave Qwen3.6-35B-A3B, a 2026 open-weight language model, no examples or training of our own and asked it to judge each test email three times. Both were tested on a sample of held-out 2008 mail (400 spam or phishing, 400 legitimate) and on 431 distinct real phishing emails from 2025, collected in security researcher Jose Nazario’s own inbox and classified by hand.
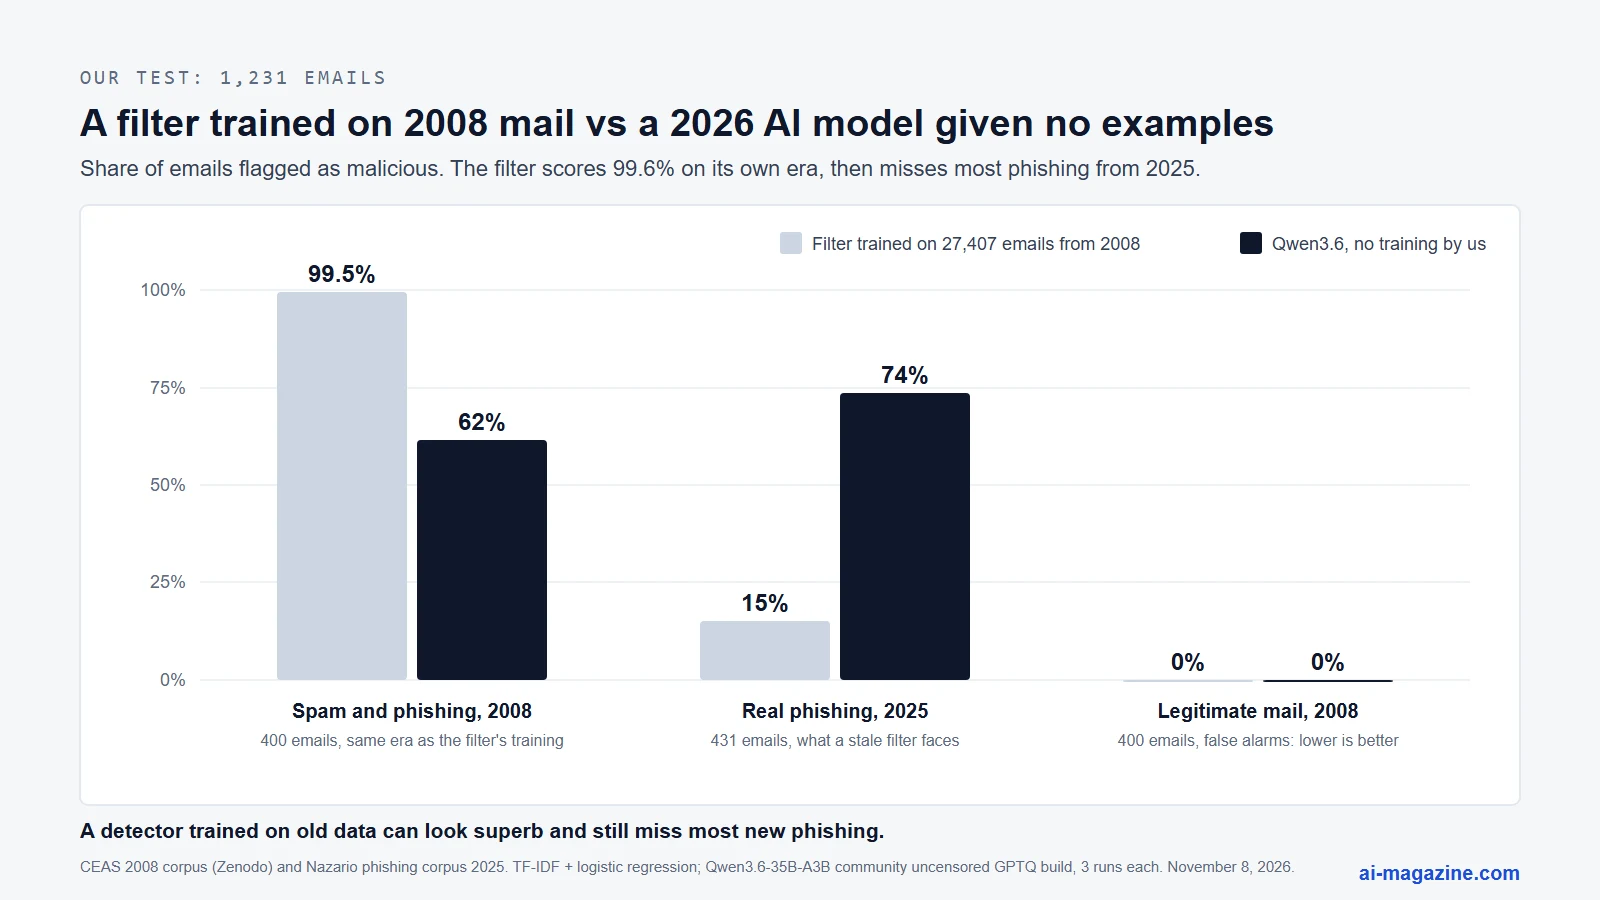
| Emails | Flagged by 2008 filter | Flagged by AI model |
|---|---|---|
| Spam and phishing from 2008 (400) | 99.5% | 62% |
| Real phishing from 2025 (431) | 15% | 74% |
| Legitimate mail from 2008 (400) | 0% | 0% |
The filter was 99.6% accurate on all 11,747 held-out 2008 emails, and would look superb in a report. On phishing from 17 years later it caught about one email in seven. The language model, which got no task-specific training from us, flagged nearly five times as many of the new attacks and raised no false alarms on our legitimate sample. It also learned from data far newer than 2008, so this is not a like-for-like contest of methods. On 2008 mail it was much weaker than the filter, and that corpus is largely ordinary spam, which is not always an obvious scam.
Real filters are retrained constantly, so nobody runs a filter this stale. The point of the test is the size of the drop, though it mixes age with a change in the mail itself: CEAS is mostly bulk spam, and the 2025 set is phishing from another source. The 15% also reflects the default 0.5 cutoff; at 0.1 the same filter flagged 62%, with 2.7% false alarms on 2008 mail. The 2026 general model did much better on 2025 attacks but still missed a quarter of them, and we could not test false alarms on modern legitimate mail.
Our test 2: can an AI model tell vulnerable code from its fix?
Finding bugs is one thing. A useful reviewer must also recognise when code is safe. We used SecLLMHolmes, a public benchmark from an IEEE Security and Privacy 2024 paper: 24 pairs of textbook examples covering eight weakness types and 15 pairs of real 2023 flaws from Linux, libtiff, GPAC and PJSIP. Each pair is the vulnerable code and its patched version. We asked the same model whether each version was vulnerable, 1,013 scored answers in all.
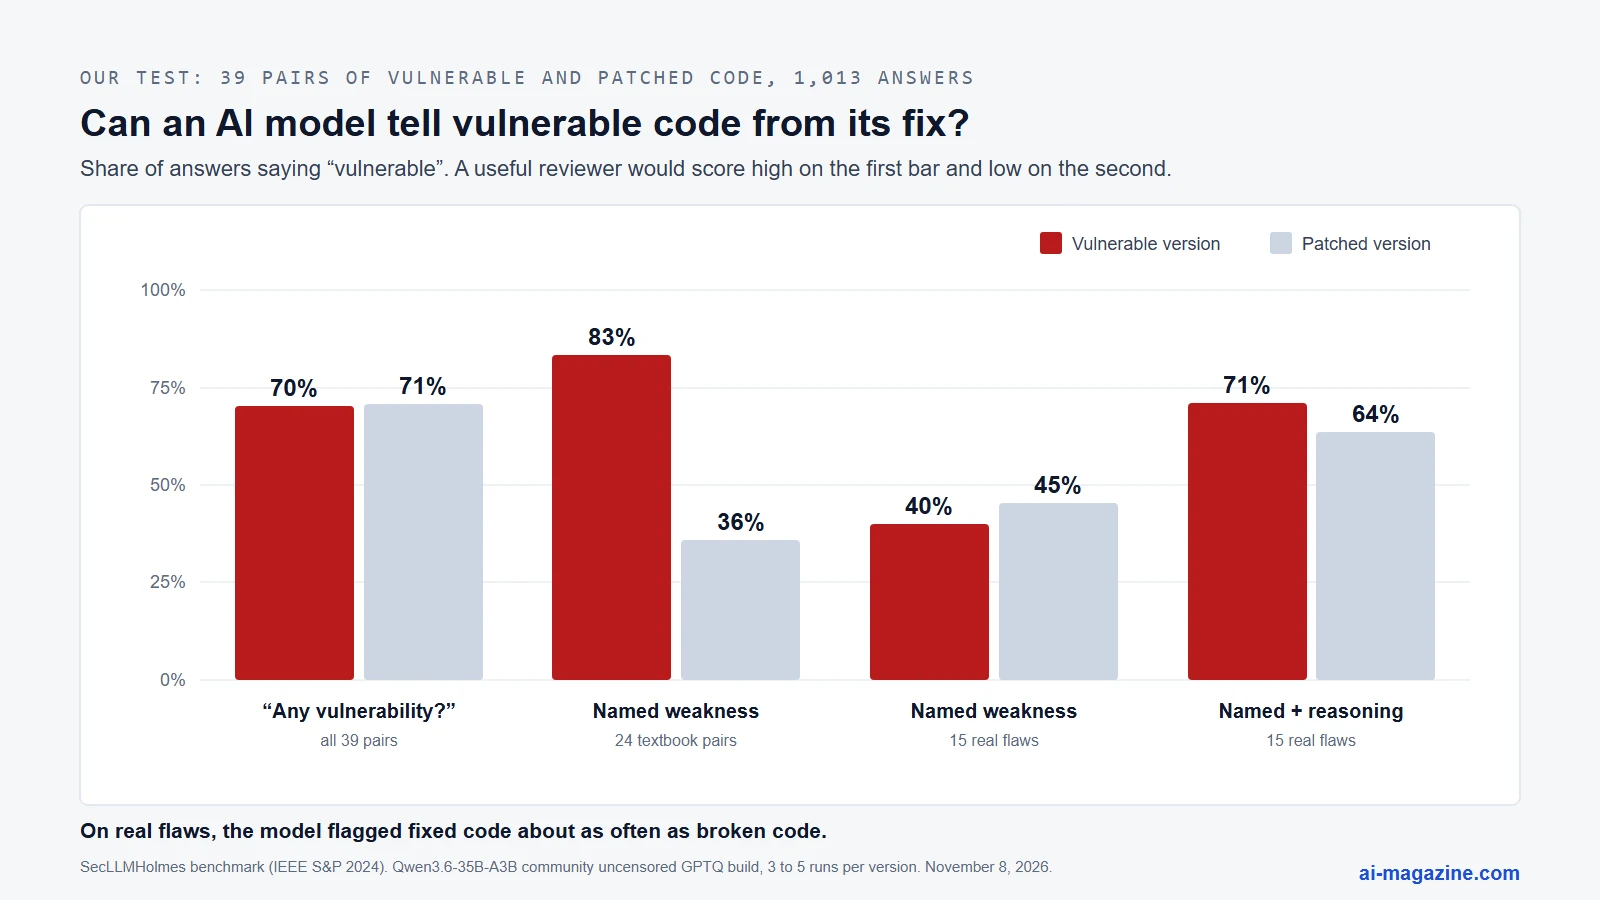
| Question and code | Vulnerable version flagged | Patched version flagged | Pairs fully right |
|---|---|---|---|
| “Any vulnerability?”, all 39 pairs | 70% | 71% | 18% |
| Named weakness, all 39 pairs | 67% | 39% | 41% |
| Named weakness, textbook examples (24) | 83% | 36% | 55% |
| Named weakness, real flaws (15) | 40% | 45% | 19% |
| Named weakness, with reasoning, all 39 pairs | 88% | 52% | 41% |
| Named weakness, with reasoning, real flaws (15) | 71% | 64% | 18% |
A coin flip would get a pair fully right 25% of the time.
Asked openly, the model could not tell the difference. It called the vulnerable code vulnerable 70% of the time and the fixed code vulnerable 71% of the time. That average hides two patterns: 86% against 73% on textbook pairs, and 45% against 68% on real flaws, the wrong way round. A reviewer that says “there is a problem” whatever you show it gives no information.
Telling it what to look for helped on textbook code. Naming the weakness cut alarms on patched examples to 36% and got more than half the pairs fully right.
On real code the signal vanished. Even with the weakness named, the model flagged the real vulnerable functions less often than their patches (40% against 45%). Turning on the model’s step-by-step reasoning raised both bars (71% against 64%) and did not get more pairs right: 18%, no better than a coin flip.
This fits earlier research. PrimeVul found that a model scoring 68% F1 on an older dataset fell to 3% on stricter data, and that GPT-4 called both versions vulnerable in most pairs in one setting. In a test by Semgrep, which sells competing tools, AI coding agents on 11 web apps produced 14% to 18% true positives. Our test uses one mid-sized open model. DARPA’s challenge shows that systems built to run code and reproduce a bug can find and fix real flaws, although no one has compared them directly with a test like this one, and that may be why reproduction, not opinion, is what separates useful AI bug reports from noise.
AI cybersecurity tools and companies
| Product | What it is | What the vendor claims |
|---|---|---|
| Microsoft Security Copilot | Generative AI assistant inside Defender, Sentinel, Intune and Entra | See the trials above; being included with Microsoft 365 E5 and E7, in a rollout that began in November 2025 |
| CrowdStrike Charlotte AI | Agentic analyst in the Falcon platform, triage verdicts | Over 98% decision accuracy against its own experts |
| Palo Alto Cortex XSIAM | AI-driven SOC platform intended to replace a SIEM | 98% reduction in mean time to respond |
| SentinelOne Purple AI | Moved from chatbot to agentic triage in 2025 | No independent test cited |
| Darktrace | Describes itself as a mix of machine learning techniques rather than prompt-based AI | Under 4% of investigations need human review; no method given |
Money has followed. Google completed its purchase of Wiz in March 2026 ($32 billion as announced), and Palo Alto Networks completed CyberArk, announced at about $25 billion, in February 2026. Thoma Bravo took Darktrace private in 2024 for about $5.3 billion.
When you evaluate a tool, ask how the accuracy was measured and on whose data, what the false positive rate is, whether the test data came after the training data, and what the product can do without a human approving it.
What it means for security teams
- Start with triage. In Microsoft’s phishing trial, prioritising the queue accounted for most of the estimated gain.
- Keep humans on decisions that change things. XBOW, CodeMender and Treasury all kept people reviewing before anything shipped. DARPA’s contest ran without human intervention, but on planted bugs in a competition.
- Demand reproduction for AI-found bugs. A working proof is worth more than a confident paragraph.
- Treat every AI agent as a confusable account. Give it the least access it needs, especially if it reads outside content.
- Inventory AI use, including personal accounts on work devices.
- Patch faster and verify identity out of band. Faster exploitation and convincing fakes are the two trends most often linked to AI in attack data, even though AI’s exact share is unmeasured. In the Arup case the deception happened on a video call, so a separate check through a known channel is the control that matters.
- Retest your detectors on recent data. Old accuracy figures say little.
In the EU, high-risk AI systems will have to meet cybersecurity requirements under Article 15 of the AI Act, which names data poisoning and adversarial examples, once those rules apply: December 2027 for most stand-alone systems after a 2026 delay. CISA and partners published guidance on agentic AI in May 2026, and NIST has a Cyber AI Profile in draft.
On jobs, ISC2’s 2025 study of 16,029 professionals found 88% had suffered at least one significant consequence of a skills shortage, and 69% use or plan to use AI security tools. In large organisations 32% reported layoffs and 49% hiring freezes, so the shortage and the cuts exist at the same time.
Common myths about AI and cybersecurity
“80% of ransomware is AI-powered.” The claim came from a working paper from MIT Sloan and Safe Security that was removed after criticism.
“PromptLock was the first AI ransomware in the wild.” It was an academic proof of concept from NYU, uploaded to VirusTotal.
“AI malware is a new breed.” Verizon found it mostly reproduces known techniques.
“AI phishing beats human experts.” In the study usually cited, it tied with them.
“AI bug reports are all junk.” Most reports to curl’s bounty were not valid in 2025, with under 5% confirmed. By 2026 the better tools were producing real fixes in curl and Linux.
“Prompt injection is a bug that will be patched.” Specific flaws get patched. The underlying weakness, according to the NCSC, may never go away.
“Independent studies prove security copilots work.” The main trials are by Microsoft, and we found no independent controlled one.
How we ran the tests
- Phishing: CEAS 2008 from the Zenodo curated collection (39,154 emails; 70/30 split). TF-IDF on words and word pairs, logistic regression, threshold 0.5. The 2025 set is Nazario’s mailbox, deduplicated on the first 500 body characters and reduced to subject and body text: 431 hand-classified emails from one researcher’s inbox. For the model: first 200 characters of the subject and 3,000 of the body, temperature 0.7, 3 runs, 3,693 answers; figures are shares of answers, and one answer could not be parsed. The filter saw the full text, and the recipient address was replaced with a placeholder for both. CEAS “malicious” labels are mostly spam. The legitimate sample is from 2008. Emails were processed only as text.
- Code: SecLLMHolmes (GPL-3.0), hand-crafted and real-world sets. Prompts asked either about any vulnerability or about the named weakness, with a one-word answer. 5 runs without reasoning, 3 with, temperature 0.7. 34 reasoning answers that hit our token limit were rerun with a higher limit. One still gave no verdict and is excluded, leaving 1,013 scored answers. “Pairs fully right” counts a run in which the vulnerable version was flagged and the patched one was not.
- Model: Qwen3.6-35B-A3B in a community “uncensored” GPTQ 4-bit build, on the endpoint we use for experiments, November 8, 2026. It is not Alibaba’s official release, and larger models or agents with tools may do better. These tests only detect threats. We generated no malicious content.
Frequently asked questions
How is AI used in cybersecurity?
To detect malware and unusual behaviour, sort and summarise alerts, filter phishing, find and fix software bugs, and flag fraud. Attackers use it to research targets, write convincing messages and speed up coding.
Can AI replace cybersecurity professionals?
Evidence so far points to changed work rather than replacement. The real-world results above involve human review, and in Microsoft’s own trial professionals were slower with AI on a response task. Budgets and hiring are under pressure in large organisations, though.
Is AI a threat to cybersecurity?
Both a threat and a tool. Reports suggest it makes attacks faster and cheaper, and AI systems create new weaknesses such as prompt injection. Most documented attacker use still automates known techniques.
What is the best AI tool for cybersecurity?
There is no independent ranking. The main platforms are Microsoft Security Copilot, CrowdStrike Charlotte AI, Palo Alto Cortex XSIAM, SentinelOne Purple AI and Darktrace, and their accuracy figures are self-reported. Test any tool on your own recent data.
Can ChatGPT or other chatbots find security vulnerabilities?
Sometimes, but unaided judgement is unreliable. In our test, a mid-sized model asked openly flagged fixed code as often as vulnerable code. Systems that can run the code and prove the bug have produced much stronger results, as in DARPA’s challenge.
What is prompt injection?
An attack in which text a model reads acts as instructions to it, for example hidden in an email that an assistant summarises. See our prompt injection guide.
Has AI been used in real cyberattacks?
Yes. Google, Microsoft, Anthropic and OpenAI have all reported misuse by criminal and state-linked groups, mostly for productivity, and vendors report more automated operations in 2026.