AI Frameworks and Libraries: What PyTorch, TensorFlow, scikit-learn and Others Are Used For (2026)
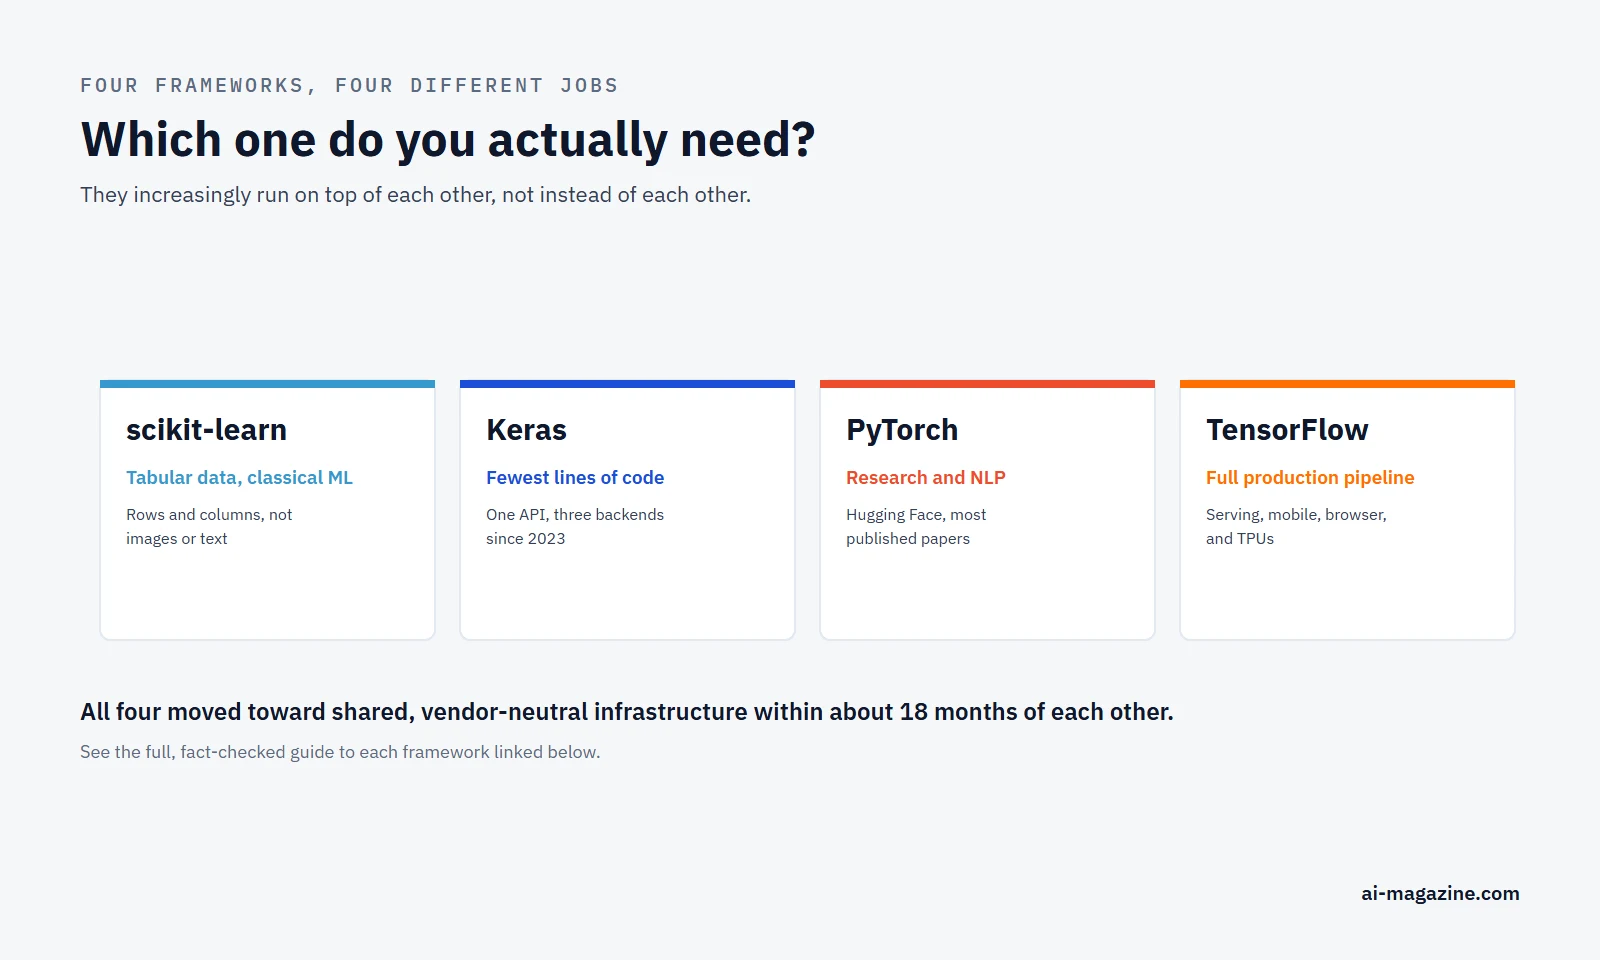
AI frameworks and libraries are the software developers use to build, train and run machine learning models. They are not interchangeable: scikit-learn and XGBoost work on tables of numbers, PyTorch, TensorFlow, JAX and Keras train neural networks, Hugging Face Transformers hands you ready-made models, and runtimes such as ONNX Runtime, LiteRT and vLLM run finished models on servers, phones and in browsers. This guide explains what each one is actually used for, with real examples from companies that use them and short code samples, then maps them to tasks and gives a way to choose. We also measured which frameworks people install and share in October 2026, and ran the same two jobs through scikit-learn, XGBoost, LightGBM, PyTorch and Keras to show why the right tool depends on the data.
| Framework | What it is mainly used for | Typical users |
|---|---|---|
| PyTorch | Training and fine-tuning neural networks, LLMs, research | Meta, OpenAI, Shopify, most published models |
| TensorFlow | Production ML pipelines, on-device and browser ML | Google products, many 2017–2021 enterprise systems |
| Keras | Writing neural networks quickly, on any of three backends | Learners, prototyping, Google teams |
| scikit-learn | Classical machine learning on tabular data | Almost every data science team |
| JAX | Large-scale training on TPUs, scientific computing | Google DeepMind, Apple, xAI |
| Hugging Face Transformers | Using and fine-tuning pretrained models | Anyone working with open models |
| XGBoost, LightGBM, CatBoost | Best accuracy on tables: fraud, credit, pricing | Banks, marketplaces, competition winners |
| ONNX Runtime, LiteRT, ExecuTorch, vLLM | Running trained models fast in production | Windows, Google and Meta apps, LLM APIs |
What is an AI framework (and how is it different from a library)?
The distinction between a framework and a library matters when you are architecting a system. A library is a collection of functions you call to perform specific tasks, like scikit-learn’s classification algorithms. A framework provides a structure where you plug in your code; it often controls the flow of execution, as seen in PyTorch’s dynamic computation graphs or TensorFlow’s execution engines. In practice the line blurs, and people use “framework” for both, but the intent differs: libraries give you tools, frameworks give you an environment.
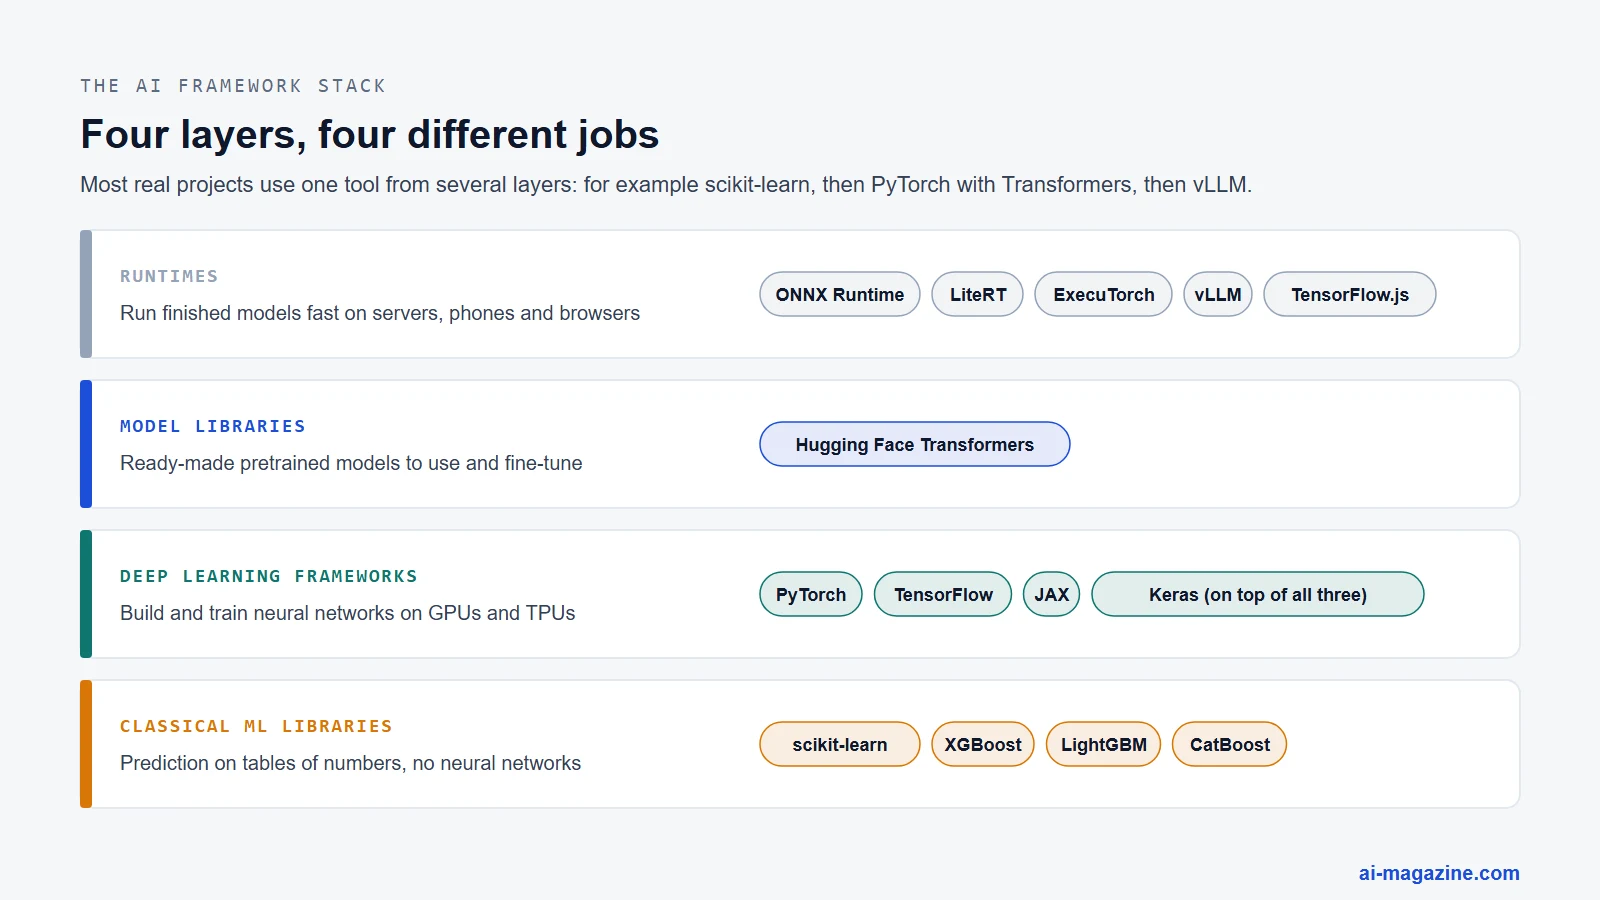
The modern AI stack sits on four distinct layers. The first layer consists of classical ML libraries. Tools like scikit-learn, XGBoost, LightGBM, and CatBoost dominate tabular data. They are the standard for structured datasets, where deep learning rarely beats them (our test below shows why).
The second layer is deep learning frameworks. PyTorch, TensorFlow, JAX, and Keras (which often sits on top of these backends) handle neural network training and inference. This layer has become the default for large language models and computer vision.
The third layer includes model libraries and hubs. Hugging Face Transformers is the prime example. It provides pre-trained architectures and tokenizers that sit on top of the deep learning framework, allowing developers to load and fine-tune models without building the underlying tensor operations from scratch.
The fourth layer comprises runtimes that serve trained models. ONNX Runtime, LiteRT, ExecuTorch, vLLM, and TensorFlow.js are designed for deployment. They optimize inference for specific hardware, whether that is a mobile phone, a browser, or a data center GPU. Understanding which layer a tool belongs to helps you avoid choosing the wrong tool for the job.
PyTorch: what it is used for
PyTorch is the main framework for deep learning research and for large language models. It runs code line by line like ordinary Python (“eager” execution), so models are easy to debug and change, and since version 2.0 torch.compile can speed them up without rewriting. In January 2020 OpenAI announced it was standardizing on PyTorch. Typical jobs: training and fine-tuning neural networks for text, images and audio, serving LLMs through vLLM, recommender systems at scale with TorchRec, and on-device AI with ExecuTorch.
import torch
from torch import nn

model = nn.Sequential(nn.Linear(30, 64), nn.ReLU(), nn.Linear(64, 2))
optimizer = torch.optim.Adam(model.parameters(), lr=1e-3)
loss_fn = nn.CrossEntropyLoss()

# X_train, y_train: tensors with your data
for epoch in range(200):            # you write the training loop yourself
    optimizer.zero_grad()
    loss = loss_fn(model(X_train), y_train)
    loss.backward()                 # autograd computes the gradients
    optimizer.step()
That explicit loop is the PyTorch style: more code than Keras, but full control over every step, which is why researchers and LLM teams prefer it. The full walkthrough is in our PyTorch guide.
Meta, which created PyTorch, is one of its largest production users. In June 2021 it said it was moving all its AI systems to PyTorch and already ran more than 1,700 PyTorch inference models in production. In December 2022 it reported 70 billion daily on-device inferences from 50 PyTorch models in Instagram, Facebook and Messenger. This on-device push continues with ExecuTorch 1.0, released in October 2025. ExecuTorch enables efficient model execution on edge devices, powering features in Instagram, WhatsApp, Messenger, and Meta Ray-Ban Display wearables.
It is also how many companies adapt and serve their own language models. A Shopify case study from September 2026 is a good example. Shopify built a GraphQL agent that handles up to 2,000 requests per minute. They fine-tuned the model using PyTorch (SFT + GRPO) and served it with vLLM. The result was a 96% reduction in serving costs, dropping from an estimated $27 million annually to roughly $1 million, alongside a 38% reduction in end-to-end latency.
PyTorch is not only for neural networks. In June 2026, LinkedIn rebuilt its DuaLip linear-programming solver for job matching and email volume from Scala/Spark to GPU-based PyTorch. The new implementation ran 75 times faster per iteration on eight GPUs.
PyTorch is governed independently: the PyTorch Foundation under the Linux Foundation was set up in September 2022, with a board including AMD, AWS, Google Cloud, Meta, Microsoft Azure, and NVIDIA. In May 2025, it became an umbrella foundation, hosting projects like vLLM, DeepSpeed, and Ray. The current version is 2.14 (September 2026; 2.14.1 followed on 30 September). It runs on NVIDIA GPUs through CUDA, AMD GPUs through ROCm, Intel GPUs, Apple silicon through Metal (MPS), and on Google TPUs through the new TorchTPU, which replaces PyTorch/XLA; that project’s repository is due to be archived on 15 November 2026.
TensorFlow: what it is used for
TensorFlow is Google’s end-to-end machine learning platform, open-sourced in 2015. It is used to train models and, above all, to run them in production: data pipelines and serving with TFX and TensorFlow Serving, phones and embedded devices through LiteRT, browsers through TensorFlow.js, and recommendation models through TensorFlow Recommenders. Most people now write TensorFlow models through Keras. More in our TensorFlow guide.
Its on-device runtime, LiteRT (formerly TensorFlow Lite), was renamed in September 2024 and now runs models from other frameworks too. LiteRT supports models authored in PyTorch, JAX, and TensorFlow, and it runs on Android, iOS, Linux, and microcontrollers. It is embedded in major Google apps like YouTube, Google Photos, Gmail, and Maps. The browser ecosystem is also covered by TensorFlow.js.
TensorFlow’s own case-study page, mostly written between 2017 and 2021, shows the kind of work it was chosen for: Airbnb classified listing photos, Twitter ranked its home timeline (2019), Spotify built its recommendation pipelines on TFX and Kubeflow (2019), PayPal used it for fraud detection, GE Healthcare identified anatomy in brain MRI scans (2019), NAVER Shopping sorted more than 20 million new products a day into about 5,000 categories, and the ad exchange OpenX served more than a million requests a second with TFX.
The 2026 picture is quieter. TensorFlow 2.21 was released in March 2026. As of October 21, 2026, no newer release has occurred. The tf.lite module is moving to the separate LiteRT repository, and Hugging Face Transformers v5, released in January 2026, dropped TensorFlow support in favor of PyTorch. Google has not announced any change in TensorFlow’s status, and it remains a sound choice for systems already built on it, particularly where TensorFlow.js, TFX or TensorFlow Recommenders are in use; for new deep learning projects most teams now start elsewhere.
Keras: what it is used for
Keras is a high-level API designed to reduce the number of lines of code required to build neural networks. It abstracts the underlying framework, allowing developers to prototype quickly. Keras 3, released in November 2023, is a multi-backend rewrite that can run on JAX, TensorFlow, or PyTorch. It also supports OpenVINO for inference only. The same model code can switch backend with one setting:
import os
os.environ["KERAS_BACKEND"] = "torch"   # or "jax" or "tensorflow", set before importing keras
import keras

model = keras.Sequential([
    keras.Input(shape=(30,)),
    keras.layers.Dense(64, activation="relu"),
    keras.layers.Dense(1, activation="sigmoid"),
])
model.compile(optimizer="adam", loss="binary_crossentropy", metrics=["accuracy"])
model.fit(X_train, y_train, epochs=20)   # the training loop is built in
The framework is ideal for prototyping, teaching, and production workflows where simplicity is key. Keras says it is used by more than 2.5 million developers and powers the Waymo self-driving fleet and YouTube’s recommendation engine. See our Keras guide for both of its model-building APIs. The latest version, 3.15, continues to support this multi-backend approach, giving teams the flexibility to switch backends without rewriting their model definitions. This makes Keras a practical choice for teams that want to keep their model code decoupled from the underlying hardware or training engine.
scikit-learn: what it is used for
scikit-learn is the standard for classical machine learning on tabular data. It provides tools for classification, regression, clustering, preprocessing pipelines, and model evaluation. It is not designed for deep learning, but it remains the most used library among Python ML users. In the JetBrains/PSF Python Developers Survey 2024, 68% of the respondents who work with machine learning used it, up from 67% a year earlier. Every model follows the same fit() and predict() pattern, and preprocessing and model chain into one pipeline:
from sklearn.datasets import load_breast_cancer
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import cross_val_score

X, y = load_breast_cancer(return_X_y=True)          # 569 rows, 30 numeric columns
model = make_pipeline(StandardScaler(), LogisticRegression(max_iter=1000))
print(cross_val_score(model, X, y, cv=5).mean())    # about 0.98 accuracy
Its official testimonials, mostly from the 2010s, show typical uses: J.P. Morgan for classification and predictive analytics across the bank. Booking.com relies on it for hotel recommendations, fraudulent reservation detection, and customer-service scheduling. Spotify uses it for music recommendations, and Zopa applies it to credit risk, fraud, marketing, and pricing models. Change.org uses its RandomForestClassifier for email targeting.
Version 1.9 (June 2026; 1.9.1 in September) extends experimental GPU support: with PyTorch or CuPy arrays, models such as LogisticRegression can run on a GPU, though the project itself says the GPU experience is not yet as good as the default NumPy path. The library also improves handling of missing values in trees and supports sparse arrays. For any project on structured data, it is the default place to start. Details in our scikit-learn guide.
JAX: what it is used for
JAX, from Google, looks like NumPy but adds composable function transformations: grad for automatic differentiation, jit to compile a function with the XLA compiler, and vmap to vectorize it. The same code runs on CPUs, GPUs and Google’s TPUs. It is used mainly for very large training runs and for scientific computing, where that compilation and scaling matter more than convenience.
import jax
import jax.numpy as jnp

def loss(w, x, y):
    return jnp.mean((x @ w - y) ** 2)

grad_fn = jax.jit(jax.grad(loss))    # differentiate, then compile with XLA
w = w - 0.01 * grad_fn(w, x, y)      # one gradient-descent step
The practical applications of JAX are visible in some of the largest AI systems built recently. Google’s Gemini technical report (December 2023) describes training on TPU v4 and v5e with JAX and Pathways. Apple’s 2024 report on its Foundation Models says they were trained on TPU v4 and v5p clusters with AXLearn, a deep learning library built on JAX. xAI said in 2023 that its training and inference stack is built on Kubernetes, Rust and JAX, and published Grok-1’s open weights with JAX example code.
JAX is also common in science: the published code of AlphaFold 2 and AlphaFold 3, Google DeepMind’s protein structure models, is built on JAX and the Haiku library. Google packages it as the “JAX AI stack”: Flax for neural network layers, Optax for optimizers, Orbax for checkpoints, Grain for data loading, MaxText for LLM training and Pathways for multi-host scaling. The current version is 0.12 (October 2026). JAX has a smaller community than PyTorch and fewer ready-made models, so it suits teams with large-scale or TPU-heavy work more than beginners.
Hugging Face Transformers: what it is used for
The Hugging Face Transformers library is the standard for working with pretrained models. It provides ready-made implementations for text, vision, audio, and multimodal architectures, allowing developers to load, fine-tune, and share models without building them from scratch. Version 5, released in January 2026, dropped TensorFlow and Flax and made PyTorch the only backend. Despite this shift, the library maintains a massive ecosystem with over 400 architectures and more than 750,000 compatible checkpoints on the Hugging Face Hub.
Transformers v5 streamlined the workflow by removing legacy dependencies. The minimum Python version is now 3.10, and the library adopts weekly minor releases to keep pace with rapid model development. It supports quantization configurations and interoperates with major inference engines like vLLM, SGLang, TensorRT-LLM, llama.cpp, and MLX. Three lines are enough to run a pretrained model:
from transformers import pipeline

classifier = pipeline("text-classification",
                      model="distilbert/distilbert-base-uncased-finetuned-sst-2-english")
print(classifier("The new release fixed every bug I reported."))
# [{'label': 'POSITIVE', 'score': 0.99...}]
Hugging Face said in December 2025 that the library was installed more than 3 million times a day through pip, up from 20,000 a day when version 4 launched. By standardizing on PyTorch, Hugging Face has aligned the library with the dominant training framework, reducing friction for developers who train a model in PyTorch and then want to fine-tune or serve it using the same ecosystem.
XGBoost, LightGBM and CatBoost: what they are used for
When the data is tabular, gradient-boosted decision trees (GBDTs) remain the dominant approach. XGBoost, LightGBM, and CatBoost are the three primary libraries for this task. They excel at fraud detection, credit scoring, pricing optimization, demand forecasting, and ranking tasks. Deep learning dominates images, text and audio, but on tables of numbers boosted trees usually train faster and predict better than neural networks, as our own test below shows. They share scikit-learn’s interface:
from xgboost import XGBClassifier

clf = XGBClassifier(n_estimators=300, learning_rate=0.05, max_depth=4)
clf.fit(X_train, y_train)            # same fit/predict interface as scikit-learn
print(clf.score(X_test, y_test))
Competitions confirm it. The ML Contests reports counted gradient-boosting libraries in winning solutions: LightGBM 16, CatBoost 13 and XGBoost 8 in 2024; XGBoost and LightGBM 14 each and CatBoost 8 in 2025. The pattern is old: the 2016 XGBoost paper counted 17 of 29 Kaggle winning solutions published in 2015 using it, and every top-10 team at KDD Cup 2015.
Several major companies rely on these libraries for critical infrastructure. Uber used massive XGBoost ensembles for its ETA predictions for years before transitioning to DeepETA. Stripe Radar relied on an XGBoost and DNN “Wide & Deep” ensemble for fraud detection until 2022; Stripe wrote that simply removing XGBoost would have cost 1.5% of recall, which is why the switch to a pure neural network took work.
Runtimes: running trained models in production
Training a model is one thing; serving it at scale is another. Runtimes bridge the gap between a trained model and the end user. ONNX and ONNX Runtime are critical here. ONNX is an open file format for both deep learning and classical models, so a model trained in PyTorch, TensorFlow or scikit-learn can be exported once and run by ONNX Runtime on many kinds of hardware. Microsoft built it for its own products: at version 1.0 in 2019 it already ran more than 60 models in Office, Bing, Windows and Skype, handling billions of requests a day. With Windows ML generally available in September 2025, the runtime is now deeply integrated into the Windows ecosystem, supported by execution providers from AMD, Intel, NVIDIA, and Qualcomm.
For edge and mobile devices, LiteRT (formerly TensorFlow Lite) and ExecuTorch are the standards. LiteRT supports models from PyTorch, JAX, and TensorFlow, accelerating inference on CPUs, GPUs, and NPUs across Android, iOS, and embedded systems. It powers apps like YouTube, Google Maps, and Gmail. ExecuTorch, released in version 1.0 in October 2025, brings similar on-device capabilities to the PyTorch ecosystem, supporting backends like Core ML, Vulkan, and Qualcomm NPUs.
In the browser, TensorFlow.js and ONNX Runtime Web allow models to run directly in JavaScript environments. For large language models, vLLM is one of the most widely used serving engines. It came out of UC Berkeley, manages GPU memory with a technique called PagedAttention, is built on PyTorch (it is now a PyTorch Foundation project) and runs on NVIDIA, AMD and Intel GPUs and CPUs, with support for more than 200 Hugging Face model architectures.
AI frameworks by the numbers (October 2026)
There is no single “market share” for AI frameworks, so we looked at four independent signals ourselves on 20–21 October 2026, and checked them against the surveys.
What people say they use. In the JetBrains and Python Software Foundation Python Developers Survey 2024 (more than 30,000 respondents, 38% of whom train or run ML models), scikit-learn was used by 68% of the ML users, PyTorch by 66%, TensorFlow by 49%, Keras by 30%, Hugging Face Transformers by 28% and XGBoost by 23%. PyTorch gained six points in a year; TensorFlow was flat. The Stack Overflow Developer Survey 2024 shows the same turn among all developers: PyTorch at 10.6% and TensorFlow at 10.1%, the first year PyTorch was level or ahead after TensorFlow led in 2022 (13.0% vs 8.6%) and 2023. The 2025 Stack Overflow survey did not ask about these libraries.
What gets installed. Downloads from PyPI, the Python package index, in the 30 days to 20 October 2026:
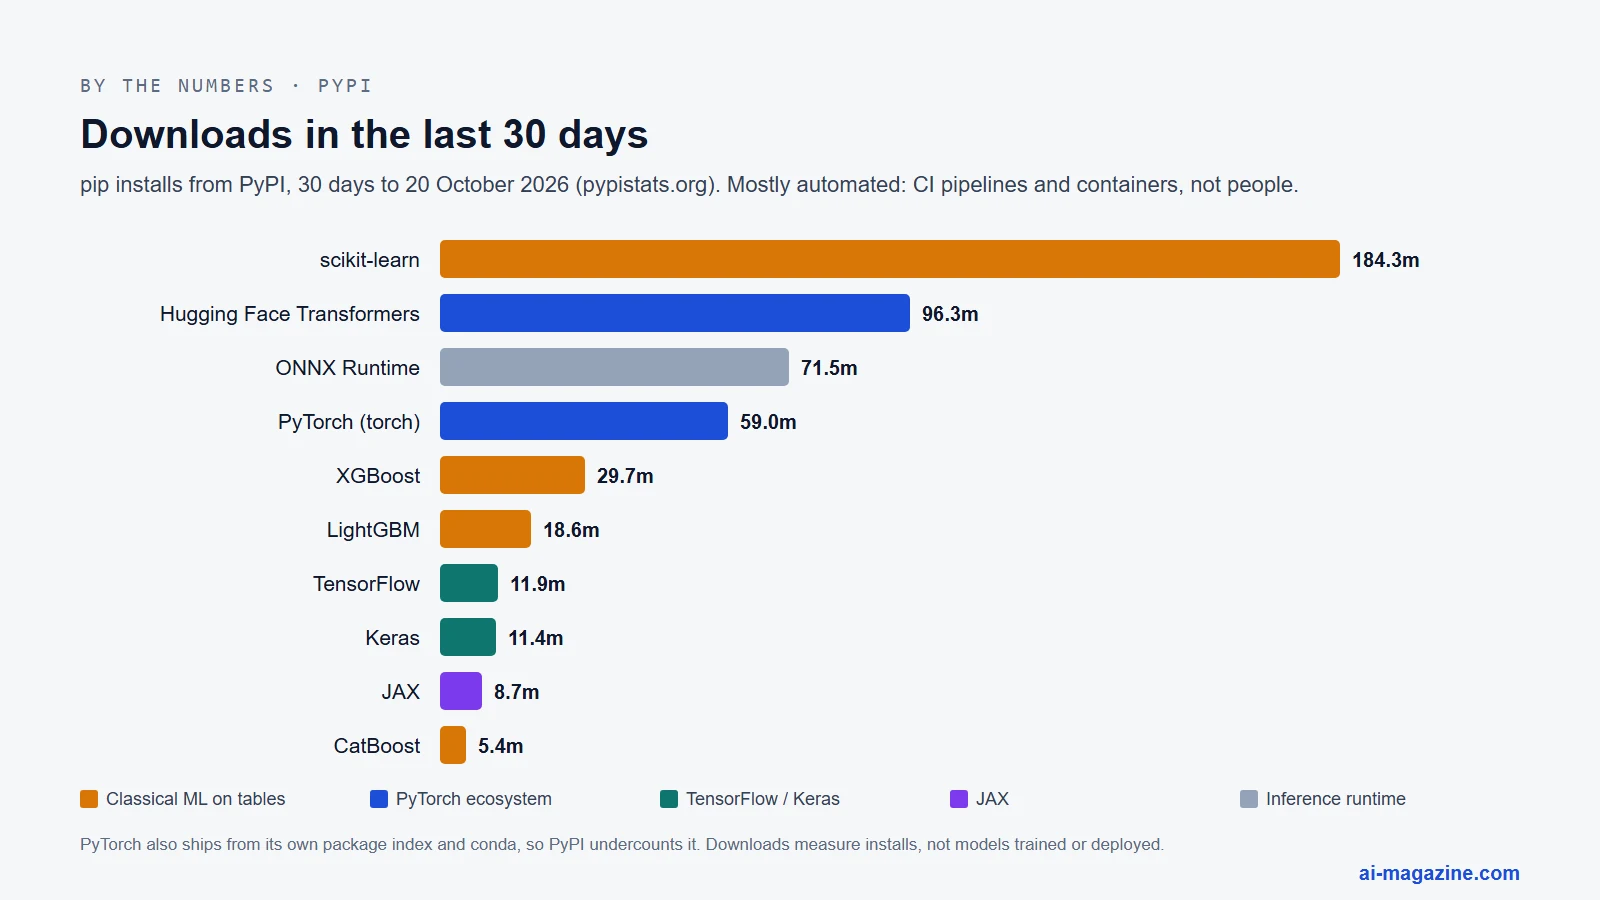
Download counts are dominated by automated installs in build pipelines and containers, and PyTorch is also distributed through its own package index and conda, so PyPI undercounts it. Two things still stand out: scikit-learn is installed more than any deep learning framework, because almost every data project needs it at some point, and PyTorch’s torch package is pulled five times as often as tensorflow.
What gets shared. On the Hugging Face Hub, the main place where trained models are published, we counted public models by library tag on 21 October 2026:
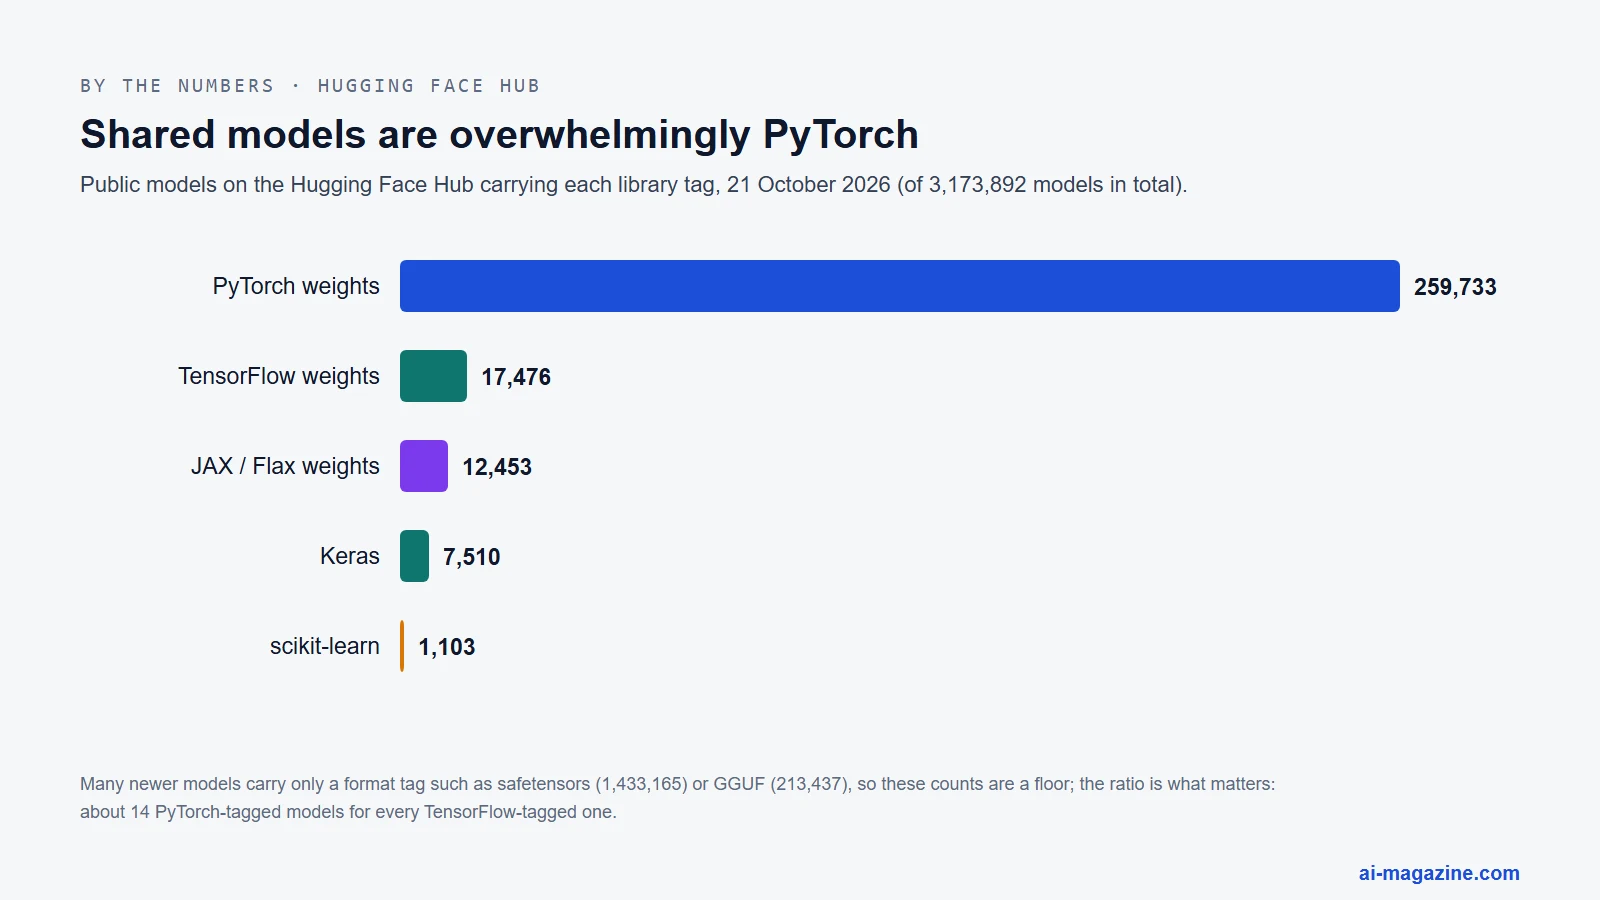
About 15 models carry a PyTorch tag for every one with a TensorFlow tag. The absolute numbers understate everything, because most newer models are tagged only by file format (1.43 million carry safetensors, 213,000 gguf), but the ratio matches what the Transformers team decided in 2026 when it made PyTorch its only backend.
What wins. The ML Contests reports, which analyze winning solutions across hundreds of machine learning competitions a year, found 44 winners using PyTorch, 1 TensorFlow and none JAX in 2025 (53 to 7 in 2024). On tabular competitions, gradient boosting still rules: XGBoost and LightGBM appeared in 14 winning solutions each in 2025 and CatBoost in 8.
| Signal (October 2026 unless noted) | PyTorch | TensorFlow | scikit-learn | Keras | JAX |
|---|---|---|---|---|---|
| Python ML users, JetBrains/PSF 2024 | 66% | 49% | 68% | 30% | n/a |
| PyPI downloads, last 30 days | 59.0m | 11.9m | 184.3m | 11.4m | 8.7m |
| Hugging Face models tagged | 259,733 | 17,476 | 1,103 | 7,510 | 12,453 |
| GitHub stars | 104,900 | 201,200 | 67,800 | 64,400 | 36,500 |
| Competition winners, 2025 (deep learning) | 44 | 1 | n/a | n/a | 0 |
| Latest release | 2.14.1 (Sep 2026) | 2.21 (Mar 2026) | 1.9.1 (Sep 2026) | 3.15.1 (Jul 2026) | 0.12.0 (Oct 2026) |
GitHub stars are the one signal where TensorFlow still leads, but stars are never taken back: they add up over a project’s whole life since 2015 and measure accumulated attention more than current use.
Our test: the same two jobs in five frameworks
“Use scikit-learn for tables and PyTorch for images” is common advice. On 21 October 2026 we checked it on an ordinary laptop CPU, running two standard datasets through scikit-learn, XGBoost, LightGBM, PyTorch and Keras (on its TensorFlow backend) with the same train/test split for every tool.
- Job A, a table: the California housing dataset, 20,640 districts described by 8 numbers (income, house age, rooms, location and so on). Predict the median house value.
- Job B, images: Fashion-MNIST, 70,000 small grayscale photos of clothing in 10 classes (shirts, sneakers, bags…). Predict the class.
The neural networks were deliberately ordinary: a two-layer network for the table, and a small two-layer convolutional network trained for 8 passes over the data for the photos, written the same way in PyTorch and in Keras. The tree models used common settings without tuning.
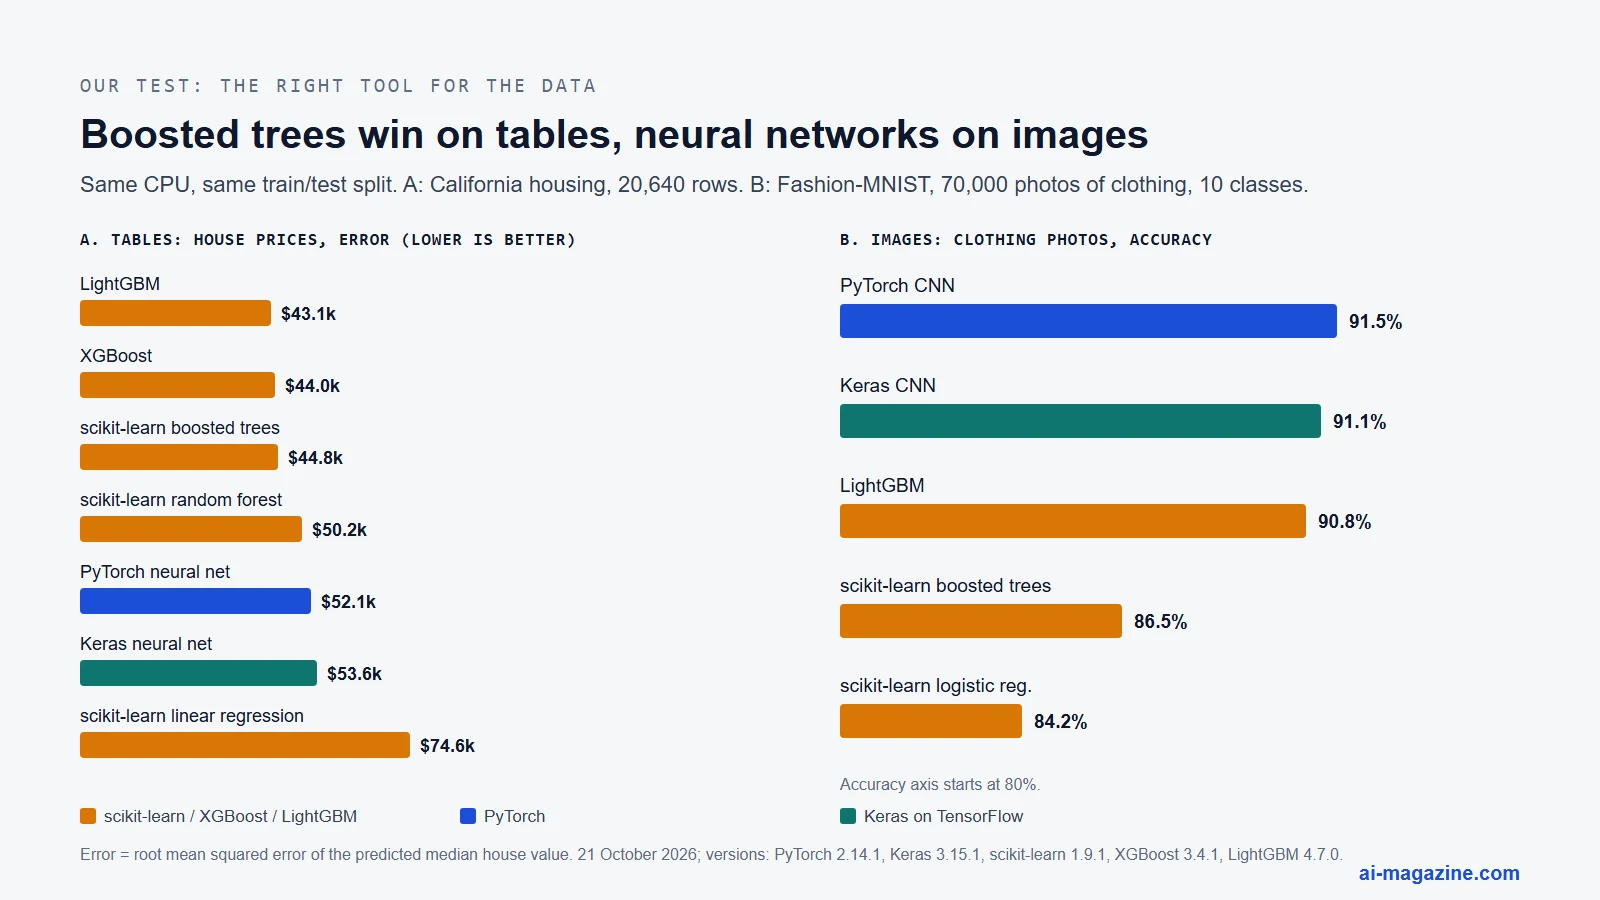
| Tool | A. House prices: error | A. Training time | B. Clothing photos: accuracy |
|---|---|---|---|
| LightGBM | $43,100 | 2 s | 90.8% |
| XGBoost | $44,000 | 5 s | not run |
| scikit-learn boosted trees (HistGradientBoosting) | $44,800 | 1.5 s | 86.5% |
| scikit-learn random forest | $50,200 | 18 s | not run |
| PyTorch neural network | $52,100 | 52 s | 91.5% (CNN) |
| Keras neural network | $53,600 | 21 s | 91.1% (CNN) |
| scikit-learn linear regression | $74,600 | 0.01 s | 84.2% (logistic regression) |
Error is the root mean squared error of the predicted value; always guessing the average would give $114,500.
On the table, the boosted trees won outright. LightGBM, XGBoost and scikit-learn’s own gradient boosting were all within $1,700 of each other and trained in seconds. Both neural networks had 21% to 24% higher error and trained more slowly, even though they took more code to write. This is the same result the competition data shows, and why banks, marketplaces and fraud teams still run XGBoost and LightGBM.
On the photos, the order flipped, but less than you might expect. The small convolutional networks in PyTorch and Keras were the most accurate, at 91.5% and 91.1%, because convolutions are built to find edges and shapes in neighboring pixels. LightGBM, which sees each image as 784 unrelated numbers, came surprisingly close at 90.8%, but needed a large model and over ten minutes to get there, while scikit-learn’s logistic regression stopped at 84.2%. Fashion-MNIST is a small, easy image set; on real photos, and anything with text or audio, the gap in favor of neural networks grows quickly, and that is where PyTorch and pretrained models take over.
PyTorch and Keras gave practically the same answer. For identical networks the difference was 0.4 points on the photos and $1,500 on the table, small enough that a different random seed could reverse it. The choice between them is about workflow (explicit training loops in PyTorch, a built-in fit() in Keras) and ecosystem, not accuracy. We do not compare their speed: PyTorch ran on 2 CPU threads by default in this run, while TensorFlow sets its own thread pools, so the timings are not like for like.
Limits: one run per model, CPU only, no tuning, two public datasets. A GPU would cut the neural networks’ training times sharply, and tuning would narrow some gaps. The direction of the result, trees for tables and neural networks for images, matches the larger benchmarks discussed in our machine learning algorithms guide.
Which framework for which task
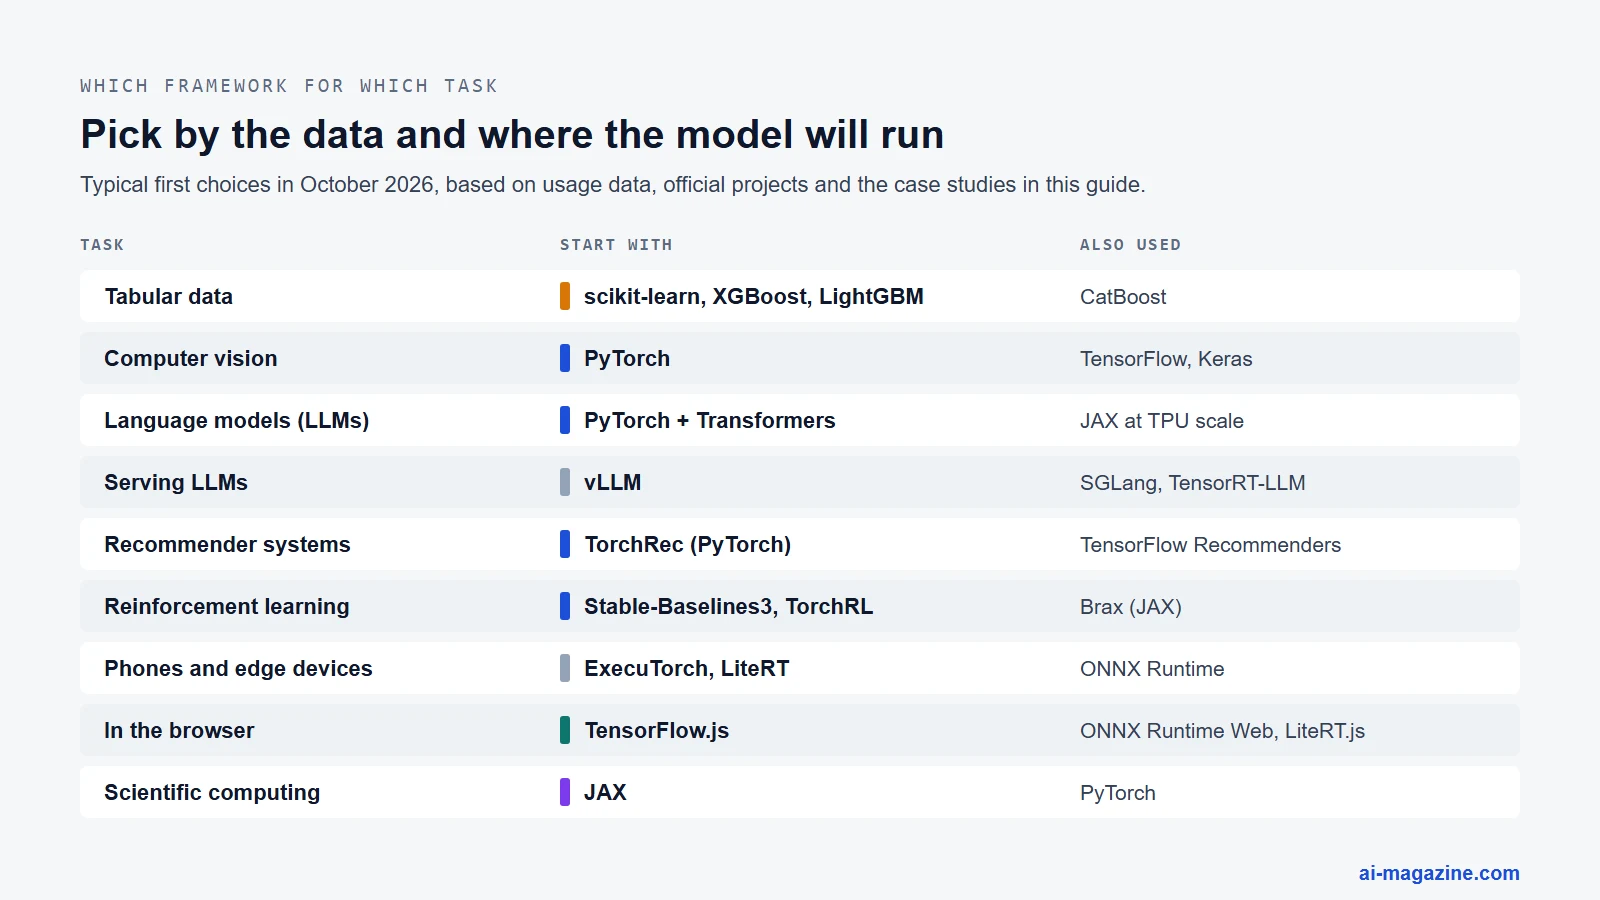
Choosing a framework depends on the data type and the hardware. For computer vision, PyTorch is the default for training new models; TensorFlow runs many older production systems, and LiteRT or ExecuTorch take models onto phones and cameras. For NLP and large language models, PyTorch combined with Hugging Face Transformers is the default for training and fine-tuning, while vLLM handles serving. Tabular and structured data tasks are best served by scikit-learn for baseline models and GBDTs like XGBoost or LightGBM for high-performance predictions.
Recommender systems often use TorchRec for embedding sharding at scale or TensorFlow Recommenders for end-to-end workflows. Reinforcement learning has specialized tools: Stable-Baselines3 and TorchRL for PyTorch, and Brax for JAX. Mobile and edge deployments rely on ExecuTorch or LiteRT, while browser-based inference uses TensorFlow.js or ONNX Runtime Web. Scientific computing uses JAX for its NumPy-like code and gradient transformations (AlphaFold is the best-known example), while PyTorch has its own science projects such as NeuralOperator and PINA.
| Task | First choice | Also used | Example |
|---|---|---|---|
| Computer vision | PyTorch | TensorFlow, Keras | Tesla Autopilot (PyTorch, 2019), GE Healthcare MRI (TensorFlow, 2019) |
| NLP and LLMs | PyTorch + Transformers | JAX | Hugging Face Hub (PyTorch), Google Gemini (JAX) |
| Tabular data | scikit-learn, XGBoost, LightGBM | CatBoost | Stripe Radar (XGBoost), Uber ETA (XGBoost) |
| Recommender systems | TorchRec | TensorFlow Recommenders | Meta production (TorchRec), YouTube (Keras) |
| Reinforcement learning | Stable-Baselines3 (PyTorch) | TorchRL, Brax (JAX) | OpenAI Spinning Up rewritten in PyTorch (2020) |
| Mobile and edge | ExecuTorch or LiteRT | ONNX Runtime | Instagram, WhatsApp (ExecuTorch); YouTube, Google Photos (LiteRT) |
| Browser | TensorFlow.js | ONNX Runtime Web | InSpace toxicity filter (TF.js) |
| Scientific computing | JAX | PyTorch | AlphaFold 3 (JAX), PINA (PyTorch) |
How to choose an AI framework
- Start with your data type. If it is tabular, use scikit-learn for baselines and XGBoost or LightGBM for performance. If it is unstructured, move to deep learning frameworks.
- For deep learning, PyTorch is the default choice for most developers. It offers a flexible, Pythonic interface that aligns with research papers.
- Use JAX if you train at large scale on Google TPUs or do scientific computing; it is what Google, Apple (AXLearn) and xAI have described using for their large models.
- Choose Keras 3 if you want backend freedom. It allows you to switch between JAX, TensorFlow, and PyTorch without changing your code.
- Pick Transformers if you need pretrained models. It is the standard for NLP and multimodal tasks.
- Let your deployment target decide the runtime. Use ONNX Runtime for cross-platform consistency, LiteRT for edge devices, or vLLM for LLM serving.
- Check your team’s skills. PyTorch has the largest deep learning community (66% of Python ML users in the JetBrains/PSF 2024 survey, against 49% for TensorFlow), which also means more tutorials, answers and ready-made models.
- Watch maintenance signals. TensorFlow’s last release was 2.21 in March 2026 and Transformers v5 dropped it, while PyTorch, scikit-learn and JAX all released in the past two months.
Frequently asked questions
What are AI frameworks? AI frameworks are software libraries that simplify the creation of machine learning models. They provide tools for data handling, model architecture definition, training loops, and deployment. Examples include PyTorch, TensorFlow, JAX, and scikit-learn.
What is the most popular AI framework? It depends on the job. scikit-learn is the most used library overall (68% of Python ML users in 2024, and the most downloaded), while PyTorch is the most used deep learning framework: 66% of Python ML users, 44 of 45 deep-learning competition winners in 2025, and about 15 times as many Hugging Face models as TensorFlow. In the 2024 Stack Overflow survey, PyTorch (10.6%) drew level with and passed TensorFlow (10.1%) for the first time.
What is PyTorch used for? PyTorch is used for deep learning research, computer vision, and NLP. It is the standard for training large language models and powering on-device AI. Meta runs its apps’ AI on it, Shopify fine-tunes and serves its own models with it, and Amazon Ads has used it to screen ads.
What is TensorFlow used for? TensorFlow is used to train and especially to deploy models in production: TFX pipelines, TensorFlow Serving, on-device apps through LiteRT and in-browser models with TensorFlow.js. Companies have used it for recommendations (Spotify), fraud detection (PayPal) and medical imaging (GE Healthcare).
Is TensorFlow still worth learning in 2026? Learn it if your job involves existing TensorFlow systems, TFX pipelines or TensorFlow.js. For a first deep learning framework, PyTorch is the safer bet in 2026: it is more widely used, it is the only backend of Hugging Face Transformers, and it releases more often. Keras 3 lets you learn one high-level API and run it on either.
Is scikit-learn an AI framework? scikit-learn is a machine learning library rather than a deep learning framework, and it is the most widely used of all. It specializes in traditional algorithms like linear regression, decision trees, and support vector machines. It is the go-to tool for tabular data and baseline models.
Which framework is used to build large language models? Most open large language models are built and fine-tuned with PyTorch, and Hugging Face Transformers and vLLM are built on it. JAX is the other option at the very top end: Google described training Gemini with JAX, and Apple its Foundation Models with the JAX-based AXLearn, both on TPUs.
Related
- PyTorch: What It Is, Its Real History, and How to Use It
- TensorFlow: What It Is, Its Real History, and How to Use It
- Keras: What It Is, How It Works, and How to Use It in 2026
- scikit-learn: The Machine Learning Library That Isn’t Deep Learning
- Machine Learning Algorithms: Types, How They Work and How to Choose One