AI Algorithms for Computer Vision: From Edge Detection to 3D, Video and Robots
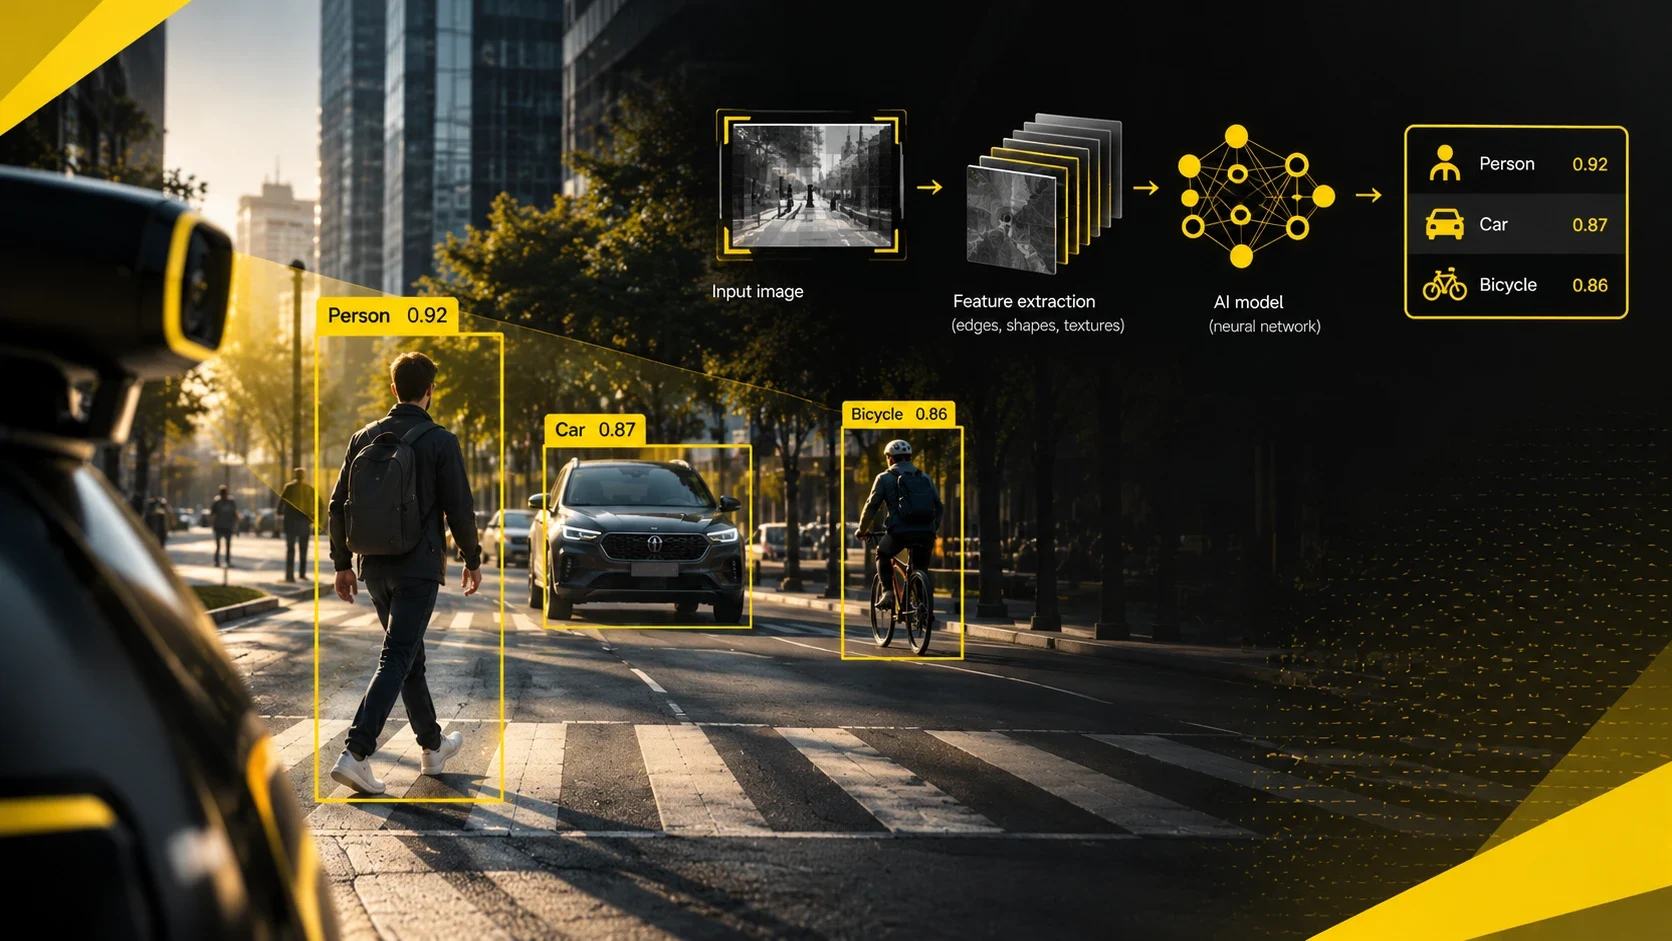
Computer vision is the field of AI that turns pixels into usable information: what is in a scene, how it moves, how far away it is, what text it contains, and what a robot or car should do next. Image recognition, telling a cat from a dog, is only the best-known part. The same field covers motion tracking in sports broadcasts, the 3D maps behind AR apps, document scanners that read invoices, and the cameras that let a driverless car cross an intersection.
This guide maps the main families of computer vision algorithms, from 1980s methods that still ship in every OpenCV install to 2025–2026 foundation models, and gives the verified numbers behind each. Classification, object detection and segmentation are covered in depth in our companion guide, AI Algorithms for Image Recognition, so here they get a short summary.
What computer vision algorithms do
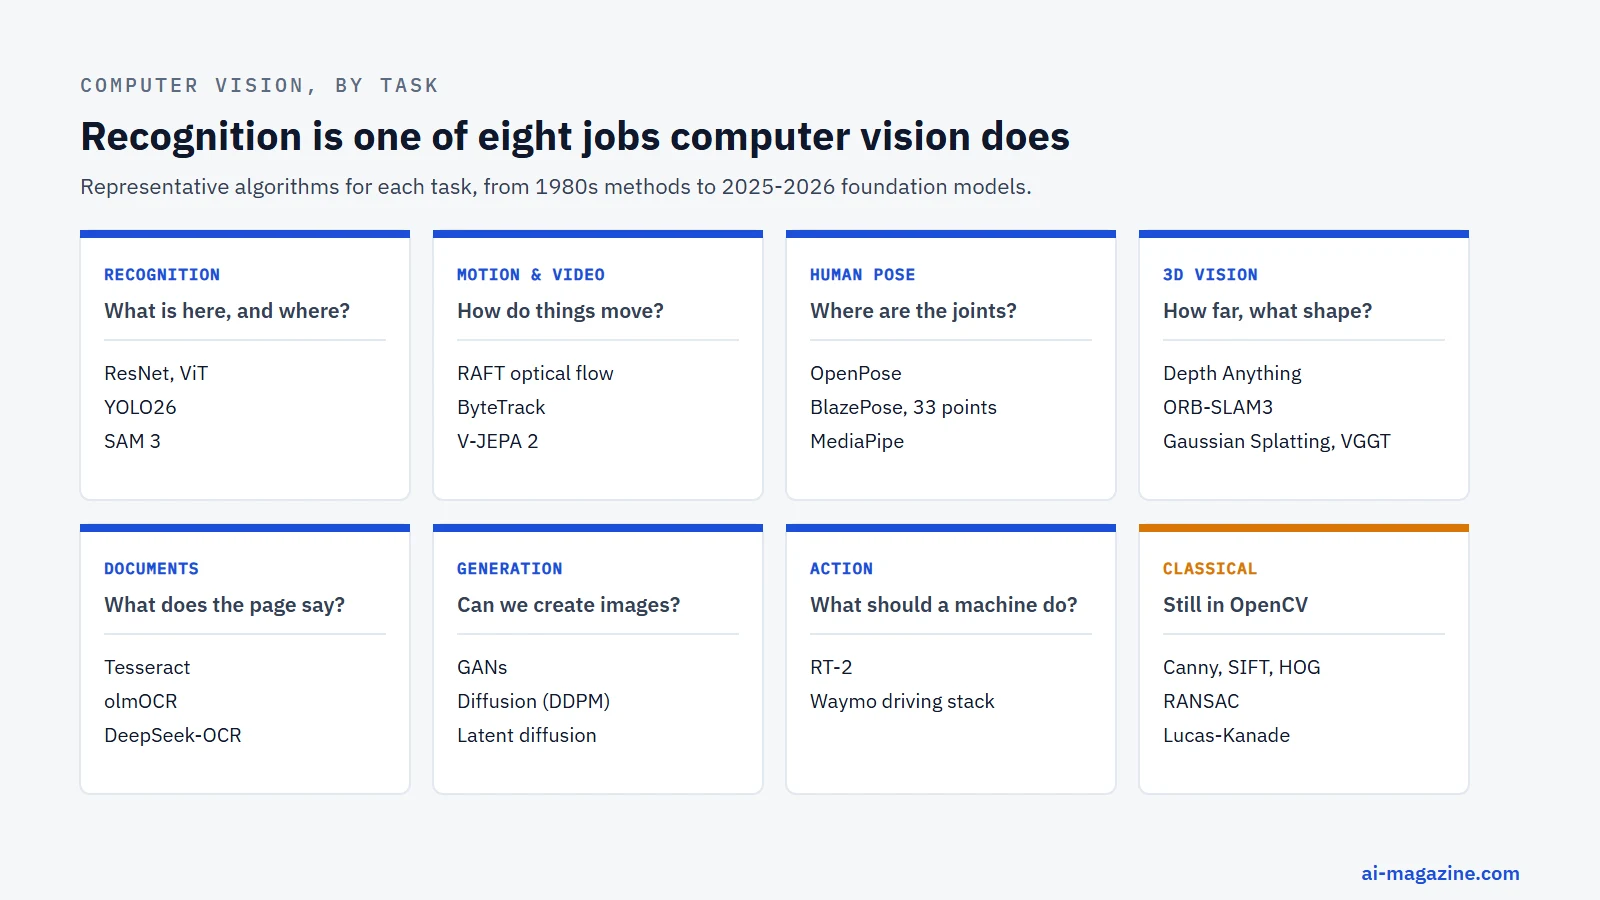
| Task | Question it answers | Representative algorithms |
|---|---|---|
| Recognition | What is in the image, and where? | ResNet, Vision Transformer, YOLO26, Segment Anything |
| Motion and video | How do things move between frames? | Lucas–Kanade, RAFT, SORT, ByteTrack, V-JEPA 2 |
| Human pose | Where are a person’s joints? | OpenPose, BlazePose, MediaPipe |
| 3D vision | How far away is everything, and what shape is it? | Depth Anything, ORB-SLAM3, NeRF, Gaussian Splatting, VGGT |
| Documents | What text and layout does the page contain? | Tesseract, TrOCR, olmOCR, DeepSeek-OCR |
| Generation | Can we create or edit realistic images? | GANs, diffusion models |
| Action | What should a robot or vehicle do next? | RT-2, driving stacks such as Waymo’s |
Classical algorithms that still run everywhere
Deep learning did not erase the older toolbox. Many of these methods are fast, need no training data, and remain inside production pipelines, usually through OpenCV, the open-source library most “computer vision with Python” tutorials start with. OpenCV 5.0.0, the first stable 5.x release, came out in June 2026, and the 4.x line continues with 4.14.0 (July 2026).
| Algorithm | Year | What it does | Where it is still used |
|---|---|---|---|
| Lucas–Kanade | 1981 | Estimates motion between frames from image gradients | Feature tracking, video stabilization |
| RANSAC | 1981 | Fits a model while ignoring outlier points | Image stitching, 3D reconstruction, SLAM |
| Canny edge detector | 1986 | Finds clean, thin edges | Preprocessing, measurement, document cropping |
| SIFT | 1999 / 2004 | Finds distinctive keypoints that survive scaling and rotation | Panorama stitching, matching photos of the same place |
| Viola–Jones | 2001 | Real-time face detection with a cascade of simple features | Low-power cameras, legacy face detection |
| HOG | 2005 | Describes shape through histograms of edge directions | Lightweight pedestrian and object detection |
Two details show how far the field has moved. Viola and Jones reported detecting faces in 384×288 images “at 15 frames per second on a conventional 700 MHz Intel Pentium III”. And SIFT, long the default for matching images, was patented by the University of British Columbia until the patent expired in March 2020, which is why it now ships freely in OpenCV.
The deep learning shift, in brief
From 2012, convolutional neural networks learned features directly from data and overtook hand-designed ones; from 2020, transformers joined them; and since 2023, large pre-trained “foundation” vision models have become the starting point for most new systems, adapted to specific jobs through transfer learning. For recognition tasks:
- Classification says what an image shows (ResNet, ConvNeXt, Vision Transformer, CLIP).
- Object detection adds bounding boxes (YOLO26, DETR family).
- Image segmentation outlines exact pixels (Mask R-CNN, Meta’s Segment Anything).
The benchmarks, model versions and failure modes for all three are in our image recognition guide. The rest of this article covers what computer vision does beyond recognition.
Motion and video
Optical flow estimates how every pixel moves between two frames. The classical Lucas–Kanade method tracks a sparse set of points. RAFT (Princeton, 2020), which won the Best Paper award at ECCV 2020, computes dense flow with a recurrent network. On the KITTI driving benchmark it cut the error rate to 5.10%, a 16% reduction from the previous best published result.
Multi-object tracking keeps a consistent ID on each object across frames, which is what turns per-frame detections into “this player ran 11 km”. SORT (2016) showed a simple approach, a detector plus a Kalman filter and frame-to-frame matching, could update at 260 Hz, “over 20x faster than other state-of-the-art trackers”. ByteTrack (2021) kept low-confidence detections that earlier trackers discarded and reached 80.3 MOTA and 63.1 HOTA on the MOT17 benchmark at 30 frames per second on one V100 GPU.
Video understanding goes beyond tracking to recognizing actions and predicting what happens next. VideoMAE (2022) learned from video by hiding 90–95% of it and reconstructing the missing parts, reaching 87.4% on the Kinetics-400 action benchmark without extra data. Meta’s V-JEPA 2 (June 2025), a 1.2-billion-parameter model, was pre-trained on more than one million hours of internet video and then on less than 62 hours of unlabeled robot video. Meta reports it could then plan pick-and-place tasks on robot arms in new labs zero-shot, with success rates of 65–80% on objects it had not seen.
Human pose estimation
Pose estimation finds a person’s joints, the basis for fitness apps, motion capture, sign-language research and workplace-safety analytics.
- OpenPose (Carnegie Mellon University, CVPR 2017) introduced “part affinity fields” to link joints to the right person in a crowd, and its later version was described as “the first open-source realtime system for multi-person 2D pose detection, including body, foot, hand, and facial keypoints”.
- BlazePose (Google, 2020) targeted phones: it “produces 33 body keypoints for a single person and runs at over 30 frames per second on a Pixel 2 phone”.
- MediaPipe Pose Landmarker, Google’s current on-device tool, outputs 33 three-dimensional landmarks plus an optional segmentation mask, in Lite, Full and Heavy model sizes.
3D vision: depth, mapping and reconstruction
Monocular depth estimation predicts distance from a single ordinary photo. MiDaS (Intel, 2019) showed that training on a mix of datasets, including 3D movies, made depth models generalize. Depth Anything (January 2024) scaled this with about 62 million unlabeled images; Depth Anything V2 (June 2024) replaced labeled real images with synthetic ones for sharper results, offers models from 25 million to 1.3 billion parameters, and is “more than 10x faster” than depth models built on Stable Diffusion. Depth Anything 3 (ByteDance Seed, November 2025, an ICLR 2026 oral) extends it to any number of views and recovers camera positions as well as depth.
SLAM (simultaneous localization and mapping) lets a robot, drone or AR headset build a map while tracking its own position in it. ORB-SLAM (2015) became a standard open-source system that “operates in real time, in small and large, indoor and outdoor environments”. ORB-SLAM3 (2020) added support for monocular, stereo and depth cameras with inertial sensors, and reported being “2 to 5 times more accurate than previous approaches”, with an average error of 3.6 cm on the EuRoC drone dataset.
Neural 3D reconstruction builds 3D scenes from photos:
- NeRF (neural radiance fields, ECCV 2020) represents a scene as a neural network that maps a 3D position and viewing direction to color and density, producing photorealistic new viewpoints but rendering slowly. See NeRF.
- 3D Gaussian Splatting (SIGGRAPH 2023) represents the scene as millions of small 3D Gaussians and achieves “real-time (>= 30 fps) novel-view synthesis at 1080p resolution”, fast enough for interactive use.
- VGGT (University of Oxford and Meta, CVPR 2025 Best Paper, chosen from more than 13,000 submissions) is a single feed-forward transformer that predicts cameras, depth and 3D points directly from one to hundreds of images. Its paper reports “reconstructing images in under one second”, against optimization-based pipelines that can take minutes or hours.
Documents and OCR
Optical character recognition is one of the oldest commercial vision tasks and one of the most changed by large models.
- Tesseract was developed at Hewlett-Packard between 1985 and 1994, open-sourced in 2005, maintained by Google from 2006 to 2017, and now recognizes more than 100 languages with an LSTM engine. Version 5.5.3 shipped in July 2026. It remains the default free OCR engine.
- TrOCR (Microsoft, 2021) replaced the traditional pipeline with a transformer that reads the image and generates text directly, improving results on printed, handwritten and scene text.
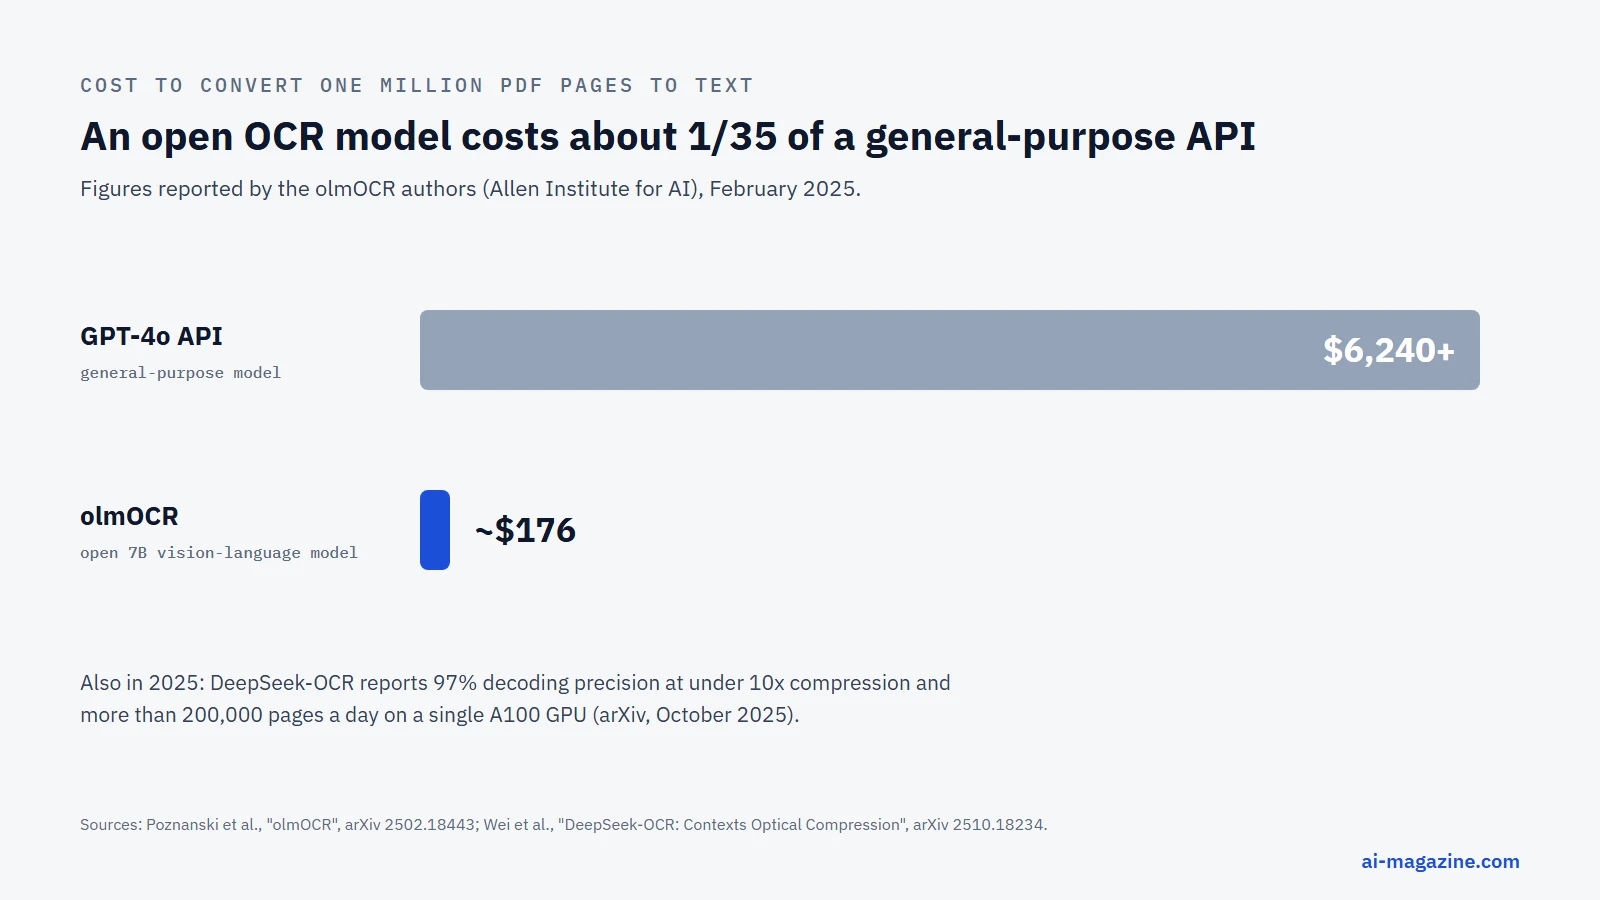
- Vision-language OCR now reads whole pages, including tables and layout. Allen AI’s olmOCR (February 2025), a fine-tuned 7-billion-parameter model, converts a million PDF pages for about $176, compared with more than $6,240 for the same job through the GPT-4o API, according to its authors.
- DeepSeek-OCR (October 2025) uses images as a compressed way to store text for language models. At under 10× compression it decodes text with 97% precision, and at 20× it still reaches about 60%. One A100 GPU can process more than 200,000 pages a day.
Generative vision
Computer vision also runs in reverse: generating images rather than analyzing them.
- GANs (Goodfellow et al., 2014) pit a generator against a discriminator that tries to tell fake samples from real ones. They dominated realistic image synthesis for years and power many deepfake tools. See generative adversarial network.
- Diffusion models (DDPM, Ho et al., 2020) learn to reverse a gradual noising process. DDPM reached a state-of-the-art FID of 3.17 on CIFAR-10. Latent diffusion (Rombach et al., CVPR 2022), the method behind Stable Diffusion, ran the process in a compressed latent space, cutting the “hundreds of GPU days” that pixel-space models needed.
The text-to-image side of this story is covered in Text-to-Image: How AI Turned Words Into Pixels.
Vision that acts: robots and driverless cars
The newest systems connect seeing to doing.
- Vision-language-action models. Google DeepMind’s RT-2 (July 2023) expressed robot actions “as text tokens” inside a vision-language model. Across more than 6,000 robot trials, it succeeded on 62% of unseen scenarios, against 32% for its predecessor RT-1.
- Driverless cars. Waymo’s vehicles combine cameras with lidar and radar, with computer vision models fusing the inputs. Waymo reports 271.3 million rider-only miles driven without a human driver through June 2026, and, compared with human drivers over the same distance, 95% fewer crashes causing serious injury or worse. In February 2026 it reported more than 400,000 rides a week across six US metropolitan areas.
Computer vision at war: drones in Russia’s war against Ukraine
Russia’s full-scale invasion of Ukraine has become the largest real-world use of computer vision in combat. Both sides field drones in the millions. Ukraine’s then Defence Minister Denys Shmyhal said in December 2025 that the armed forces would receive about 3 million FPV drones that year, and the Defence Ministry plans to produce more than 7 million drones in 2026. Ukraine’s foreign intelligence service estimated Russia’s 2025 target at 2 million FPV drones. Most of these are still flown by hand. Computer vision is being added for one reason above all: jamming.
Why jamming made vision essential
A small FPV (first-person view) drone is steered by an operator watching its camera feed over a radio link. Electronic warfare jams that link, most effectively close to the target, so the drone loses control in the last few hundred metres. In July 2024 a Ukrainian official told Reuters that the strike rate of most FPV units had fallen to 30–50%, and to as low as 10% for new pilots.
The answer is terminal guidance, also called “last-mile autonomy”. The operator picks the target on the camera image, the onboard computer locks on to it with object tracking, and the drone flies the final approach on its own, even if the radio link drops. CSIS analyst Kateryna Bondar, based on interviews with Ukrainian officials and manufacturers, reported in March 2025 that such autonomy raises the target engagement success rate “from around 10 to 20 percent to around 70 to 80 percent”, typically over the final 100 to 1,000 metres. The estimates differ by source, and almost all come from the Ukrainian side.
The other answer to jamming uses no computer vision at all: drones that trail a thin fibre-optic cable, usually 10–25 km long, which radio jamming cannot touch. Both sides now use them alongside camera-guided drones.
What Ukraine has deployed
- Targeting modules. In October 2024 Deputy Defence Minister Kateryna Chernohorenko told Reuters that “several dozen solutions” from Ukrainian manufacturers were being bought and delivered to the armed forces. One maker, NORDA Dynamics, said it had sold more than 15,000 units of its targeting software. Scale was still small: CSIS found that of nearly 2 million drones contracted in 2024, only about 10,000, under 0.5%, definitely used AI guidance. In 2025 The Fourth Law’s TFL-1 module went into Vyriy FPV drones for the final ~500 metres; the company claims it raises strike effectiveness 2–4 times for about 10% more cost.
- Reconnaissance that recognizes equipment. Ukraine’s Defence Ministry approved the Saker Scout drone in September 2023, saying it “independently recognises and records the coordinates of the enemy’s equipment (even camouflaged)” and sends them to command posts. Its developers later told Forbes it had carried out autonomous strikes, used “sparingly”; that claim has not been independently verified.
- Video analytics at scale. The Defence Ministry’s Avengers platform automatically analyses video from drones and fixed cameras. In September 2024 the ministry said it identified about 12,000 pieces of Russian equipment a week; by August 2026 it said the system processed more than 100,000 drone video streams a month.
- Swarms. The Ukrainian company Swarmer lets one operator assign a search area and order an attack, while the drones decide the order and timing among themselves, cutting a crew from nine people to three, according to the Wall Street Journal (September 2025). The company says a human must authorize every attack.
- Operation Spiderweb. In the 1 June 2025 attack on Russian airbases, Ukraine’s SBU security service said drones that lost their signal “switched to performing a mission using artificial intelligence along a pre-planned route”. The SBU claimed 41 aircraft were hit; the damage figures have not been independently verified.
- Interceptors. Against Russia’s Shahed-type long-range drones (about 6,500 were launched in March 2026, according to Ukrainian air force data reported by Reuters), interceptor drones now bring down about 40%, the air force says. Mykhailo Fedorov, who became Defence Minister in early 2026, said Ukraine is “working on automated drone guidance systems” for them.
What Russia is reported to use
Evidence on the Russian side comes mostly from Ukraine’s military intelligence (HUR), which examines downed drones, and from Russian marketing. Treat it accordingly.
- Lancet loitering munition. Its developers say it can fly to a designated area and scan it “for targets using the detection algorithm”. In March 2026 HUR said Russia was trying to add autonomous guidance elements to the Lancet using modules based on NVIDIA Jetson boards.
- V2U. In June 2025 HUR described a new Russian strike drone whose “key feature” is “its ability to autonomously search for and select targets using artificial intelligence”, built around an NVIDIA Jetson Orin module inside a Chinese-made computer, and used on the Sumy front.
- Shahed variants. HUR said in June 2025 that a downed Shahed-type drone carried an infrared camera and a Jetson Orin module that could “compare the image with downloaded models for automatic targeting or target selection”.
None of these claims of fully autonomous target selection, Ukrainian or Russian, has been independently confirmed.
The human cost
The clearest independent data comes from the UN Human Rights Monitoring Mission in Ukraine. In August 2025, it reported, short-range drones caused more civilian casualties than any other weapon, killing 58 civilians and injuring 272. In January 2026 the mission told Reuters that civilian casualties in 2025 rose 31% to 2,514 killed and 12,142 injured, and that short-range drones had “rendered many areas near the frontline effectively uninhabitable”.
Human in the loop, and the law
The systems described above differ in one critical respect: who chooses the target. In most deployed terminal-guidance systems, a person selects the target and computer vision only flies the last stretch. CSIS concluded that “engagement decisions remain squarely in the human domain”. A fully autonomous weapon, in the International Committee of the Red Cross definition, is one that can “select and apply force to targets without human intervention”. The ICRC calls for banning unpredictable autonomous weapons and those designed or used to apply force against people, and for strict limits on all others.
International rules are still being negotiated. The UN General Assembly passed its first resolution on lethal autonomous weapons in December 2023 by 152 votes to 4, with Russia among those voting against, and similar resolutions followed in 2024 and 2025. On 5 September 2026 the Convention on Certain Conventional Weapons expert group agreed by consensus on non-binding “elements of an instrument”. The UN Secretary-General and the ICRC president have called for negotiations on a legally binding treaty, pointing to the CCW Review Conference in Geneva on 16–20 November 2026.
How computer vision is measured
| Metric or benchmark | What it measures |
|---|---|
| IoU (intersection over union) | Overlap between a predicted box or mask and the true one |
| mAP (COCO) | Detection quality averaged over classes and IoU thresholds from 0.50 to 0.95 |
| mIoU (ADE20K, Cityscapes) | Segmentation quality per class; ADE20K has 150 categories, Cityscapes covers 50 cities |
| KITTI (2012) | Driving tasks: stereo, optical flow, odometry, 3D detection and tracking |
| MOTA, HOTA (MOT17) | Tracking quality; HOTA balances detection, association and localization |
| FID | How close generated images are to real ones (lower is better) |
Numbers on these benchmarks are only comparable within the same benchmark, split and metric, a point that matters when vendors quote headline scores.
Running vision on devices
Many vision systems must run on a camera, phone, drone or robot rather than in a data center, for latency, cost or privacy. That shapes the algorithm choice: small detectors such as YOLO26n (2.4 million parameters) and quantized models are built for it. On the hardware side, NVIDIA’s Jetson AGX Orin modules deliver up to 275 TOPS of AI performance at 15–60 W, the Orin Nano up to 40 TOPS, and the newer Jetson Thor up to 2,070 FP4 teraflops for more demanding robots.
Which approach for which job
| You need to | Start with |
|---|---|
| Crop, align or measure under controlled conditions | Classical OpenCV methods (Canny, RANSAC, template matching) |
| Detect or segment objects | YOLO26 or Segment Anything (see the image recognition guide) |
| Count and follow objects in video | A detector plus ByteTrack-style tracking |
| Measure body movement | MediaPipe Pose Landmarker or OpenPose |
| Estimate depth from a single camera | Depth Anything V2 |
| Map a space while moving | ORB-SLAM3 or a commercial AR SDK |
| Turn photos into a navigable 3D scene | Gaussian Splatting or VGGT |
| Extract text and tables from documents | Tesseract for plain text; a vision-language OCR model for complex layouts |
Frequently asked questions
What are the main computer vision algorithms?
Classical methods such as Canny edge detection, SIFT, HOG, RANSAC and Lucas–Kanade optical flow; deep learning models for recognition (CNNs, Vision Transformers, YOLO, Segment Anything); and specialized models for motion (RAFT, ByteTrack), pose (OpenPose, BlazePose), 3D (Depth Anything, ORB-SLAM, NeRF, Gaussian Splatting, VGGT), documents (Tesseract, vision-language OCR) and generation (GANs, diffusion).
Is computer vision the same as image recognition?
No. Image recognition, identifying what is in an image, is one part of computer vision. The field also covers motion, 3D geometry, pose, text reading, image generation and vision-guided action.
Which programming language is used for computer vision?
Python is the most common, through OpenCV and deep learning frameworks such as PyTorch. Performance-critical parts, including OpenCV itself, are written in C++.
Are classical computer vision algorithms still used?
Yes. Methods such as Canny, RANSAC and SIFT need no training data, run fast on small hardware and are still used for preprocessing, measurement, image stitching and 3D reconstruction, often alongside neural networks.
How is computer vision used in military drones?
Mainly for terminal guidance: an operator selects a target on the drone’s camera image, and onboard computer vision tracks it and flies the final approach, so the strike continues even if electronic warfare jams the radio link. It is also used to detect and map enemy equipment in reconnaissance video. In Russia’s war against Ukraine, most deployed systems keep a human in charge of choosing the target.
What is the newest trend in computer vision?
Foundation models that handle many tasks from one pre-trained network, such as DINOv3 for features, Depth Anything 3 and VGGT for 3D, and vision-language models for documents, plus models that connect vision to action in robots.
Related
- AI Algorithms for Image Recognition, the companion guide on classification, detection and segmentation
- AI in Agriculture, on computer-vision spot spraying, agricultural drones and farm robots
- AI in Logistics, on driverless trucks, delivery drones and warehouse robots
- Computer vision, object detection, image segmentation and NeRF in the glossary
- How Transformer Attention Actually Works, the mechanism inside Vision Transformers, VGGT and V-JEPA 2
- PyTorch and TensorFlow, the frameworks most of these models are built in