AI Algorithms for Image Recognition: From CNNs to Vision Transformers, YOLO and SAM
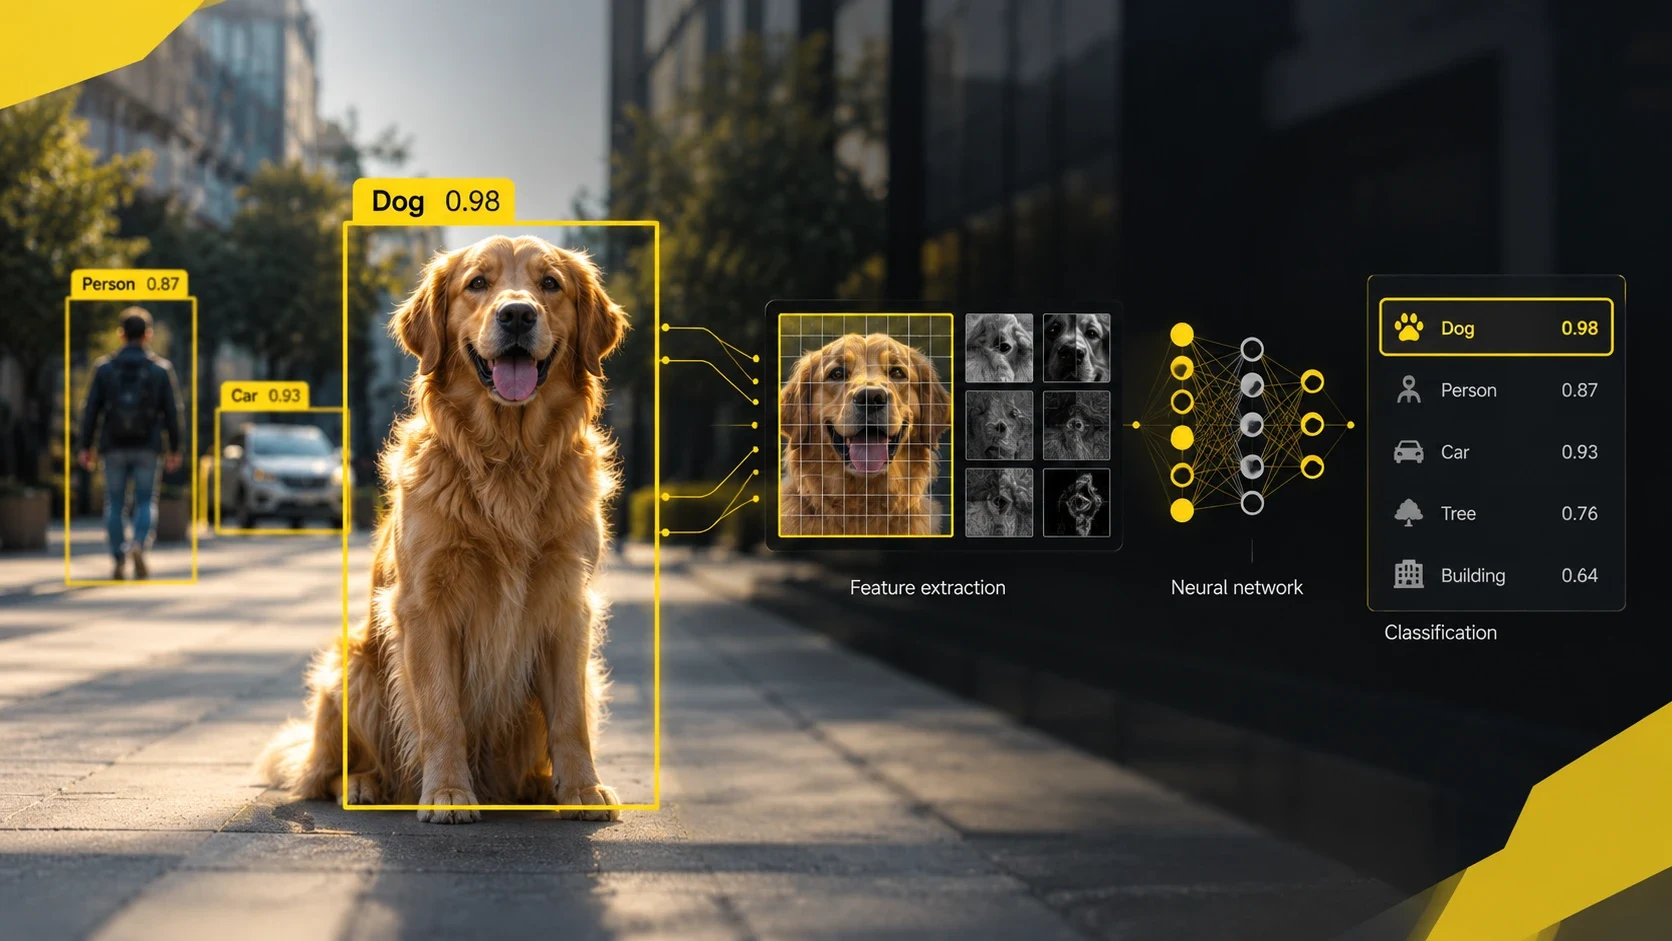
Image recognition is the ability of software to identify what is in an image or video frame: which objects are present, where they are, and sometimes exactly which pixels belong to each one. It is the core task of computer vision, and it runs everything from phone photo search and factory inspection to radiology software and self-driving cars.
The algorithms behind it have changed completely in a decade. Convolutional neural networks (CNNs) took over around 2012. Since 2020, transformers have joined them, then models trained on image-text pairs, and finally general-purpose multimodal models that answer questions about any picture. This guide walks through each family, what problem it solved, and the numbers behind it.
The tasks: what “recognition” actually means
“Image recognition” covers several tasks, and each has its own algorithms:
| Task | Question it answers | Typical models today |
|---|---|---|
| Image classification | What is in this image? | ResNet, ConvNeXt, Vision Transformer, CLIP |
| Object detection | What objects are here, and where? (boxes) | YOLO26, RT-DETR, Co-DETR |
| Image segmentation | Which exact pixels belong to each object? | Mask R-CNN, SAM 2 and SAM 3 |
| Facial recognition | Is this the same person as in another photo? | Specialized face-embedding networks |
| Visual question answering | Answer any question about the image | Multimodal LLMs (GPT, Gemini, Claude) |
A practical system often chains these: a detector finds a car, a segmentation model outlines it, a classifier reads the make, and optical character recognition reads the number plate.
How a CNN recognizes an image
A convolutional neural network treats an image as a grid of pixel values and passes small filters (kernels) across it. Each filter responds to a simple pattern, such as an edge at a certain angle or a patch of color. Early layers detect edges and textures; deeper layers combine them into parts (an eye, a wheel) and then whole objects. Pooling layers shrink the feature maps so later layers see a wider area, and a final layer turns the features into class scores, usually through a softmax.
The filters are not designed by hand. They are learned from labeled examples through backpropagation and gradient descent. That is why the field depended so heavily on one large labeled dataset.
The ImageNet era: 2012 to 2015
ImageNet now indexes more than 14 million images. Its annual competition, ILSVRC, used a subset of about 1.2 million training images in 1,000 classes, and scored models by top-5 error: the share of images where the correct label is not among the model’s five best guesses.
| Year | Model | Top-5 error | What changed |
|---|---|---|---|
| 2012 | AlexNet | 15.3% (runner-up: 26.2%) | Deep CNN trained on GPUs; 60 million parameters |
| 2014 | VGG | 7.3% | 16–19 layers of small 3×3 filters |
| 2014 | GoogLeNet | 6.67% | 22 layers with “Inception” modules |
| 2015 | ResNet | 3.57% | Up to 152 layers via residual (skip) connections |
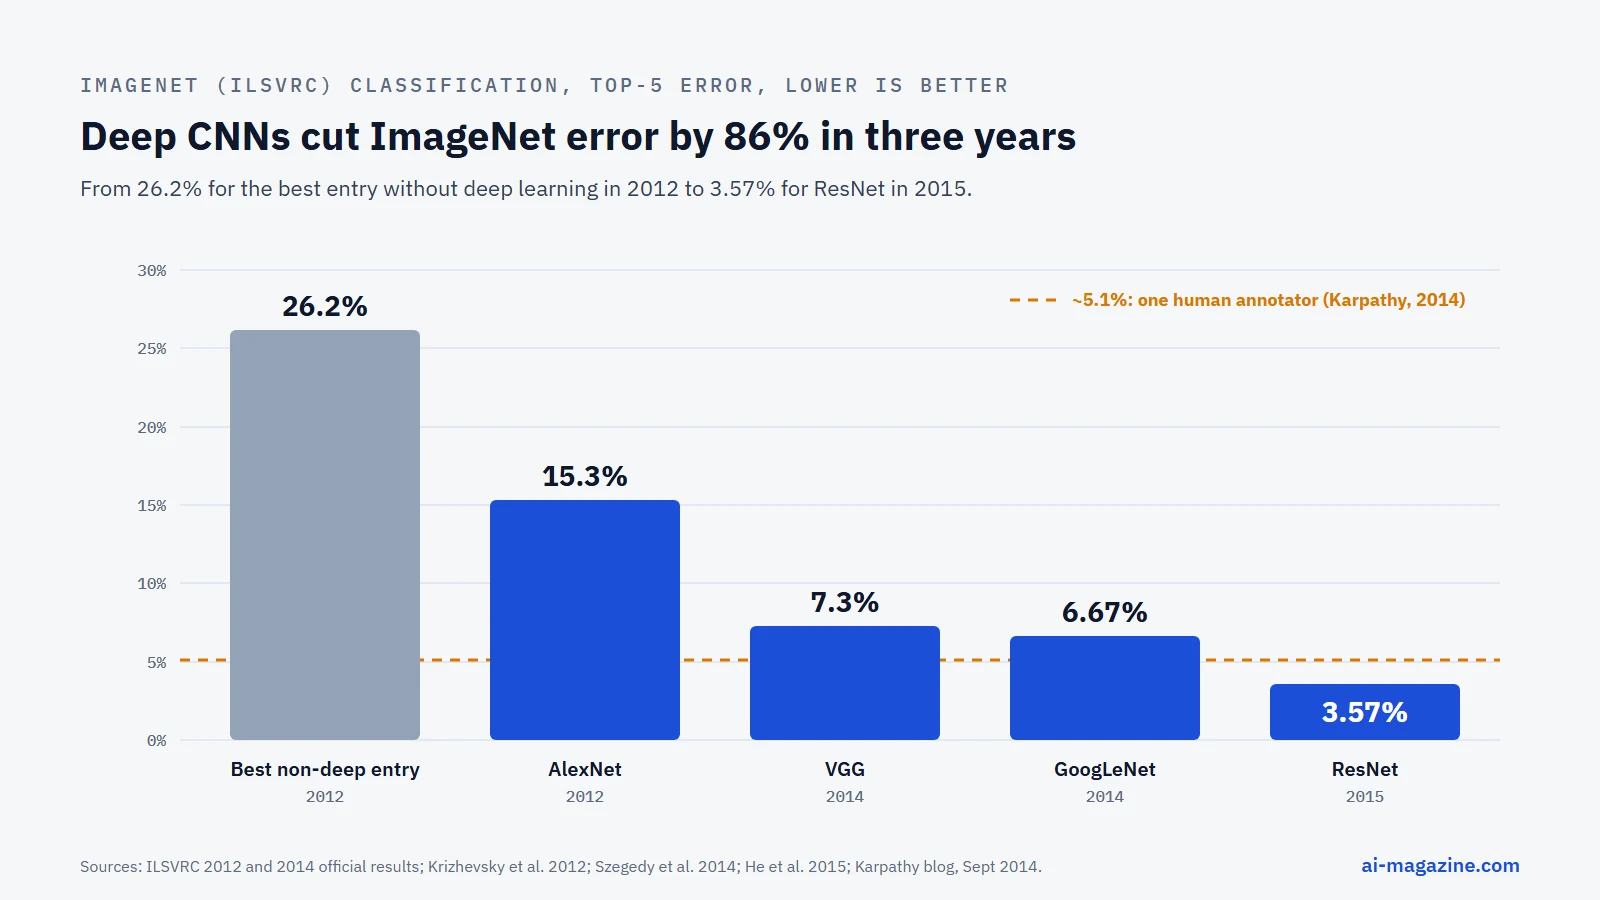
AlexNet’s 11-point lead in 2012 is usually treated as the start of the deep learning era. The often-quoted “human error of 5.1%” comes from Andrej Karpathy, who labeled about 1,500 test images himself in 2014. It is one expert’s estimate, not a universal human baseline, and Karpathy himself warned that “human accuracy is not a point”. Even so, by 2015 ResNet was below it on this benchmark.
Vision transformers: 2020 onward
In October 2020, Google researchers led by Alexey Dosovitskiy published “An Image is Worth 16x16 Words”. The Vision Transformer (ViT) cuts an image into patches, treats each patch like a word token, and processes them with a standard transformer and its attention mechanism, with no convolutions at all.
The paper’s key finding was about data. On mid-sized datasets, ViT scored “a few percentage points below ResNets of comparable size”, because transformers “lack some of the inductive biases inherent to CNNs”, the built-in assumption that nearby pixels matter together. With enough data the gap reversed: pre-trained on Google’s internal JFT-300M set of 303 million images, ViT-H/14 reached 88.55% top-1 accuracy on ImageNet. In the authors’ words, “large scale training trumps inductive bias”.
CNNs did not disappear. In 2022, Meta and UC Berkeley’s ConvNeXt modernized the ResNet design with transformer-era training tricks and reached 87.8% top-1, showing that pure ConvNets “compete favorably with Transformers in terms of accuracy and scalability”. Today both families are in production, often mixed.
Learning without hand labels: CLIP and DINO
Labeling millions of images is expensive. Two approaches removed that bottleneck.
CLIP (OpenAI, 2021) learned from 400 million image-text pairs collected from the internet, matching images to their captions instead of to fixed class labels. That makes it a zero-shot classifier: you describe the classes in words. Without using any of ImageNet’s 1.28 million training examples, CLIP matched the original ResNet-50 at 76.2% top-1 accuracy. CLIP-style encoders now sit inside many image generators and multimodal models.
DINOv2 (Meta, April 2023) used self-supervised learning, with no labels or captions at all, on a curated set of 142 million images. DINOv3 (Meta, August 2025) scaled this to a 7-billion-parameter model trained on 1.7 billion images, and Meta reports that “for the first time, a single frozen vision backbone outperforms specialized solutions on multiple long-standing dense prediction tasks”. These general-purpose backbones are increasingly the starting point for new vision systems, which are then adapted with small amounts of labeled data through transfer learning.
Object detection: from R-CNN to YOLO26
Detection adds location: a box around each object, plus its class.
- R-CNN (2013) ran a CNN on about 2,000 candidate regions per image and improved the PASCAL VOC benchmark by “more than 30% relative to the previous best result”, but it was slow.
- Faster R-CNN (2015) let the network propose its own regions and reached about 5 frames per second on a GPU.
- YOLO (“You Only Look Once”, 2015) treated detection as a single regression problem over the whole image. It ran at 45 frames per second, fast enough for live video, and its successors became the default for real-time detection.
- DETR (Facebook AI, 2020) applied transformers to detection and removed hand-designed steps such as non-maximum suppression, matching a well-tuned Faster R-CNN on the COCO benchmark.
- RT-DETR (Baidu, 2023) made transformer detection real-time: 53.1% AP on COCO at 108 frames per second on an NVIDIA T4 GPU.
The current Ultralytics release is YOLO26 (January 2026), which, like DETR, drops non-maximum suppression. Its official COCO validation scores:
| Model | COCO mAP 50–95 | Latency (T4, TensorRT) | Parameters |
|---|---|---|---|
| YOLO26n | 40.9 | 1.7 ms | 2.4M |
| YOLO26s | 48.6 | 2.5 ms | 9.5M |
| YOLO26m | 53.1 | 4.7 ms | 20.4M |
| YOLO26l | 55.0 | 6.2 ms | 24.8M |
| YOLO26x | 57.5 | 11.8 ms | 55.7M |
For comparison, YOLO11 (September 2024) scored 39.5 to 54.7 across the same five sizes. Large, slow research detectors go further: Co-DETR reported 66.0% AP on COCO test-dev in 2023. That figure is not directly comparable with real-time models measured on a different split.
Segmentation: Mask R-CNN to Segment Anything
Segmentation labels individual pixels. Mask R-CNN (2017) added a mask-predicting branch to Faster R-CNN and became the standard for instance segmentation.
Meta’s Segment Anything series changed the task from “segment these 80 classes” to “segment whatever I point at”:
- SAM (April 2023) was trained on SA-1B, a dataset of more than 1 billion masks on 11 million images. Given a click or a box, it outlines the object, including object types it never saw labeled.
- SAM 2 (July 2024) extended this to video, tracking an object across frames. Meta reports it is more accurate than SAM on images and 6 times faster.
- SAM 3 (November 2025) added “promptable concept segmentation”: type a short phrase such as “yellow school bus” and it finds and outlines every matching instance. The paper reports it “doubles the accuracy of existing systems” on this task. SAM 3.1 (March 2026) doubled video speed from 16 to 32 frames per second on an H100.
Multimodal models: recognition as conversation
The newest recognizers are not dedicated vision models. Large language models with a vision encoder, starting publicly with GPT-4V in September 2023, can describe an image, read text in it, compare two photos or answer arbitrary questions about it. Under the hood they combine a vision encoder (often CLIP-like or ViT-based) with a large language model. See multimodal learning.
Progress is measured on harder benchmarks than ImageNet. MMMU contains 11,500 college-level questions that require understanding diagrams, charts and images. At launch in November 2023, GPT-4V scored 56%. On the official leaderboard, the best reported validation score is now 85.4% (GPT-5.1), close to the 88.6% of the strongest human experts. Most leaderboard entries are self-reported by the model developers.
These models are flexible but slower and costlier per image than a YOLO-class detector, and they cannot yet give the pixel-exact boxes or masks that industrial systems need.
Which algorithm for which job
| You need | Good starting point | Why |
|---|---|---|
| Real-time detection on a camera or edge device | YOLO26 (n or s size) | Millisecond latency, small models |
| Highest detection accuracy, speed not critical | Transformer detectors (DETR family) | Best reported COCO scores |
| Classifying images into your own categories | Fine-tuned ConvNeXt, ViT or DINOv3 backbone | Strong features, little labeled data needed |
| Classes that change often, no labels | CLIP-style zero-shot classification | Classes defined in plain text |
| Cutting out objects precisely, or tracking in video | SAM 2 / SAM 3 | Promptable, works on unseen objects |
| Open-ended questions, reading documents and charts | Multimodal LLM | Flexible, but slower and pricier |
Where image recognition is used
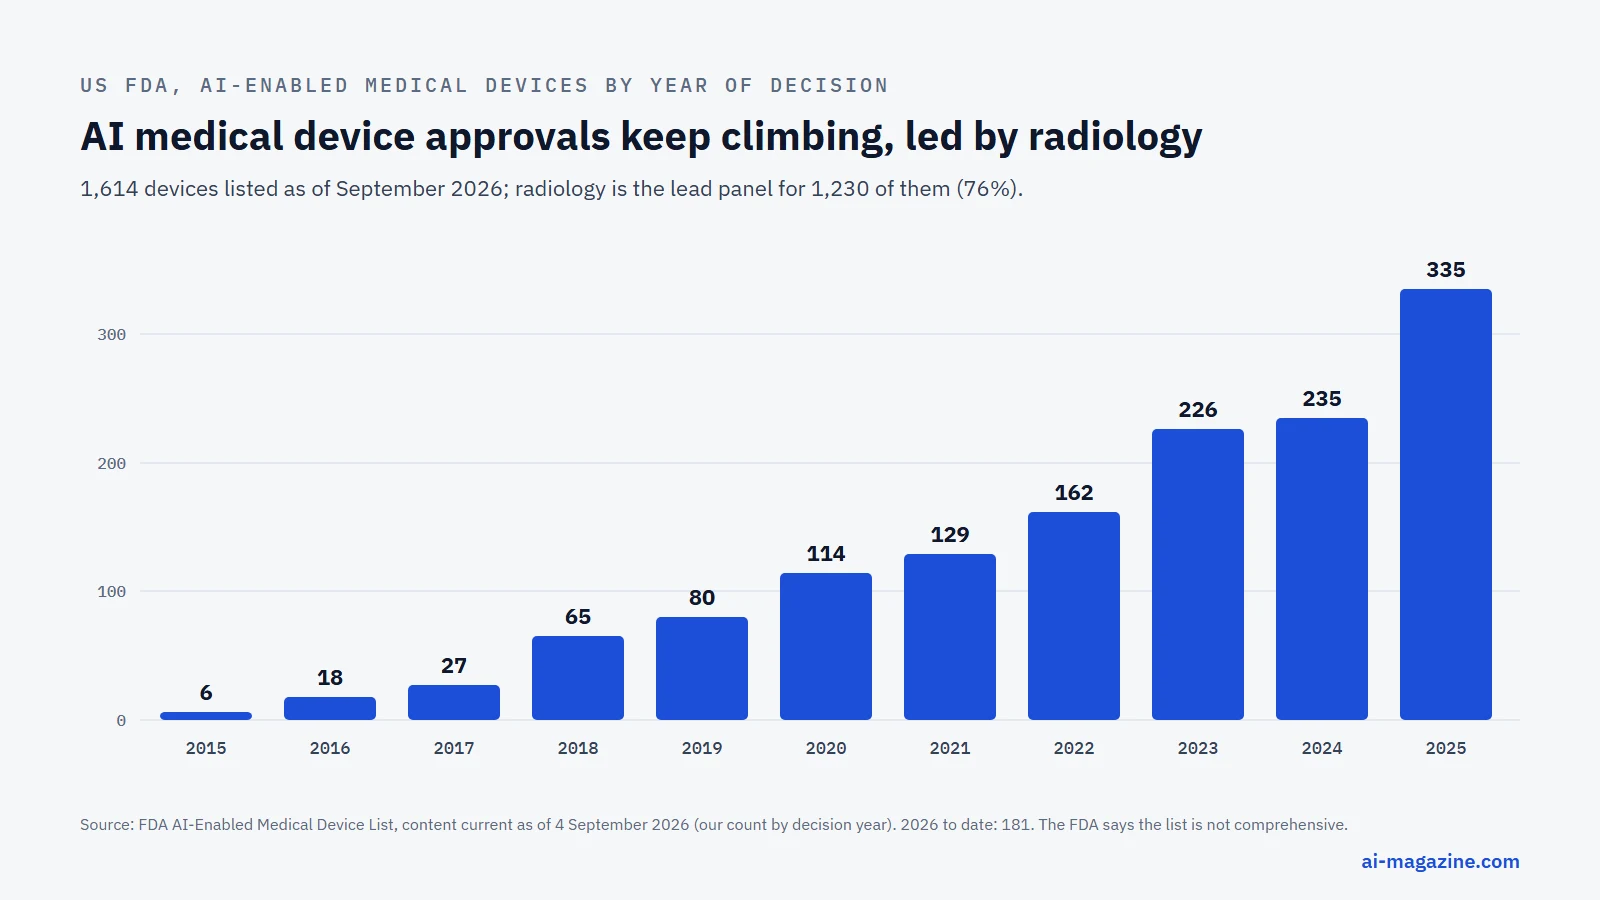
- Medicine. The US FDA’s list of AI-enabled medical devices contained 1,614 devices as of September 2026, and radiology was the lead review panel for 1,230 of them (76%). Authorizations are accelerating: 226 in 2023, 235 in 2024 and 335 in 2025. The FDA notes the list is not comprehensive.
- Face recognition. In NIST’s ongoing Face Recognition Technology Evaluation (summary updated September 2026), the best algorithms matching visa photos to border photos miss only 0.14% of genuine matches while accepting just one impostor in a million comparisons. NIST has evaluated more than 1,400 algorithms since 2017.
- Regulation. Since 2 February 2025, the EU AI Act (Article 5) has banned AI systems that build facial recognition databases through “untargeted scraping of facial images from the internet or CCTV footage”, and has prohibited real-time remote biometric identification in public spaces for law enforcement except in narrow, listed cases such as searching for abduction victims or preventing an imminent terrorist threat.
- Industry, retail, agriculture and mapping. Defect inspection on production lines, shelf monitoring, crop and pest detection from drones, and land-cover mapping from satellite imagery all rely on the detection and segmentation models above.
Where image recognition fails
High benchmark scores hide well-documented weaknesses:
- Adversarial examples. In 2013, Szegedy and colleagues showed that an “imperceptible perturbation” can make a network misclassify an image. In Goodfellow’s famous follow-up, a picture GoogLeNet labeled “panda” with 57.7% confidence was relabeled “gibbon” with 99.3% confidence after noise invisible to humans was added.
- Demographic bias. The 2018 “Gender Shades” study by Joy Buolamwini and Timnit Gebru found commercial gender-classification systems had error rates of up to 34.7% for darker-skinned women, against at most 0.8% for lighter-skinned men. See bias.
- Distribution shift. When researchers built a fresh ImageNet test set in 2019 following the original process, the accuracy of existing models dropped by 11–14%. Models trained on one distribution of photos degrade on slightly different ones, a version of data drift.
- Benchmark saturation. The most cited fine-tuned ImageNet result is about 91% top-1 (Google’s CoCa, 2022), and remaining errors include ambiguous or wrongly labeled images. The field has moved on to harder tests such as COCO for detection and MMMU for multimodal reasoning.
Frequently asked questions
What algorithm is used for image recognition?
There is no single one. Convolutional neural networks (ResNet, ConvNeXt) and Vision Transformers dominate classification; YOLO and DETR-style models handle object detection; Mask R-CNN and Meta’s Segment Anything models handle segmentation; and multimodal LLMs answer open-ended questions about images.
Is a CNN or a Vision Transformer better for image recognition?
It depends on data and constraints. Vision Transformers outperform CNNs when pre-trained on very large datasets, while modern CNNs such as ConvNeXt remain competitive and are often more efficient on small devices. Many current systems combine both.
What is the difference between image recognition and object detection?
Image recognition is the umbrella term. Image classification says what is in a picture overall; object detection also locates each object with a bounding box; segmentation outlines its exact pixels.
What is the latest YOLO version?
As of October 2026, the latest released Ultralytics model is YOLO26, from January 2026, with YOLO27 announced but not yet released.
How accurate is AI image recognition?
On ImageNet, top models exceed 90% top-1 accuracy, and top-5 error fell below one expert human’s estimate back in 2015. Accuracy drops on images that differ from the training data, on adversarially altered images and, for some systems, on under-represented groups of people.
Related
- Computer vision, image recognition, object detection and image segmentation in the glossary
- How Transformer Attention Actually Works, the mechanism behind Vision Transformers
- PyTorch and TensorFlow, the frameworks most of these models are built and trained in
- Convolutional neural networks and ImageNet in the glossary