AI glossary
Small Language Models (SLMs): What Counts as Small, Examples, and What Fits on Your Device
A small language model (SLM) is a language model with few enough parameters to run on ordinary hardware, such as a phone, a laptop or a single modest server, instead of a cluster of data-centre GPUs. In practice that usually means somewhere between a hundred million and about ten billion parameters, but there is no agreed cut-off, and the line keeps moving as hardware improves.
Small models trade breadth for cost, speed and control. They answer quickly, can work offline, keep data on the device, and cost far less per answer. They know less about the world, reason less reliably on hard problems, and can lose accuracy when they are compressed. Whether that trade is worth it depends on the task, which is what this page is about.
Below: the competing definitions, the main small models of 2026, how models are made small, where they hold up against large language models and where they break, what fits on which device, and our own analysis of which model sizes people actually download from Hugging Face.
Small language models at a glance
| Question | Short answer |
|---|---|
| How small is “small”? | No standard. IBM says a few million to a few billion parameters; a Microsoft blog and an NVIDIA paper put the line at about 10 billion |
| Examples in 2026 | Gemma 4 E2B and E4B, Qwen3.5 0.8B to 9B, Phi-4-mini, Llama 3.2 1B and 3B, Ministral 3, SmolLM3, Granite 4.2, Apple’s 3B on-device model |
| What do they do well? | Narrow, well-defined tasks: classification, extraction, short summaries, simple tool calls, on-device assistants |
| Where do they struggle? | Hard reasoning, long documents, factual recall; many also fail basic safety tests |
| How much memory? | About half a byte per parameter at 4-bit precision: a 4B model needs roughly 2 GB for its weights, plus working memory |
| What do people download? | In our analysis of 688 million Hugging Face downloads, 27% went to models under 4B parameters. For models uploaded in 2026 the share was 11% |
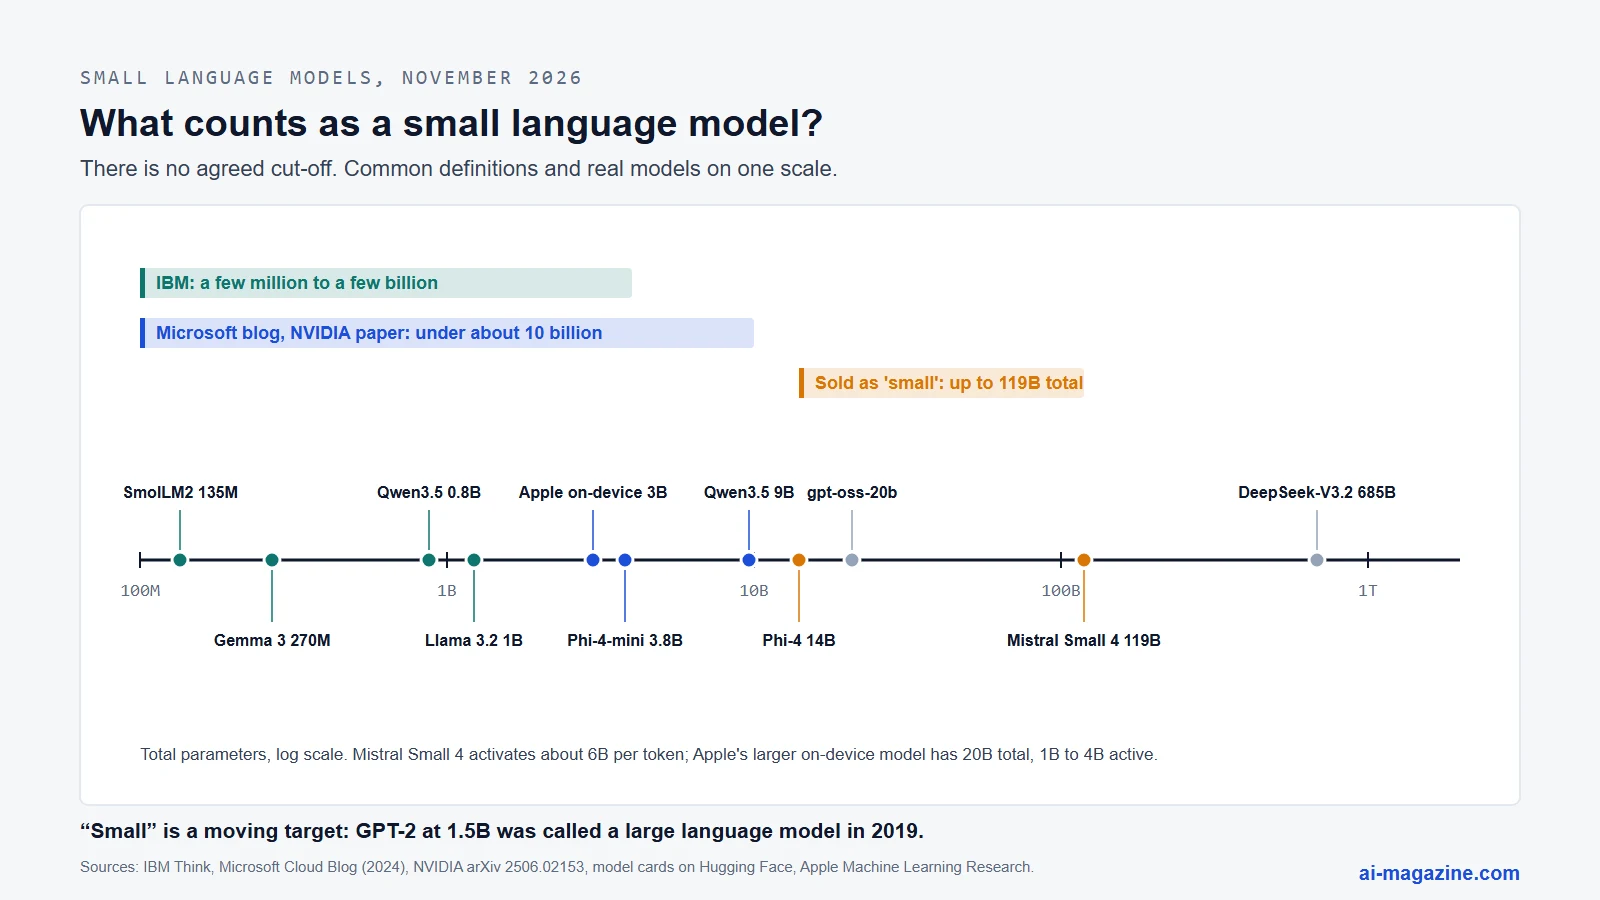
What counts as a small language model?
Every definition you will find is either a rough parameter range or a description of what the model can run on.
- IBM describes SLMs as having a few million to a few billion parameters, against hundreds of billions or trillions for large models.
- Microsoft wrote in a 2024 blog post that SLMs are “typically” sized “just under 10 billion parameters”. Its own Azure glossary says an SLM “might only contain a few hundred million”, so even one company’s pages differ by more than ten times.
- NVIDIA and Georgia Tech researchers, in the paper Small Language Models are the Future of Agentic AI, define an SLM by function: a model that fits on a common consumer device and answers one user’s requests fast enough to be practical. They say that in 2025 they were comfortable calling most models below 10 billion parameters small, while stressing this is not a hard line.
- A 2024 survey of small language models declines to set any cut-off, pointing out that GPT-2, called a large language model in 2019 at 1.5 billion parameters, is smaller than many models now called small.
Three things make the label slippery:
Total, active and “effective” parameters differ. A mixture-of-experts model stores many parameters but uses only some of them for each token. Mistral Small 4 has 119 billion parameters in total and about 6 billion active. Google counts Gemma 4 E2B as 2.3 billion “effective” parameters, 5.1 billion including embeddings. Apple’s larger on-device model has 20 billion parameters in total but 1 to 4 billion active per request. Memory usually follows the total, though Apple keeps its full weights in flash and loads only the needed experts into DRAM; speed follows the active count more closely.
Product tiers are not parameter counts. Names like Haiku, mini, Flash-Lite and Nano describe a price and speed tier. Anthropic and Google publish prices for these models but not their sizes, so calling Claude Haiku or a GPT “mini” model an SLM is a guess. IBM’s own SLM explainer lists GPT-4o mini as an example, although OpenAI has not published its size.
Small is not the same as open. Gemini Nano and Apple’s on-device model are small but closed. Some open-weight models are enormous: open weights describe the licence, not the size.
A workable definition for 2026: a model whose full weights fit comfortably in the memory of a phone, a laptop or one consumer GPU, which today means up to roughly 10 billion total parameters at 4-bit precision, or up to roughly 4 billion if it has to run on a phone.
Small language model examples in 2026
| Model | Size | Licence | Released | Notes |
|---|---|---|---|---|
| SmolLM2 and SmolLM3 (Hugging Face) | 135M, 360M, 1.7B; 3B | Open | 2024; July 2025 | SmolLM3’s full training recipe is published: about 11.2 trillion tokens on 384 H100 GPUs for 24 days |
| Gemma 3 270M (Google) | 270M | Gemma terms | August 2025 | Built for fine-tuning to one task |
| Gemma 4 E2B and E4B (Google) | 2.3B and 4.5B effective | Apache 2.0 | April 2026 | Text, image and audio input, 128K context |
| Qwen3.5 small models (Alibaba) | 0.8B, 2B, 4B, 9B | Apache 2.0 | February 2026 | Text, image and video input, 262K context. The newer Qwen3.6 and 3.8 lines start at 27B |
| Llama 3.2 (Meta) | 1.23B, 3.21B | Llama community licence | September 2024 | We found no smaller Llama released since |
| Phi-4-mini and Phi-4 (Microsoft) | 3.8B; 14B | MIT | February 2025; December 2024 | Trained heavily on synthetic data |
| Ministral 3 (Mistral) | 3B, 8B, 14B | Apache 2.0 | December 2025 | Base, instruct and reasoning versions |
| Granite 4.2 (IBM) | 3B, 8B | Apache 2.0 | August 2026 | Granite 4.0 Nano went down to 350M in October 2025 |
| Apple Foundation Models 3 Core | 3B | Proprietary | June 2026 | Runs Apple Intelligence on the device |
| Gemini Nano (Google) | Not published | Proprietary | Runs on Android phones and in Chrome | |
| Mu (Microsoft) | About 330M | Not released | June 2025 | Powers the agent in Windows Settings |
On Windows, Microsoft says its built-in Phi Silica model is being replaced by a model called Aion Instruct, rolling out to Insiders in November 2026 and to everyone in January 2027. Microsoft has not published Aion Instruct’s size. For a wider look at open models of every size, see our guide to the best open-source LLMs.
How models are made small
Four techniques do most of the work, usually in combination. Each has a measurable cost.
Knowledge distillation. A small “student” model is trained to imitate a large “teacher”. DistilBERT was 40% smaller and 60% faster than BERT while keeping 97% of its language-understanding scores. Distillation of reasoning models shows how much is lost as the student shrinks. On the AIME 2024 maths test, DeepSeek reported 79.8 for its full R1 model, 72.6 for a 32B distilled version, 55.5 for 7B and 28.9 for 1.5B. More in our entry on knowledge distillation.
Quantization. Weights are stored with fewer bits, for example 4 instead of 16, which cuts the weights by up to four times in theory and about two to three times in real model files. At 8 bits the loss is usually small: one large study found FP8 effectively lossless across the Llama 3.1 family. At 4 bits the cost depends on the task. In Meta’s own tests, a SpinQuant 4-bit Llama 3.2 1B lost about 2 points on general knowledge (MMLU) but 9.8 points on tool calling, while a QLoRA 4-bit version lost 0.3 and 2.0. A study of reasoning models found weight-only 4-bit versions within a few points of the original on hard maths, while 3-bit versions dropped by up to about 25 points on the AIME test. A clinical study of five 7B to 8B models found 4-bit versions losing up to 26.8% on some medical tests and, for at least two of the models, refusing unsafe requests less often. See quantization.
Pruning. Unimportant weights or whole layers are removed from a trained model. The Sheared LLaMA project cut a 7B model down to 1.3B and 2.7B using about 3% of the compute needed to train such models from scratch. Clean figures for how much quality pruning costs at large scale are scarce.
Better training data. Microsoft’s Phi line bet on carefully chosen and synthetic “textbook” data. The first model, phi-1, had 1.3 billion parameters, trained for four days on eight GPUs, and solved 50.6% of the HumanEval coding test. Earlier, TinyStories showed that models under 10 million parameters could write coherent short stories when the training data used only words a small child would know. General knowledge is a weak spot, though Microsoft’s table does not tie it to the training data: Phi-4 scores 3.0 on the SimpleQA fact test against 39.4 for GPT-4o in Microsoft’s own table.
SLM vs LLM: where small is enough
On some standard tests, today’s small models match or beat mid-sized models from a year or two earlier.
- Mistral says its Ministral 3 14B base model scores 79.4 on MMLU against 81.0 for the 24B model it was derived from, and beats it on the MATH test.
- Google says Gemma 4 E4B beats the previous generation’s 27B model on several tests, including the AIME 2026 maths exam (42.5 against 20.8), though its table lists the 27B scores as run without thinking.
- In a Microsoft case study, a Phi-3 mini model fine-tuned on about 1,000 examples per task reached 95.86% accuracy on an internal supply-chain tool, against 88.22% for GPT-4-turbo with ten examples in the prompt. It cost 0.19 cents per query against 42.32 cents. The authors stress this is one case.
These are mostly the developers’ own numbers. The Microsoft case suggests that a small model fine-tuned for one narrow job can match or beat a general large model on that job, but it is one case.
Where small models break
Compare sizes within one family and the gaps open on hard problems.
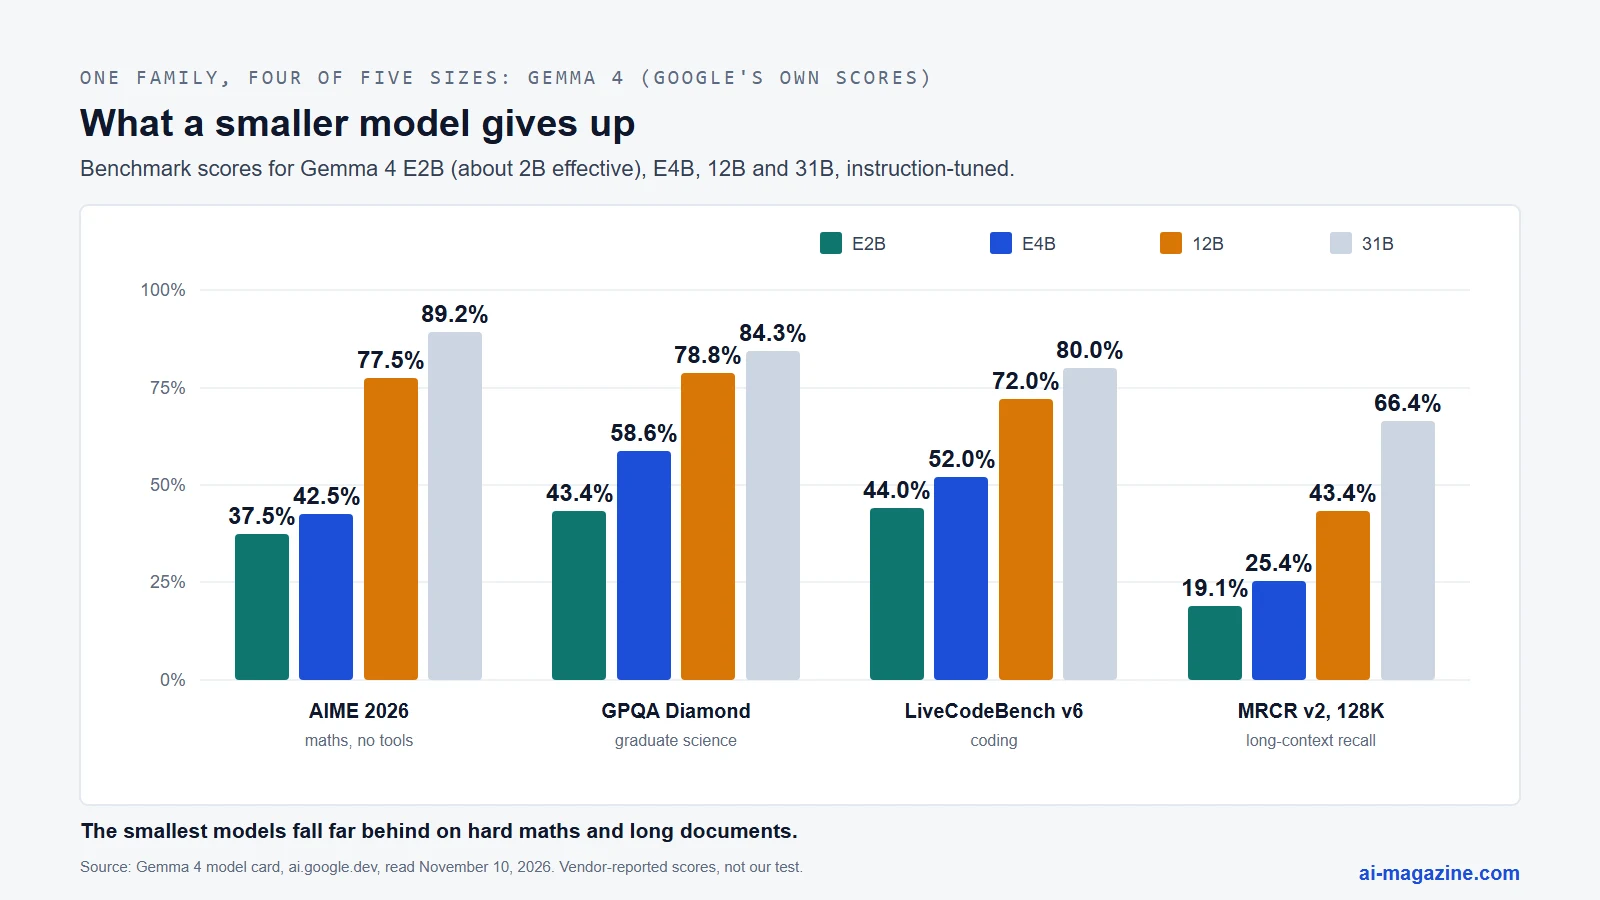
- Hard reasoning. In Google’s numbers, Gemma 4 E2B scores 37.5 on AIME 2026 maths and the 31B model 89.2. On graduate-level science (GPQA Diamond) Alibaba reports 11.9 for Qwen3.5 0.8B and 81.7 for the 9B model.
- Long documents. On a test of finding several facts in 128,000 tokens of text, Gemma 4 E2B scores 19.1 and the 31B model 66.4.
- Facts. Small models simply store less. OpenAI’s gpt-oss model card shows the 20B model getting 6.7% of SimpleQA questions right with a 91.4% hallucination rate, against 16.8% and 78.2% for the 120B model. See our article on LLM hallucinations.
Cost and energy
A small model costs less to run per answer, whether you pay a provider or run it yourself.
| Provider | Small model, per million tokens | Large model, per million tokens |
|---|---|---|
| Mistral | Ministral 3 3B: $0.10 input, $0.10 output | Mistral Large 4: $0.70 input, $2.10 output |
| Together AI | Qwen3.5 9B: $0.17 input, $0.25 output | Kimi K3: $3.00 input, $15.00 output |
Prices checked on November 10, 2026. Price is not a pure function of size: Mistral Small 4, with 119 billion total parameters, is listed at $0.15 per million input tokens, below Ministral 3 14B at $0.20.
Energy follows the same direction. In one measurement study, a response from Llama 3 70B used about 17 times as much energy as one from Llama 3 8B, though the two ran on different machines. A UNESCO and UCL report found that small, task-specific models could cut energy use by up to 90% without losing performance on the tasks tested.
Our analysis: which model sizes do people actually download?
Small models get plenty of attention. To see how often they are downloaded, we took the 1,000 most downloaded text-generation models and the 1,000 most downloaded image-and-text models on the Hugging Face Hub on November 11, 2026, removed test and placeholder models, and sorted the remaining 1,922 by size. Together they had 688 million downloads in the previous 30 days.
| Model size | Share of downloads, all models | Share, models uploaded in 2026 |
|---|---|---|
| Under 1B | 16.2% | 2.8% |
| 1B to 4B | 10.7% | 7.8% |
| 4B to 10B | 20.6% | 14.4% |
| 10B to 40B | 36.8% | 52.0% |
| 40B and up | 15.0% | 22.1% |
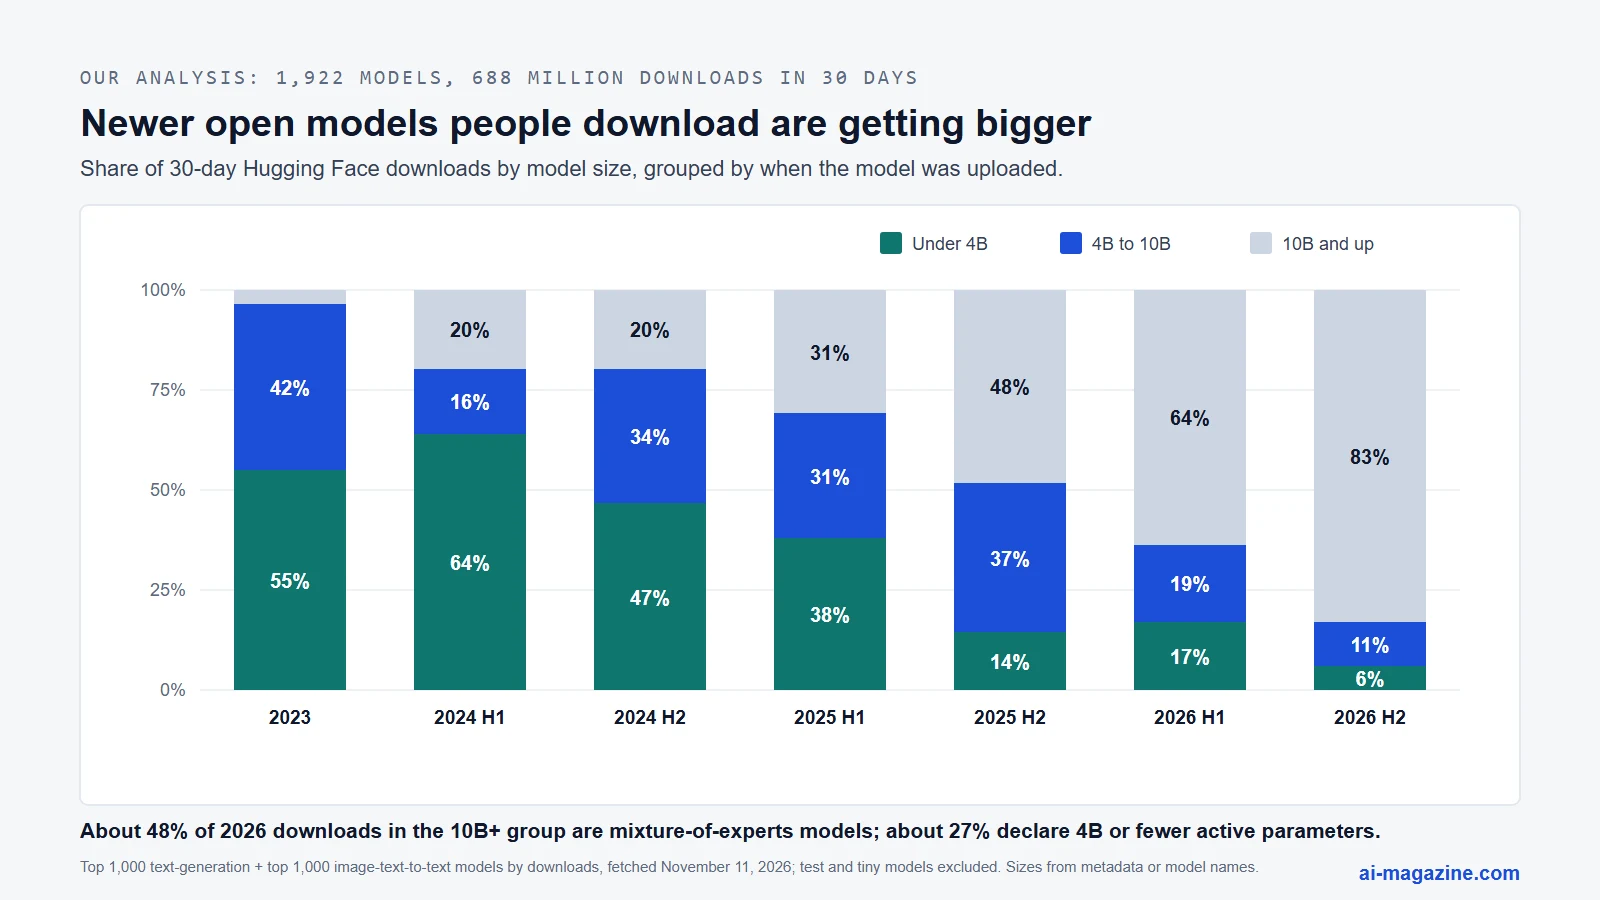
What we found:
- Small models are heavily downloaded, but much of that is old models. Across all 1,922 models, 27% of downloads went to models under 4 billion parameters and 48% to models under 10 billion, the NVIDIA paper’s rough line. Older small models such as GPT-2 are common in tutorials and automated pipelines, which probably inflates their counts.
- New releases people download are bigger. Among models uploaded in 2026, only 11% of downloads went to models under 4B. Just over half of those downloads went to models of 10 to 40 billion parameters, and the download-weighted median size was 27 billion.
- Some of the “large” downloads compute like small models. About 48% of 2026 downloads in the 10B-and-up group were mixture-of-experts models, but only about 27% went to models whose names declare 4 billion active parameters or fewer, such as Qwen3.6 35B-A3B, which activates about 3 billion per token. Those need the memory of a large model but can run closer to the speed of a small one. The rest activate more parameters or state no active count in their names.
- The most downloaded model uploaded since 2025 is small. Qwen3 0.6B had 20.5 million downloads in 30 days, second only to GPT-2 in our list.
One possible reading: small models persist in fixed tasks and pipelines, while newer downloads lean toward larger models. The data cannot show why. It does not record who downloaded a model or on what hardware, the newest Qwen lines start at 27B, so availability shapes the result, and 21% of 2026 downloads went to models of 80B and up, which need more than 40 GB even at 4 bits and are unlikely to be for personal machines. Download counts are a rough proxy for use, as we explain under the method below.
Running a small language model on your own hardware
The first question is memory. A rough rule: the weights take two bytes per parameter at 16-bit precision and about half a byte at 4-bit.
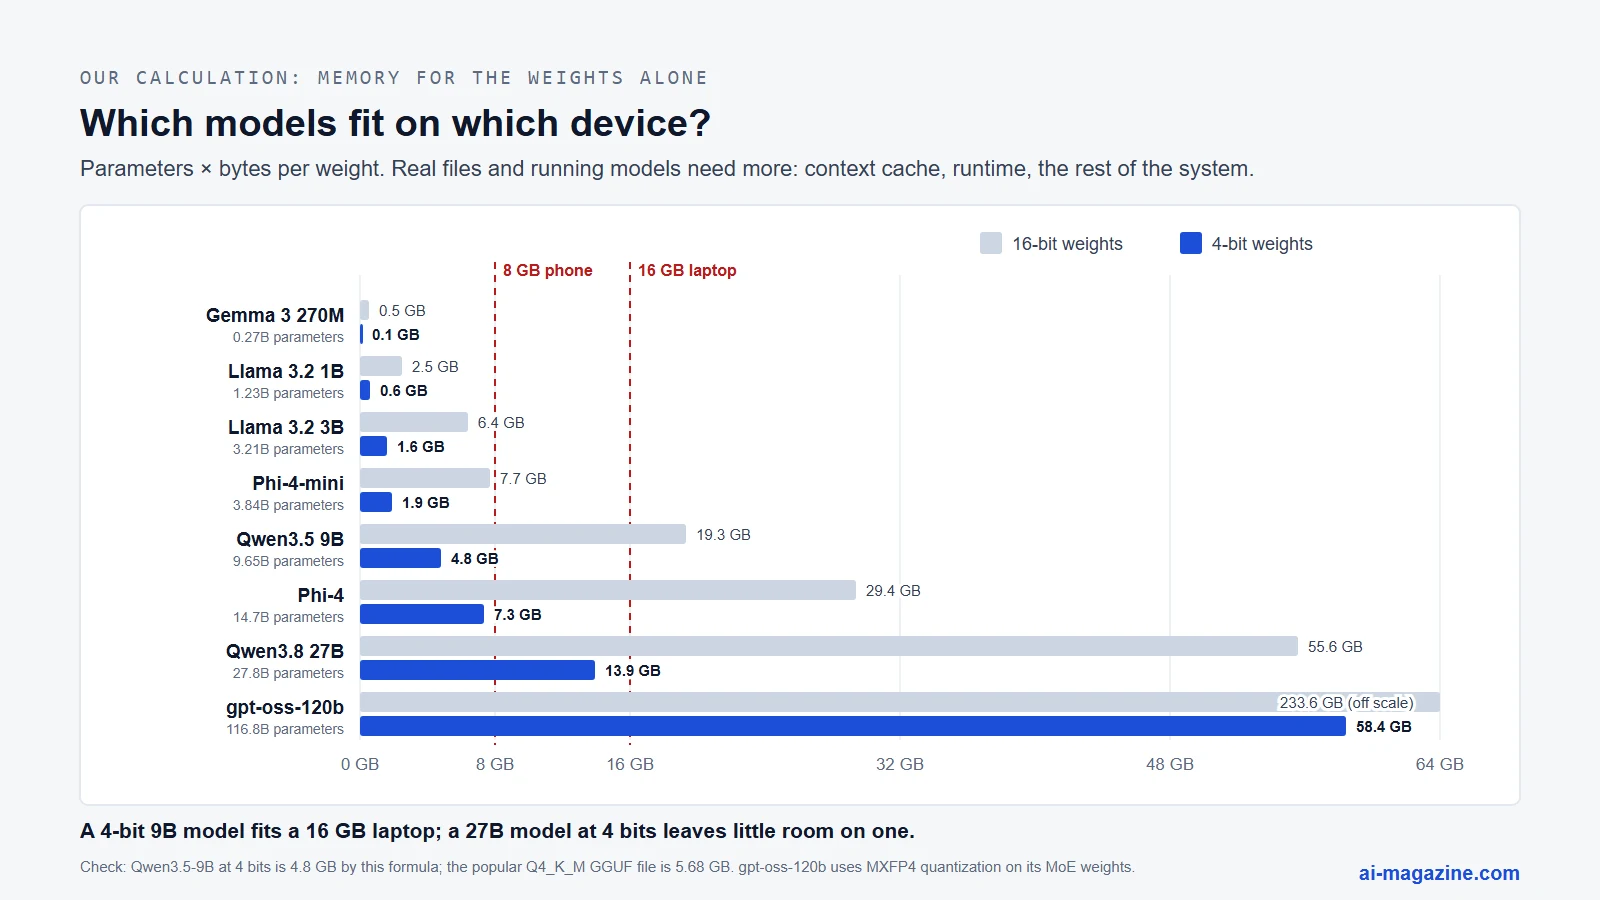
Real use needs more than the weights: the context being processed, the runtime, and the rest of the system. The popular 4-bit file of Qwen3.5 9B is 5.68 GB, against 4.8 GB by our formula, and the image encoder is a separate file of about 0.9 GB. As a guide, a 16 GB laptop runs 4-bit models up to about 9 billion parameters comfortably, and a phone is realistic up to about 4 billion.
Speed depends heavily on the device. Published figures:
| Model | Device | Speed |
|---|---|---|
| Llama 3.2 1B, 4-bit (SpinQuant) | OnePlus 12 phone, CPU | 50.2 tokens per second |
| Llama 3.2 3B, 4-bit (SpinQuant) | OnePlus 12 phone, CPU | 19.7 tokens per second |
| Gemma 4 E2B | iPhone 17 Pro, GPU | 56.5 tokens per second |
| Gemma 4 E2B | Raspberry Pi 5, CPU | 7.6 tokens per second |
| Gemma 4 E4B | MacBook Pro M4 Max, GPU | 101.1 tokens per second |
These are published figures, with the Gemma rows run at a short 2,048-token context. Mid-range phones are much slower.
Small models also ship inside operating systems:
- Apple runs a 3B model on iPhones, iPads and Macs, and says Apple Intelligence needs up to 14 GB of storage on recent devices.
- Google runs Gemini Nano on Android through AICore. Chrome’s built-in AI reportedly downloads a model of about 4 GB and, per Google’s developer docs, needs 22 GB of free disk space and either a GPU with more than 4 GB of memory or 16 GB of RAM and four CPU cores.
- Microsoft requires 16 GB of RAM and a 40 TOPS NPU for Copilot+ PCs, which run its on-device models.
To try one yourself, see our guide on how to run an LLM locally with Ollama. Local models are also an edge model use case: the data never leaves the device.
Real deployments
Most published results come from the companies involved, so treat them as claims.
- Microsoft, internal supply-chain tool. The fine-tuned Phi-3 mini case above: higher accuracy than GPT-4-turbo at a fraction of the cost, with answers in a few seconds instead of one to two minutes.
- Kakao Mobility. Uses Gemini Nano on the phone to extract delivery addresses, with a cloud model as fallback. Google’s write-up reports order completion time down 24%, with no accuracy figures.
- SK Telecom. Fine-tuned a 4B Gemma model for Korean and English content moderation. Its partner Adaptive ML reports a Korean score of 0.80, equal to GPT-4.1 and above GPT-4o’s 0.78.
- Windows Settings. Microsoft’s 330M Mu model turns requests into settings changes in under half a second, by Microsoft’s account.
- Checkr. The background-check company reportedly replaced GPT-4 with a fine-tuned 8B Llama model on its hardest cases, at 90% accuracy, five times lower cost and about 30 times the speed, according to ZenML’s summary of the case. Computerworld reports 85% on the hardest data. The original case study was not accessible to us.
Small models in AI agents and routing
The NVIDIA paper argues that most steps in an AI agent are narrow and repetitive, so a small model can handle them. Its authors write that serving a 7B model is 10 to 30 times cheaper in latency, energy and compute than a 70B to 175B model. They estimate that about 60% of model calls in the MetaGPT agent framework, 40% in Open Operator and 70% in Cradle could be handled by specialised small models. These are estimates in a position paper, and NVIDIA sells both the chips and a family of small models.
A common pattern is routing: send each request to a small model first and pass only the hard ones to a large model.
- RouteLLM cut costs by 3.66 times on the MT Bench test while keeping 95% of GPT-4’s quality. Its “small” model, though, was Mixtral 8x7B, far bigger than anything that runs on a phone.
- Hybrid LLM reported up to 40% fewer calls to the large model with no drop in quality.
- Minions, in which a local model works with a cloud model, reported 5.7 times lower cost at 97.9% of the cloud model’s performance.
More on cutting model bills in our guide to reducing LLM API costs.
Limits and risks
Safety under attack. In a study of 59 small models from 15 families, between 135 million and 5 billion parameters, 37.3% were broken by more than half of plainly harmful requests, without any jailbreak trick. Size within that range showed little link to resistance. A small safety filter model roughly halved attack success for most attacks.
Compression can hide problems. Researchers have shown that a model can be built to behave normally at full precision and turn harmful once quantized. Download quantized files from sources you trust.
Weights on the device can be copied. A model shipped inside an app is open to anyone who unpacks the app. Operating-system services such as Android’s AICore run models in an isolated system service, which Google describes as a privacy measure.
Languages. Coverage varies widely. Microsoft says Phi-4 is mostly English and “not intended to support multilingual use”; SmolLM3 covers six languages and Granite 4.2 twelve, while Google claims more than 140 for Gemma 4.
Fine-tuning can weaken safety. One study found that fine-tuning generally raises the success rate of jailbreak attacks, so a tuned small model needs its own safety testing.
How to choose between an SLM and an LLM
A small model is a good fit when:
- The task is narrow and repeated: tagging, routing, extracting fields, short summaries, simple tool calls.
- You can test it on your own data. Benchmarks may not predict how a small model handles your task.
- Data must stay on the device or the app has to work offline.
- Latency or cost per request matters at high volume.
Pick a larger model, or route to one, when the task needs broad knowledge, multi-step reasoning, long documents, or careful handling of risky content. A practical path is to start with a large model, collect real requests and answers, then fine-tune a small model on them (with techniques like LoRA) and keep the large one for the cases the small one gets wrong.
Common myths
“Small models are just worse large models.” Fine-tuned for one task, small models can match general large ones, as the Microsoft and SK Telecom cases show. They are worse at breadth, not necessarily at a specific job.
“Haiku, mini and Flash are small language models.” They are cheaper tiers. Their sizes are not published, so they may or may not be small.
“Small means private.” Only if it runs on your device. A small model called through a cloud API sends your data to the provider like any other.
“4-bit is free.” Usually close for general use, but tool calling, hard reasoning and safety behaviour can drop noticeably, as the studies above show.
“Bigger downloads mean bigger use.” Download counts include automated pipelines and repeated server pulls, so they are a weak measure of real usage.
How we ran the analysis
On November 11, 2026 we fetched the top 1,000 models by 30-day downloads in each of two Hugging Face Hub categories, text-generation and image-text-to-text, through the public API. That gave 2,000 models; we removed 78 whose names matched test, tiny, random, dummy, debug or mock, which also dropped a few real models such as TinyLlama 1.1B. Parameter counts came from the Hub’s safetensors or GGUF metadata, or from the model name when metadata was missing or differed from the name by more than two times (for example, files containing only a small add-on layer of a larger model). GGUF metadata took precedence over safetensors. We corrected three model families by hand and could not size 23 models (0.6% of downloads). Mixture-of-experts models count at their total size, except for 8 small repositories sized from a token in their names; we flagged them by name and by Hub architecture tags. Upload date is the repository’s creation date, so a re-upload of an older model counts as new.
Limits: downloads count requests for a repository’s query files, such as config.json, including HEAD requests, and every GGUF file, so they include automated systems, models uploaded recently get a launch boost, and the analysis covers only the top 1,000 in each category. The size cut-offs matter: Qwen3.5 4B has 4.66B parameters including vision, so a 5B cut-off would give 32% overall and 15% for 2026, against 27% and 11% at 4B, while leaving out OCR and document models would give about 24% and 8%. The direction, newer downloads leaning larger, holds in each case. The memory chart is a calculation, not a measurement. Benchmark figures quoted in this article come from the developers unless stated otherwise; we did not rerun them.
FAQ
What is a small language model?
A language model small enough to run on everyday hardware such as a phone or laptop, usually under about 10 billion parameters. It trades some breadth and reasoning for lower cost, faster answers and the option to run offline.
What is the difference between an SLM and an LLM?
Size and what follows from it. Large models know more and reason better on hard problems; small models are cheaper, faster and can run on a device. There is no fixed parameter line between them.
What are examples of small language models?
Gemma 4 E2B and E4B, Gemma 3 270M, Qwen3.5 0.8B to 9B, Phi-4-mini, Llama 3.2 1B and 3B, Ministral 3, SmolLM3, Granite 4.2, Apple’s on-device model and Gemini Nano.
Can a small language model run without internet?
Yes, if it runs on your device. Once the model file is downloaded, apps such as Ollama or the operating system’s built-in model can answer offline.
How much RAM do I need to run a small language model?
At 4-bit precision, about half a gigabyte per billion parameters for the weights, plus working memory. A 3B or 4B model runs on most 8 GB devices; a 9B model fits on a 16 GB laptop.
Are small language models cheaper?
Usually. Per-token prices for small open models can be ten times or more below large ones, and running one locally has no per-token bill, only the hardware and electricity.